Harness engineering in practice: from issue to PR
For CTOs and engineersHarness and checks · Updated

Filip PapranecFounder, Digitaliko
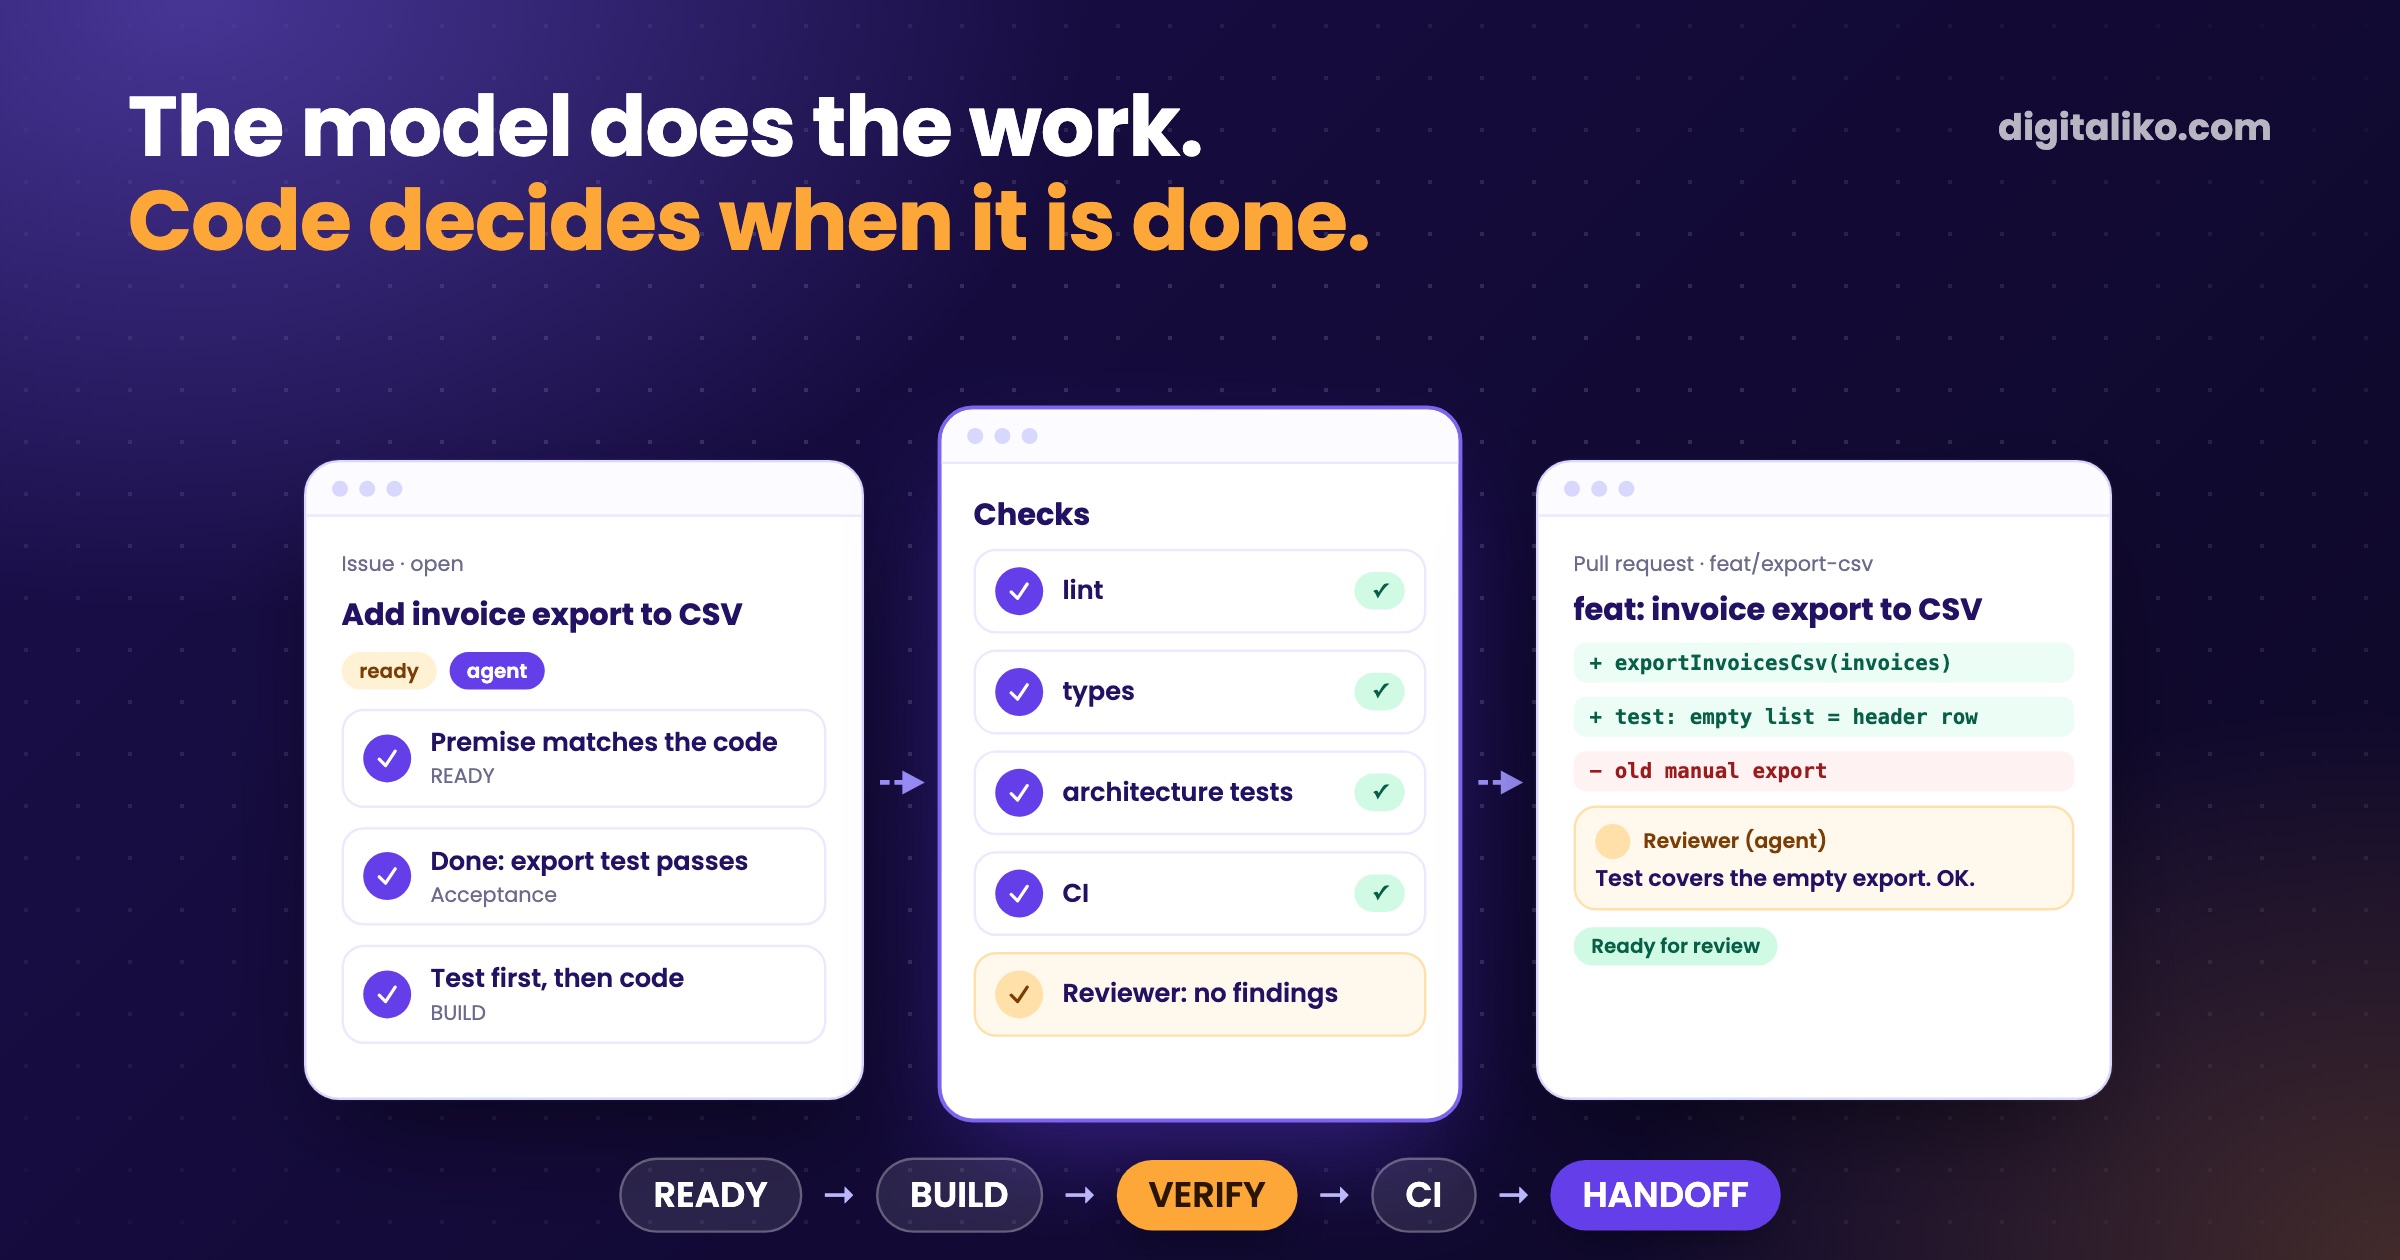
Harness engineering is the code around an AI agent that decides which task it takes, when the work counts as done, and who checks it. The model only does the work. An AI agent that writes code is cheap. An agent whose pull requests your seniors can merge without redoing them is the expensive part, and the harness closes that gap.
We run such a loop every day on our own repositories. AI writes all of our code today, and a senior is accountable for what reaches production. Below is how the loop works, the lines of code that carry it, and what broke along the way.
I put so many obstacles around AI agents that only one path is left for them. The right one.

What does harness engineering mean in practice?
An agent is a model plus its harness. You rent the model. The harness is yours: rules, context, checks, limits and the hand-off to a person. What a harness is made of is in What is an agent harness? Agent = model + harness. This article is the practice: one loop, running every day.
Our one design rule sits at the top of the dispatcher script:
# Deterministic on purpose: code decides WHAT to take and WHEN it is done, models only do the work.
Three things follow from it:
- Code picks the work. A bash dispatcher reads the GitHub issues assigned to the agent, sorted by priority label. No model decides what to start.
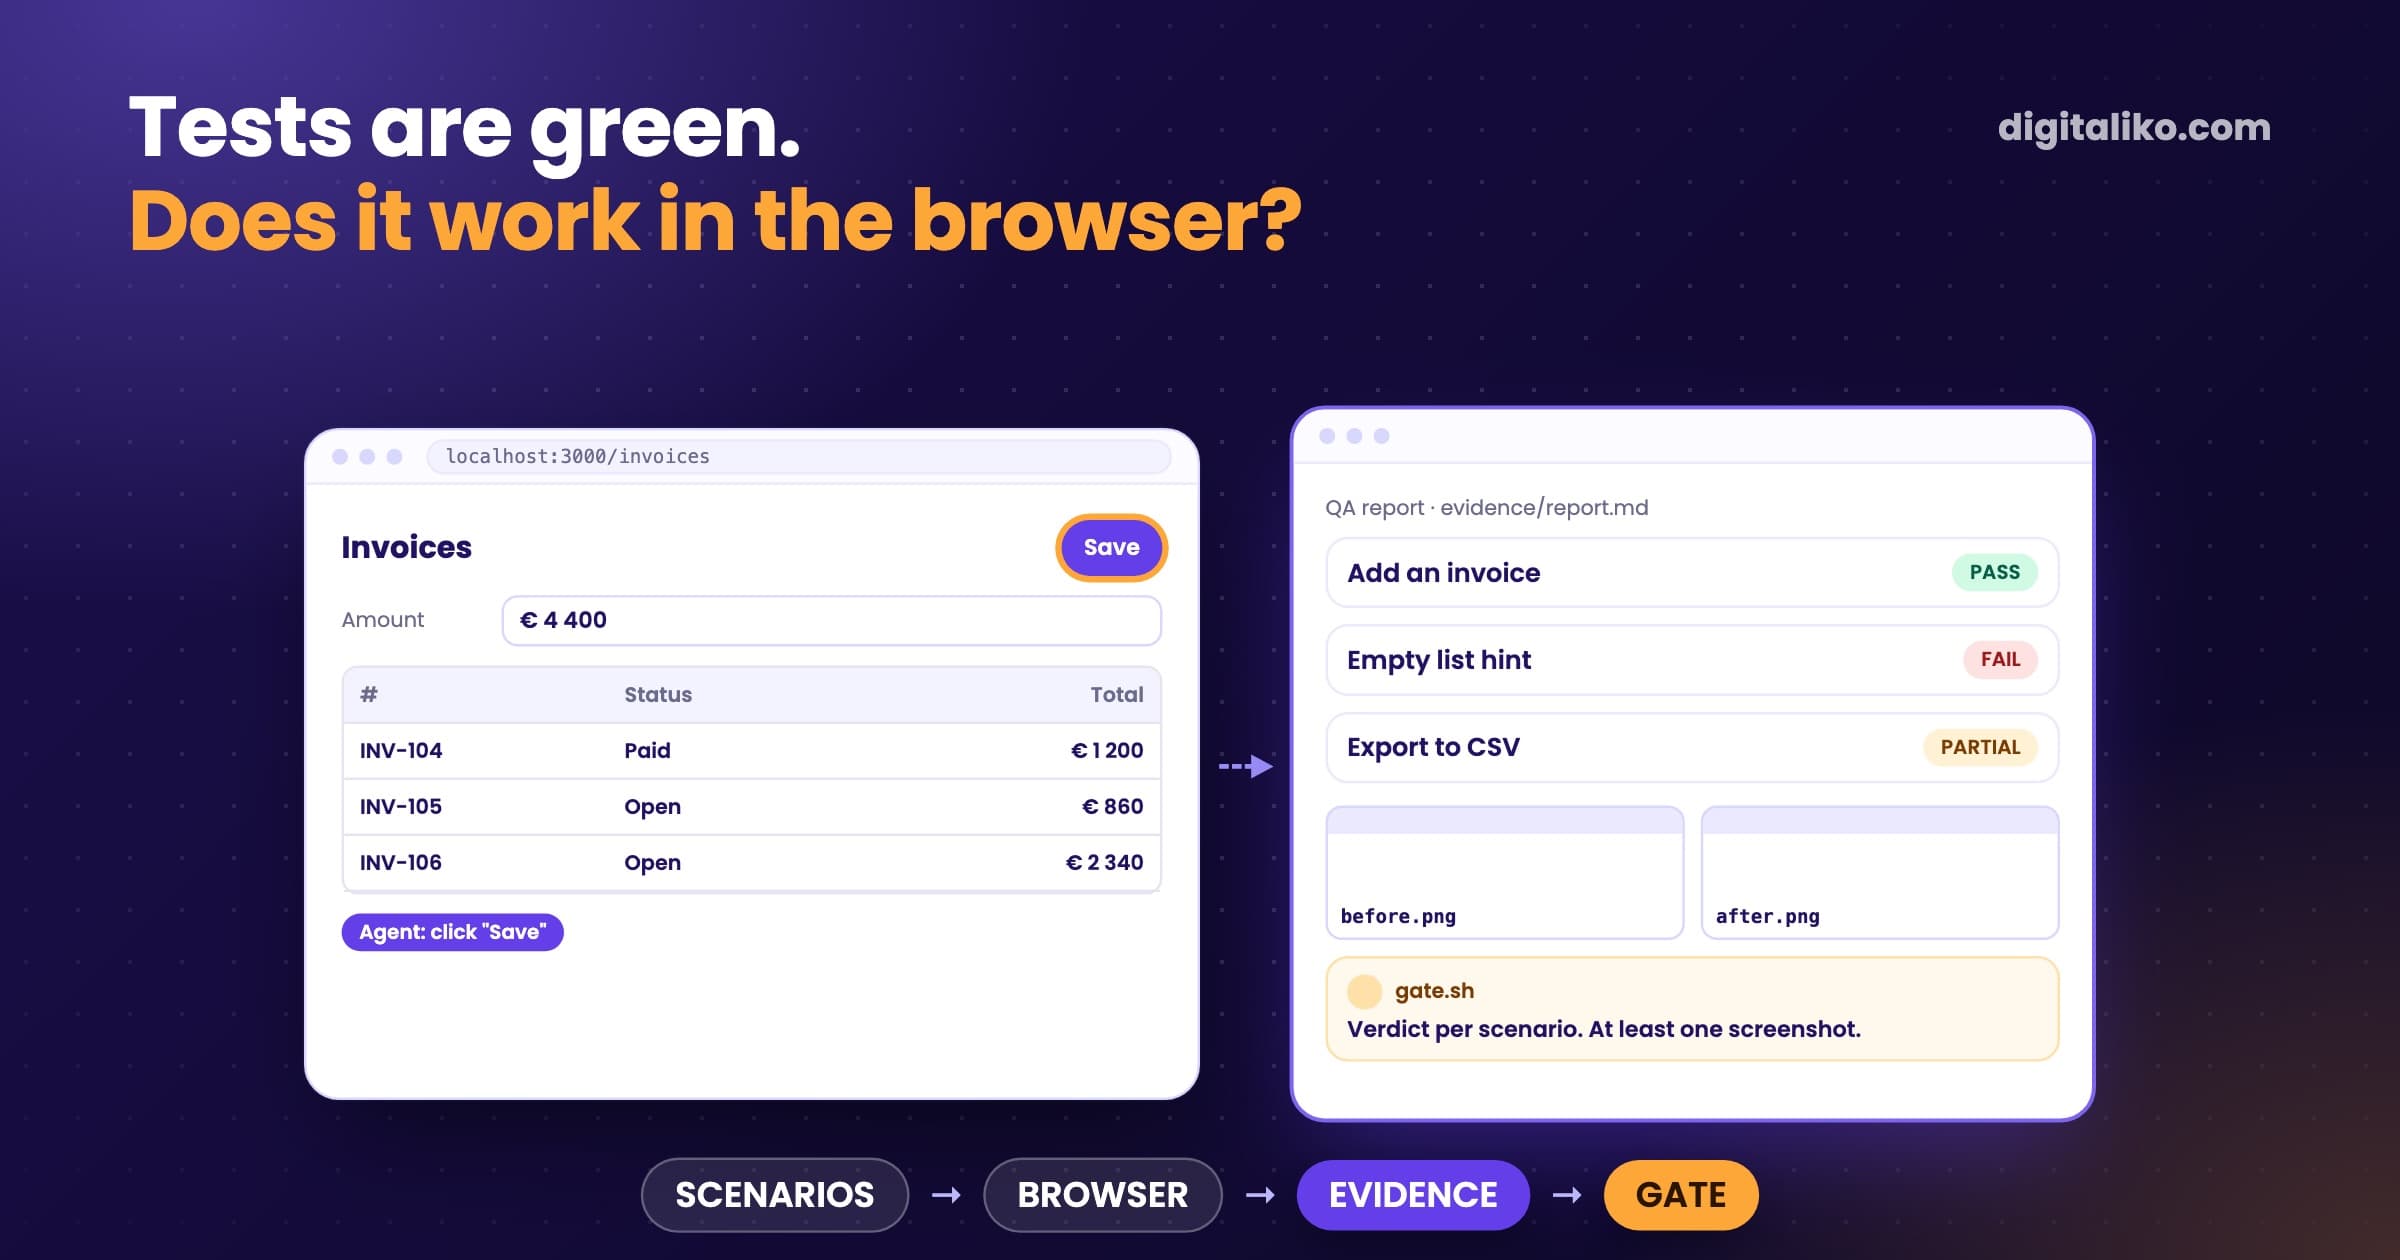
- A machine check comes first. Typecheck, lint, tests and our own gate run before any model has an opinion.
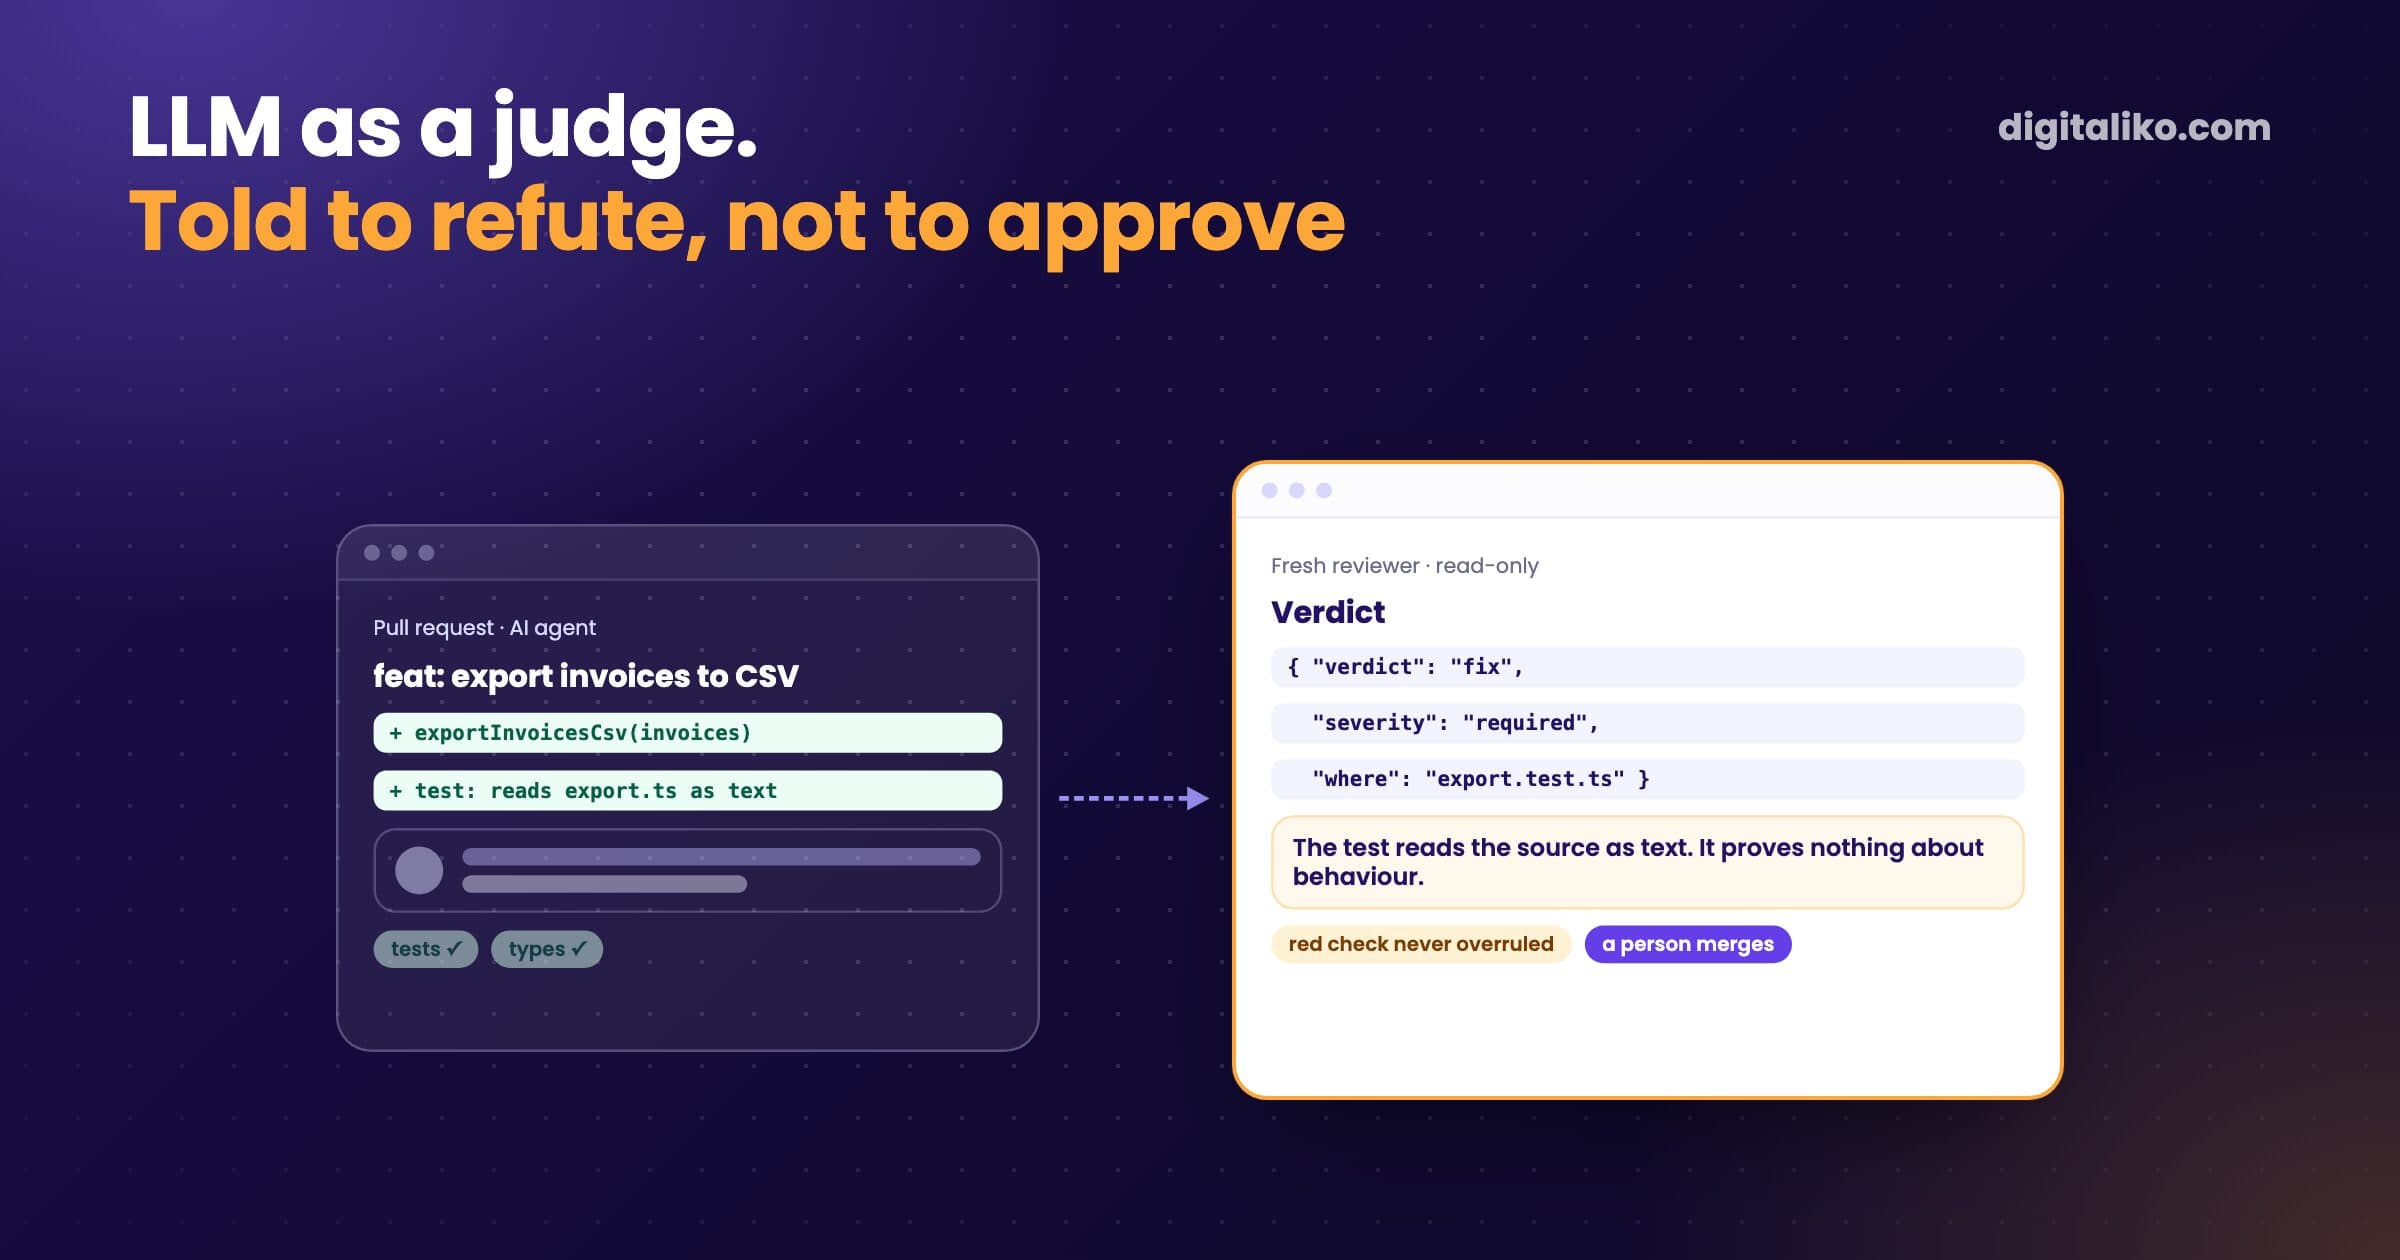
- Whoever did the work never grades it. A fresh model call with read-only tools reviews the result.
What does a developer do when the agent writes the code?
For us it started with a smaller task the agent carried all the way to a merge. That made us think about what a developer actually does now.
We no longer write the code. We make sure the result really works. And we take on the bigger problems, zoomed out, not line by line.
Today AI writes all of our code. So we don't focus on how it writes, but on what we want to achieve and how it proves that it works.
In practice that is four steps:
01
Plan
The goal, when it is done, the cases and the tests. Only then the code.
02
Hard rules
Tests, types, architecture, what the agent may and may not do. Until they pass, the change goes no further.
03
Review by another agent
Whoever wrote the code does not judge it.
04
A person at the end
Not reading every line. Checking whether the solution fits conceptually.
How does our loop take an issue to a PR?
One issue per run: one git worktree, one branch, one Claude Code session, one pull request.
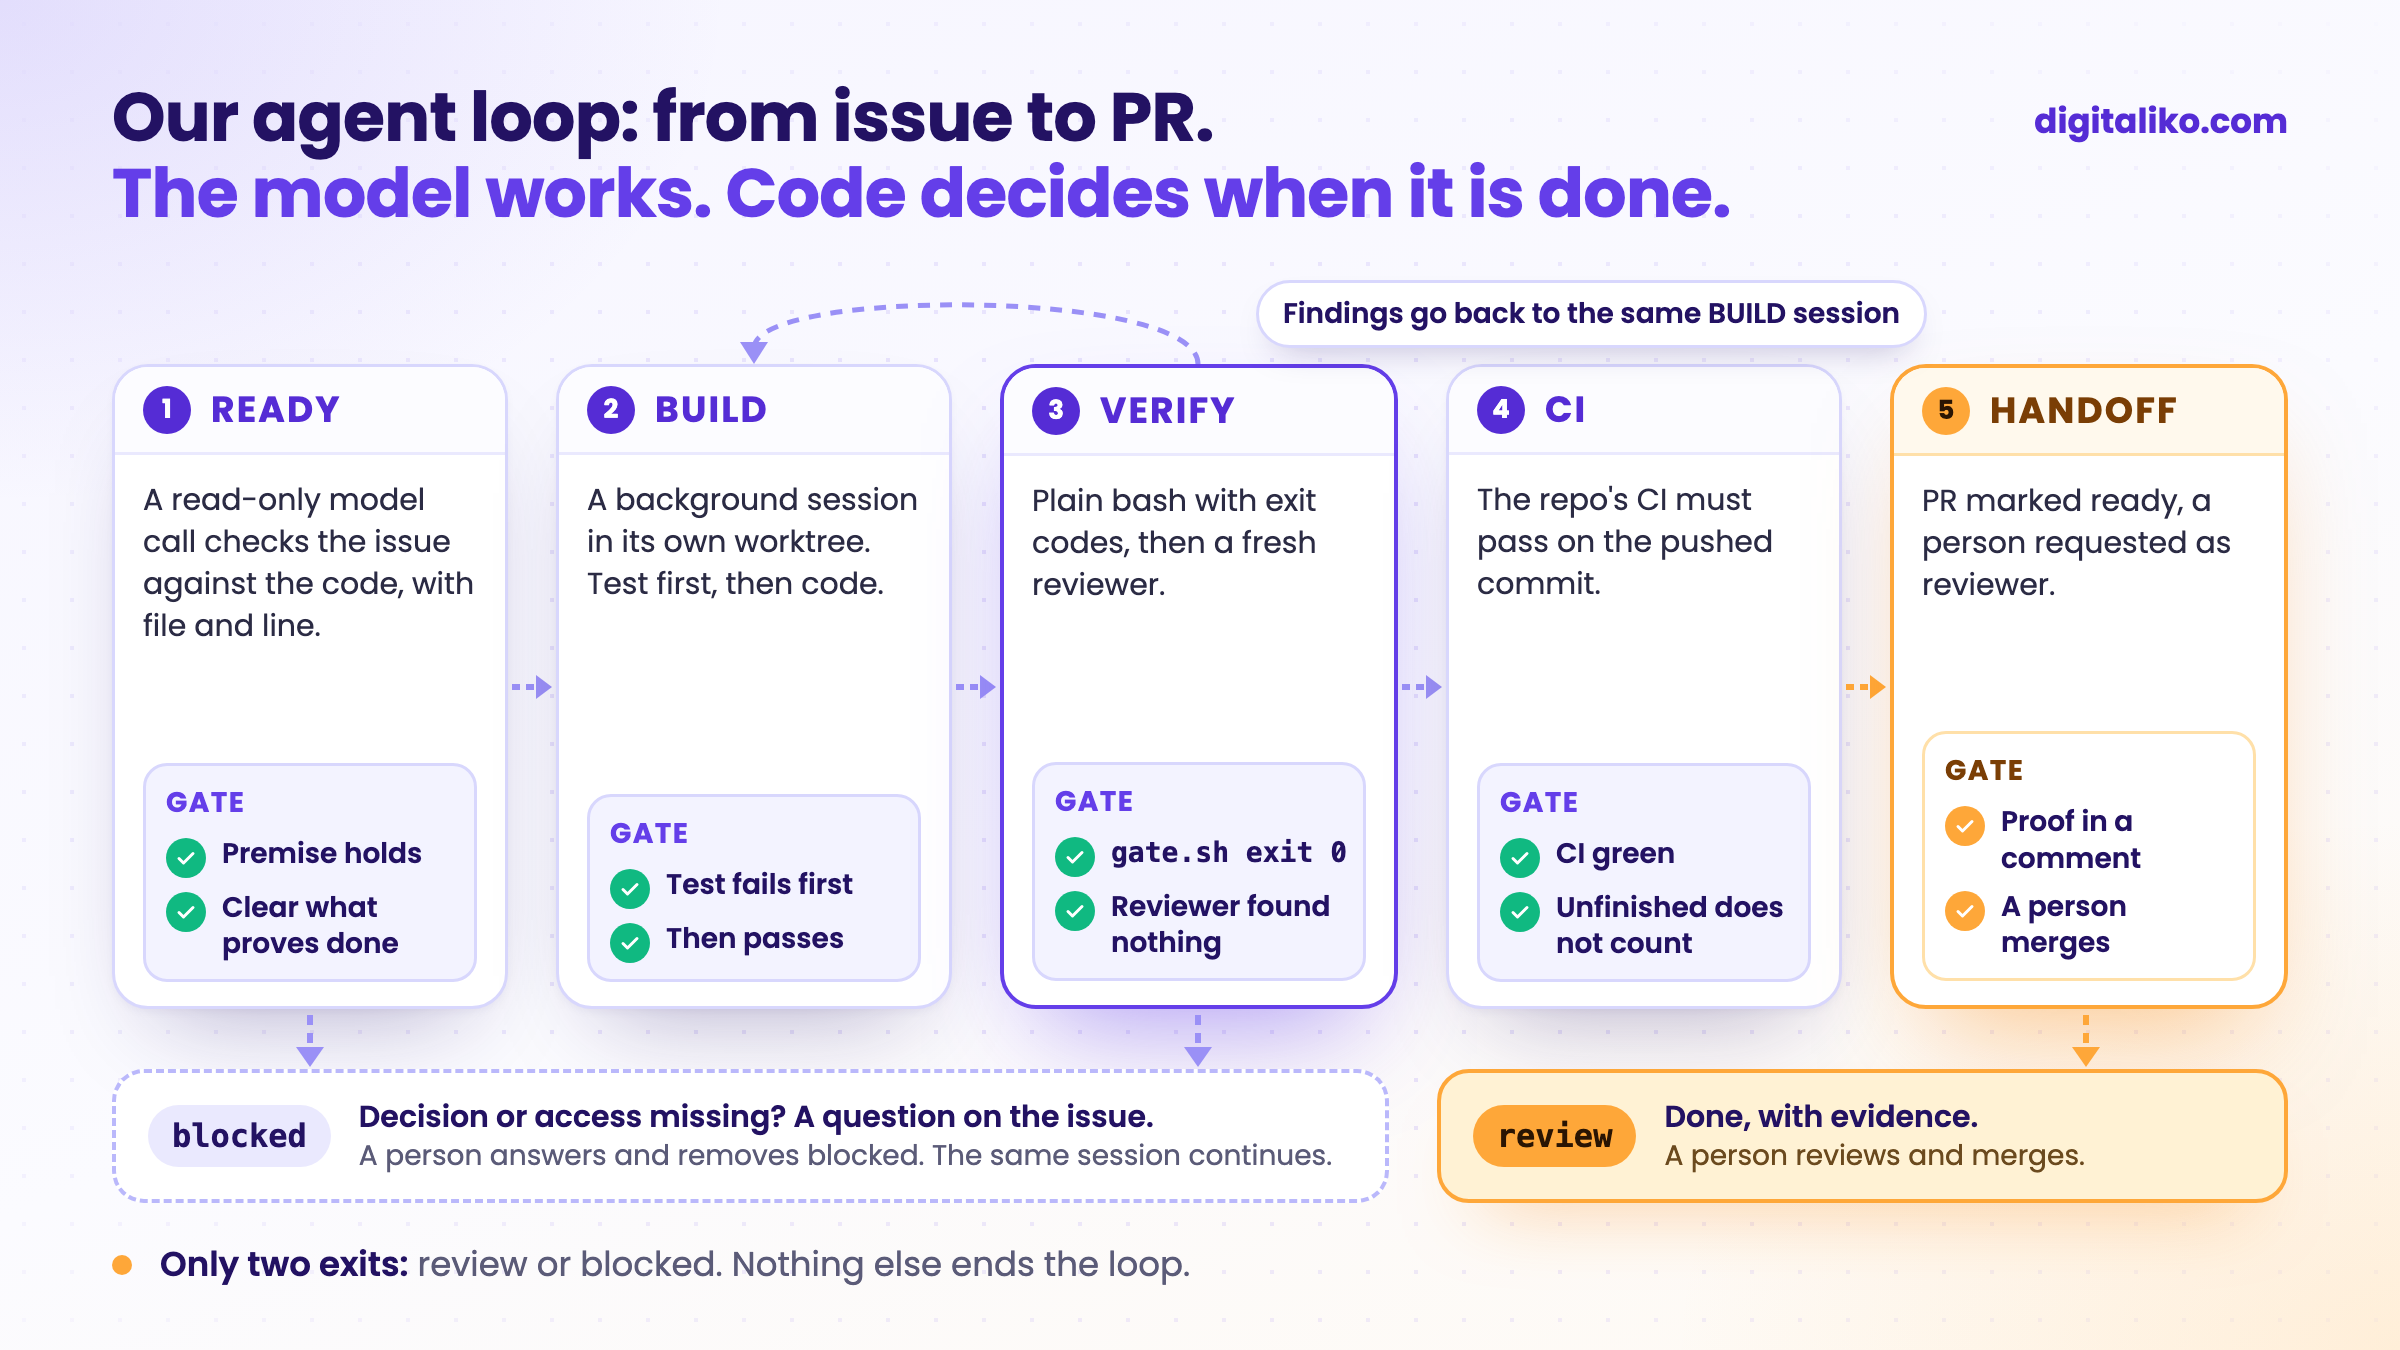
- READY. A read-only model call checks the issue against the code before anything starts. Does the premise hold, with file and line? What type of task is it? What proves it is done: a test, or only a person looking at it? If a decision is missing, the agent asks on the issue and stops.
- BUILD. A background Claude Code session does the work in its own worktree. For code it first writes one test that fails on the unchanged code, then implements.
- VERIFY. Two layers. First
gate.sh, plain bash with exit codes. Then a fresh reviewer whose only job is to try to refute the work. Its findings go back into the same BUILD session. - CI. The repository's own CI must pass on the pushed commit. A check that also fails on the main branch is reported as pre-existing, not blamed on the branch.
- HANDOFF. The PR is marked ready, a person is requested as reviewer, and a comment carries the proof.
There are only two exits: review (done, with evidence) or blocked (a question on GitHub). When a person answers and removes blocked, the same session continues with its full context.
Which lines of code carry the loop?
Three short pieces do most of the work.
Every model call returns a typed JSON answer. No answer means failure, never a default. Shortened:
# one read-only model call with a typed answer; no object back = failure, never a default
ask() {
    ( cd "$tree" && claude -p "$prompt" --tools "Read,Grep,Glob,WebFetch" \
        --json-schema "$(cat "$schema")" --output-format json ) > "$out.raw"
    jq -e 'select(.subtype == "success") | .structured_output // empty' "$out.raw" > "$out" && [ -s "$out" ]
}
A red machine check can never be talked into green:
verdict=$(jq -r .verdict "$R/verify-$round.json")
[ "$mrc" != 0 ] && [ "$verdict" = pass ] && verdict=fix   # a red executable check is never overruled to pass
And a loop that does not converge stops. If the reviewer reports the same finding twice in a row, the task goes to a person with that finding attached. Another round would not fix it.
One more detail: untrusted text gets a fence. Issue bodies and PR comments reach the model marked as data, not instructions, with HTML comments stripped first. That is where injected instructions like to hide.
Why are rules in a text file not enough for an agent?
Not long ago the agent had its rules only in rules files. Sometimes it didn't follow them. So we turned them into checks it cannot get around: ESLint, architecture tests, a type check before push, and all of it again in CI.
An agent can read a text its own way. Not a check.
Every extra gate narrows the path: architecture tests, a check that the code is complete, required files. The more gates, the less room the agent has to swerve. Only the allowed path is left.
There is a side effect too:
The projects I work on today have more tests than I have ever seen.
Where does a person come in?
At three moments, and nowhere else:
| Moment | What the person does |
|---|---|
| Start | Assigns the issue. That is the approval. |
| Question | Answers on the issue and removes blocked. |
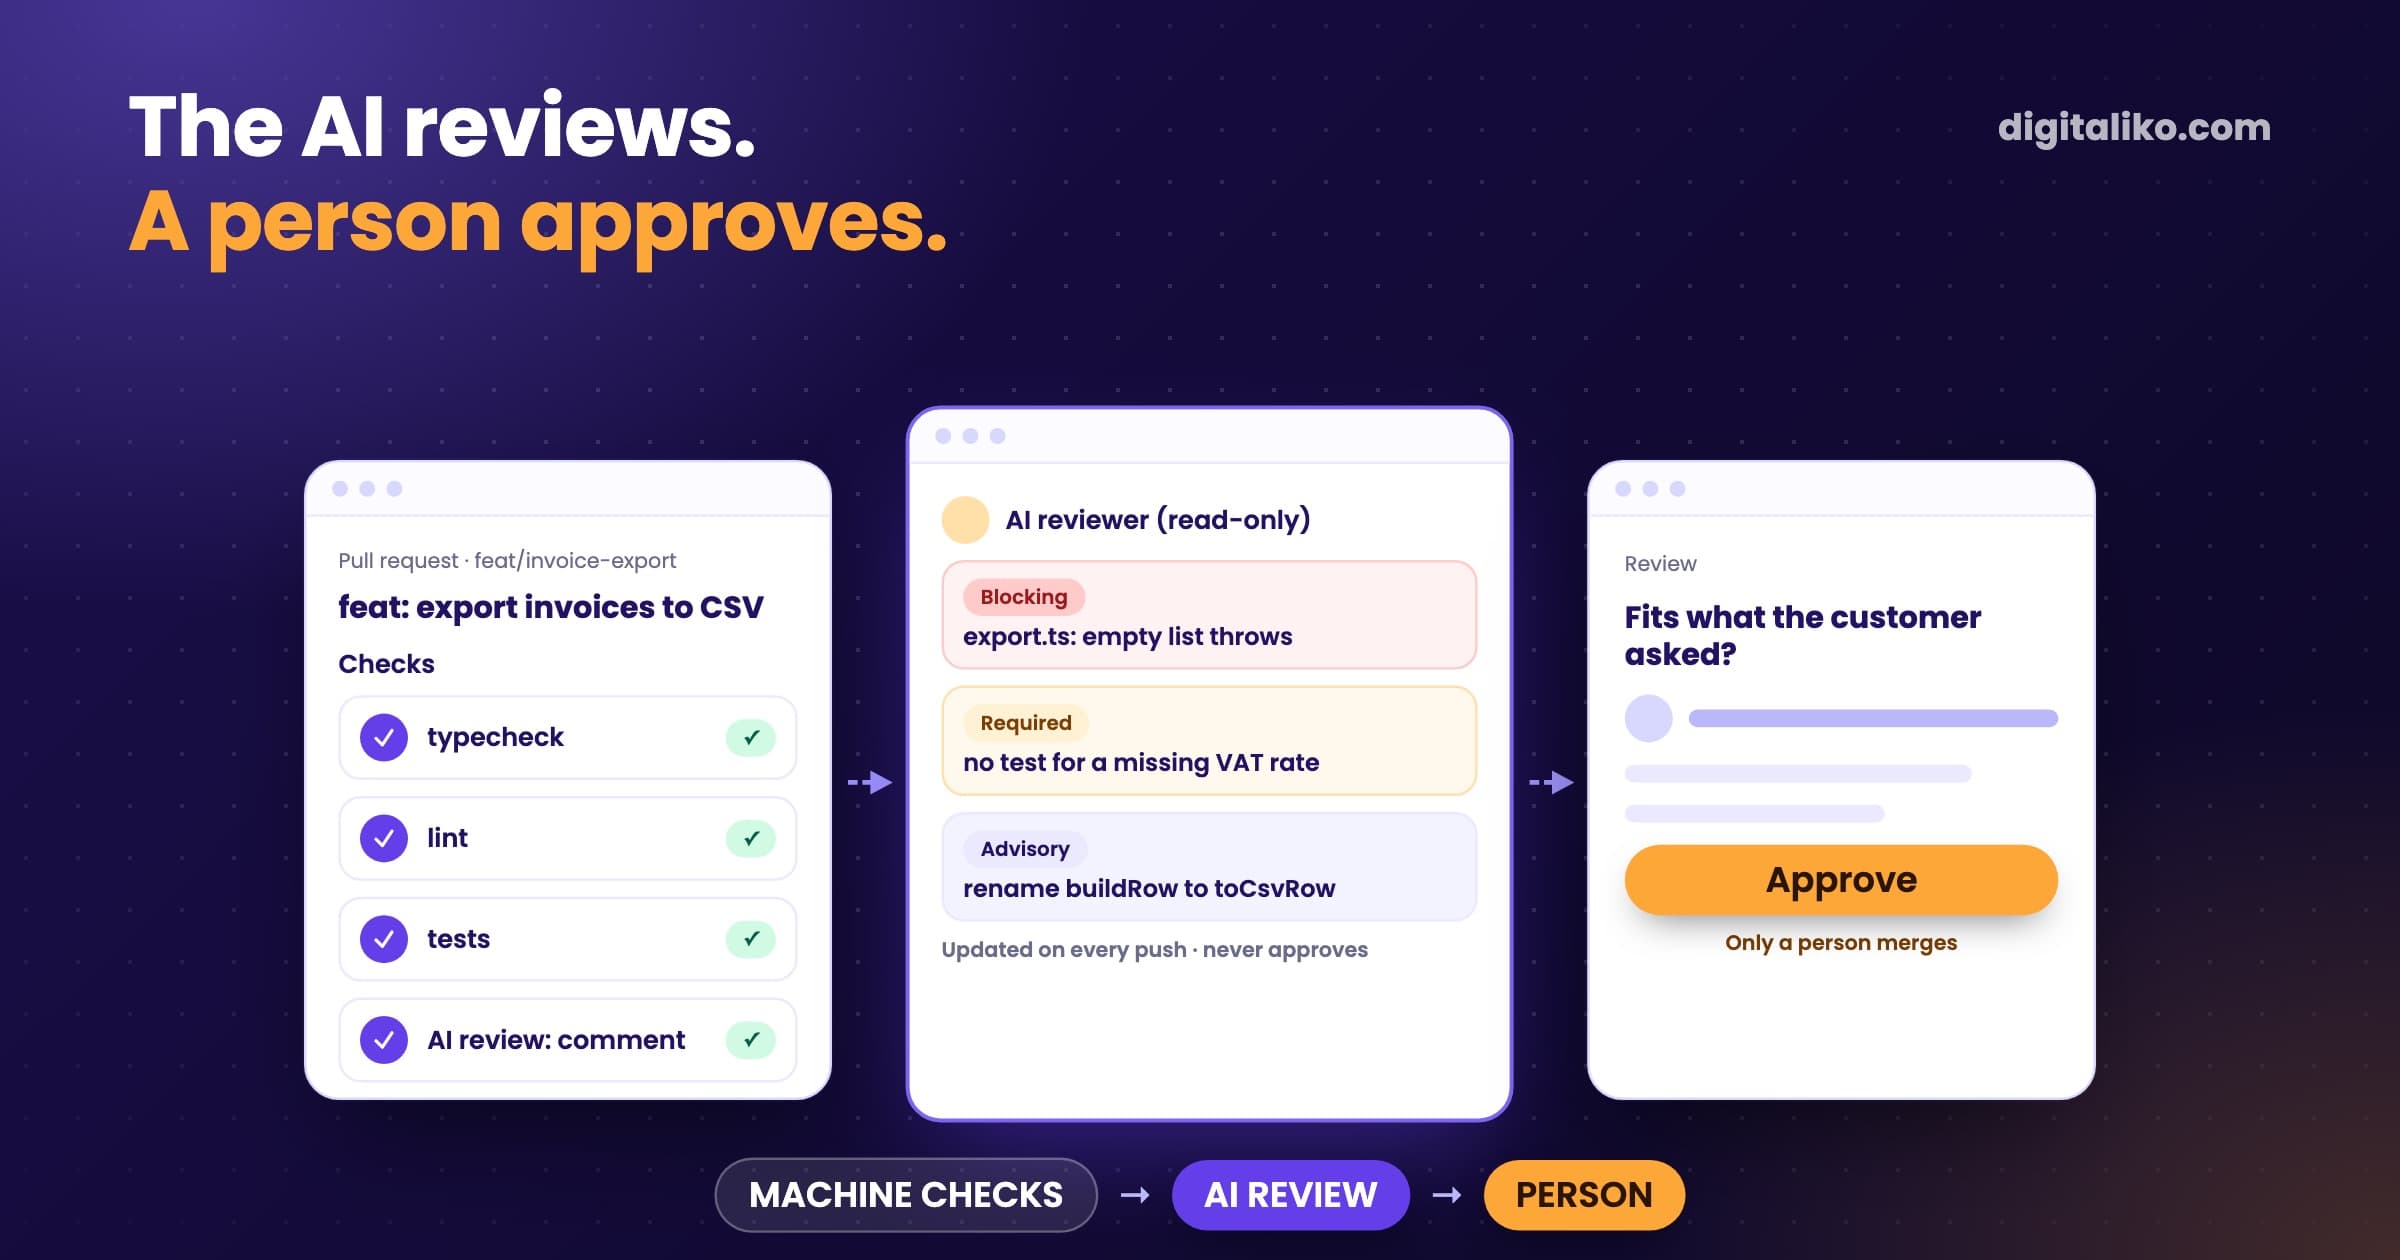
| Hand-off | Reviews and merges. Only a person merges. |
Review is the bottleneck, not the agent. So the dispatcher starts no new task while agent PRs wait for people. A task already in progress may continue. Merging, pushing to main, sending and deploying are blocked below the agent, in hooks it cannot edit.
What broke along the way?
More than we expected. These are the ones worth knowing:
- The dispatcher stopped starting tasks, silently. A change to the review limit put a count between
jq |andwhile read. The loop then read empty input, and no task started. Nothing failed, nothing alerted. An audit found it. The fix came with a dispatcher test on a stubbedgh, red on the old code and green on the new. - Infrastructure landed on a person as
blocked. A session that died in its first minutes was a missing login or token, not bad work. Now it retries on the next tick instead. - CI that never finished counted as green. Now it is a hand-back. Not finished is not passed.
- The readiness check came late. We added the premise check against the code later. Today it is the first stage, and that is where we would start.
The hardest step is usually the last one: verifying that it really works end to end. Gates and real tests. Keeping the environments aligned, so the checks always run, takes the most work. One trick has worked well for us: we send an agent into the feature as a type of customer, a persona, to explore it on its own.
Before this loop we tried two other shapes. One was a label-driven pipeline of GitHub Actions workflows. The other was one-shot @claude mentions in issues. We deleted both. Stateless CI jobs fit badly when the worker needs to resume a session and ask a person in the middle of a task.
Where do we disagree with how harness engineering is written about?
Most writing is about the tools. In our view, what decides is where a person stands in the process.
Can you run this in your own team?
Start with the quality gates. If your team has none, start there. Our loop READY → BUILD → VERIFY → CI → HANDOFF is simple and it works. Every system needs a slightly different one, though.
The loop itself is tied to our setup. The parts that matter most are not. We published them as a small public repository: the Claude Code production starter. It has agent rules, hooks that stop dangerous commands, a Stop hook that blocks "done" while checks are red, and a CI gate with red-proof tests. MIT licensed. Clone it, keep the tooling, replace the app.
Which of these does your team already have?
What goes into the rules that feed a harness like this is covered in Rules for AI code in a team. When the agent's planning mode is enough for a team is covered in Claude Code plan mode.
Want a harness like this in your repository?
We build this kind of loop right in a team's repository as part of AI-native SDLC for development teams. Is your team short of hands rather than rules? See a senior developer for your team. Since 2023 we have delivered 15+ production projects. A senior plugs into your repository and pull requests on day one.
We get back to you within two business days, and together we pick what to fix first.
If you'd rather talk first, book a 15-minute meeting with Filip.
What does your agent do today when it is unsure: ask, or guess?
In short
- The model does the work. Code decides what the agent takes and when it is done.
- Machine checks first, then a fresh reviewer that did not write the code.
- A person comes in three times: assigns the issue, answers a question, reviews and merges.
- Start with the quality gates. Add the loop once one session per task is no longer enough.
Frequently asked questions
What does harness engineering mean in practice?
Building the code around an AI agent: which task it takes, which tools and rules it gets, what checks its work and when a person takes over. The model does the work. The harness decides when the work counts as done.
What is an agent harness?
The fixed loop an AI agent runs in. Ours is a bash dispatcher and runner. It reads GitHub issues, starts one Claude Code session per issue, runs executable checks and a fresh reviewer, then hands a PR to a person.
Why not let one long agent session decide when it is done?
Because the agent that did the work grades it too kindly. In our loop code decides when the work is done: exit codes first, then a reviewer that did not write the code and cannot change it.
Does the agent merge its own pull requests?
No. Only a person merges. Merging, pushing to the main branch, sending and deploying are blocked by hooks below the agent, which it cannot change.
Do I need your whole setup to start?
No. Start with the public Claude Code production starter: agent rules, hooks, a Stop hook and a CI gate with red-proof tests. Add a loop when one agent session per task is no longer enough.
Ask AI about this article
The AI also draws on our other articles and experience from real projects.
ChatGPTClaudePerplexity