Skip to content

Engineering

How we build software with AI in the team

For CTOs and engineers: how the agent, the harness and senior quality control work together on our projects. The rules we use on 15+ production projects since 2023.

Your team has AI, but no rules or checks? AI-native SDLC. Your team can't keep up with the backlog? Senior developer for your team.

AI in the dev team

AI in the dev team

Claude Code best practices for a team: 7 that hold

Most Claude Code tips are written by solo users. These seven are team practices: a short CLAUDE.md that CI keeps short, one shared plugin, permissions and hooks in the repo, one issue to one PR, a test that fails first and a reviewer that did not write the code.
AI in the dev team

Claude Code skills and plugins: one set for every repo

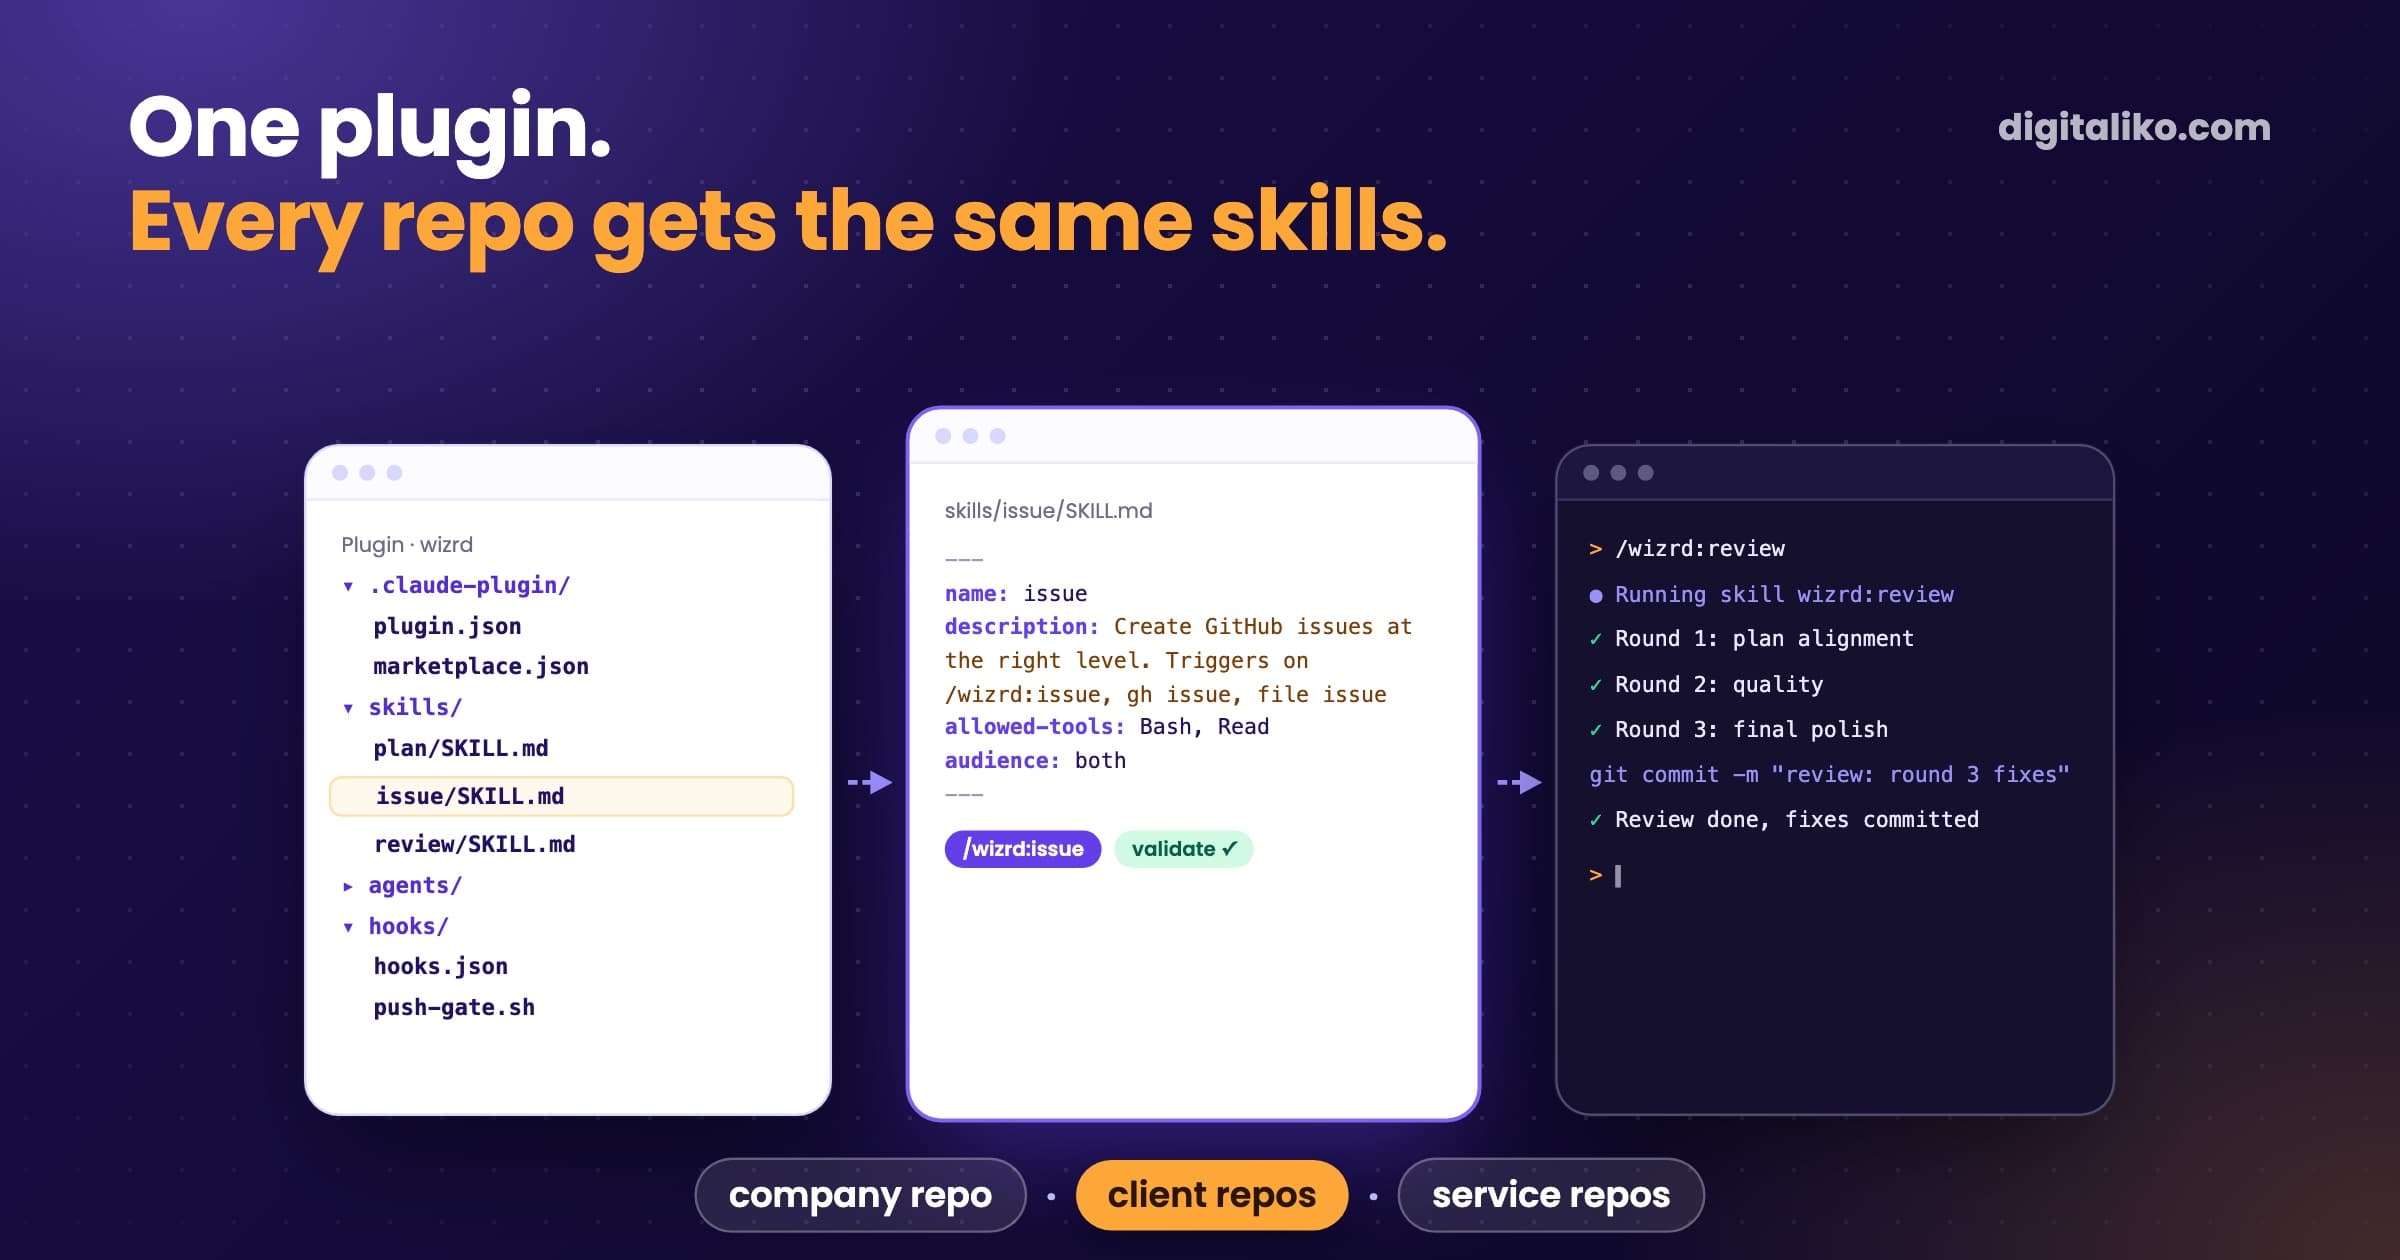
Claude Code skills are SKILL.md instructions the agent loads when a task needs them. A plugin ships skills, agents and hooks as one unit. How we run one plugin in every repo, and what broke on the way.

AI in the dev team

Claude Code subagents and worktrees: when to use which

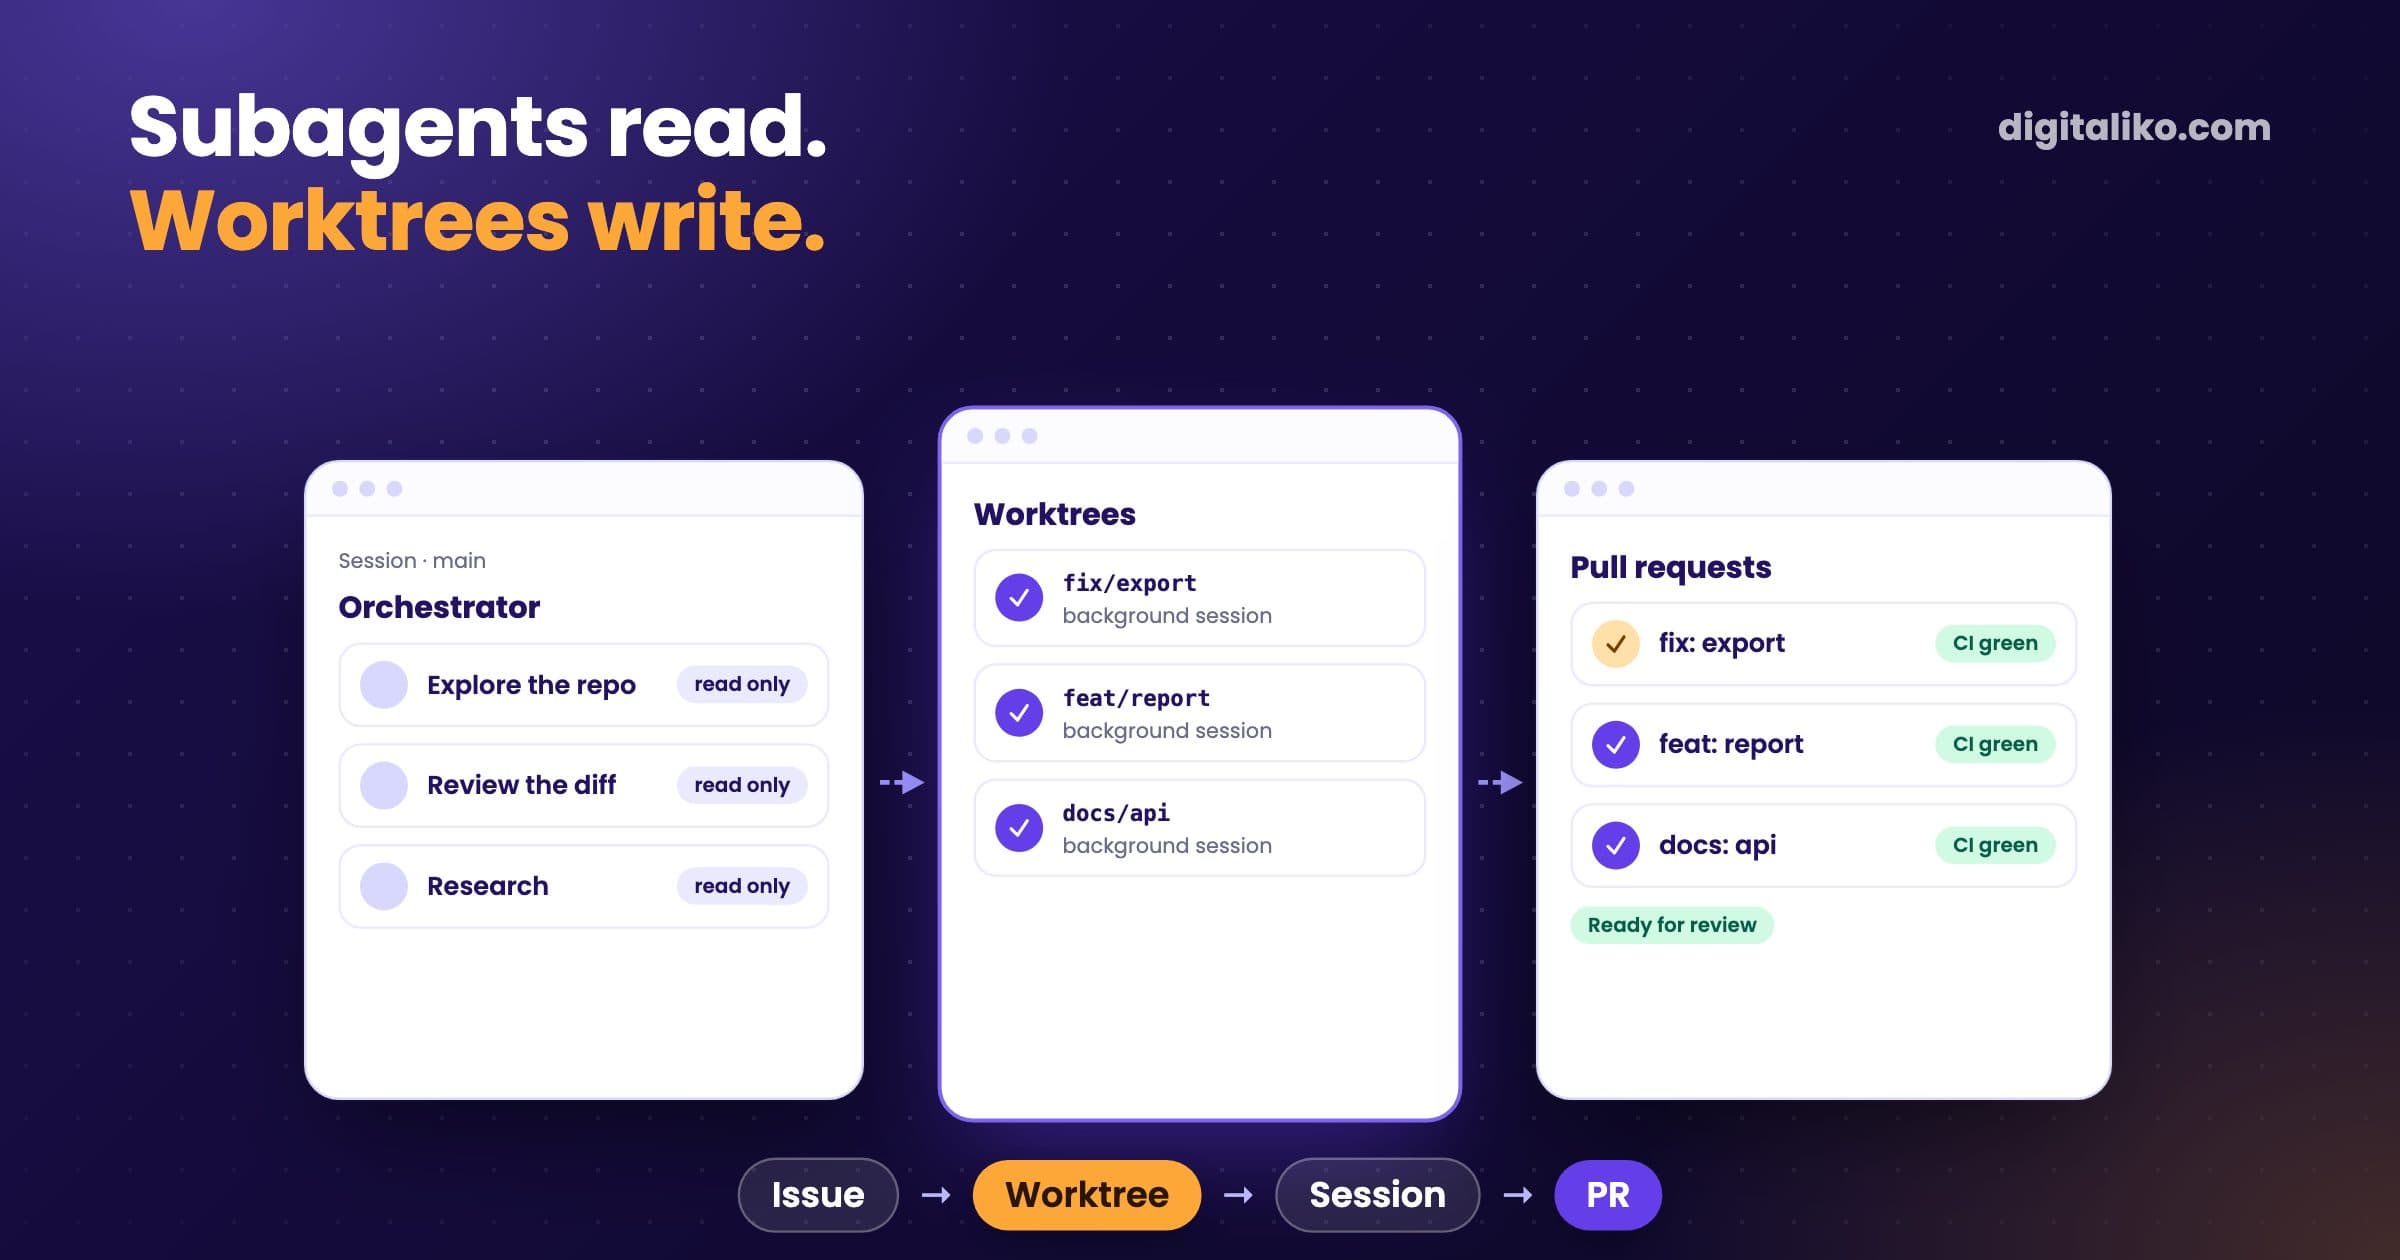
Claude Code subagents split work inside one session, worktrees isolate file edits. Our rule from running parallel agents every day: subagents only read, every change gets its own worktree and PR. What broke, and how to start.

AI in the dev team

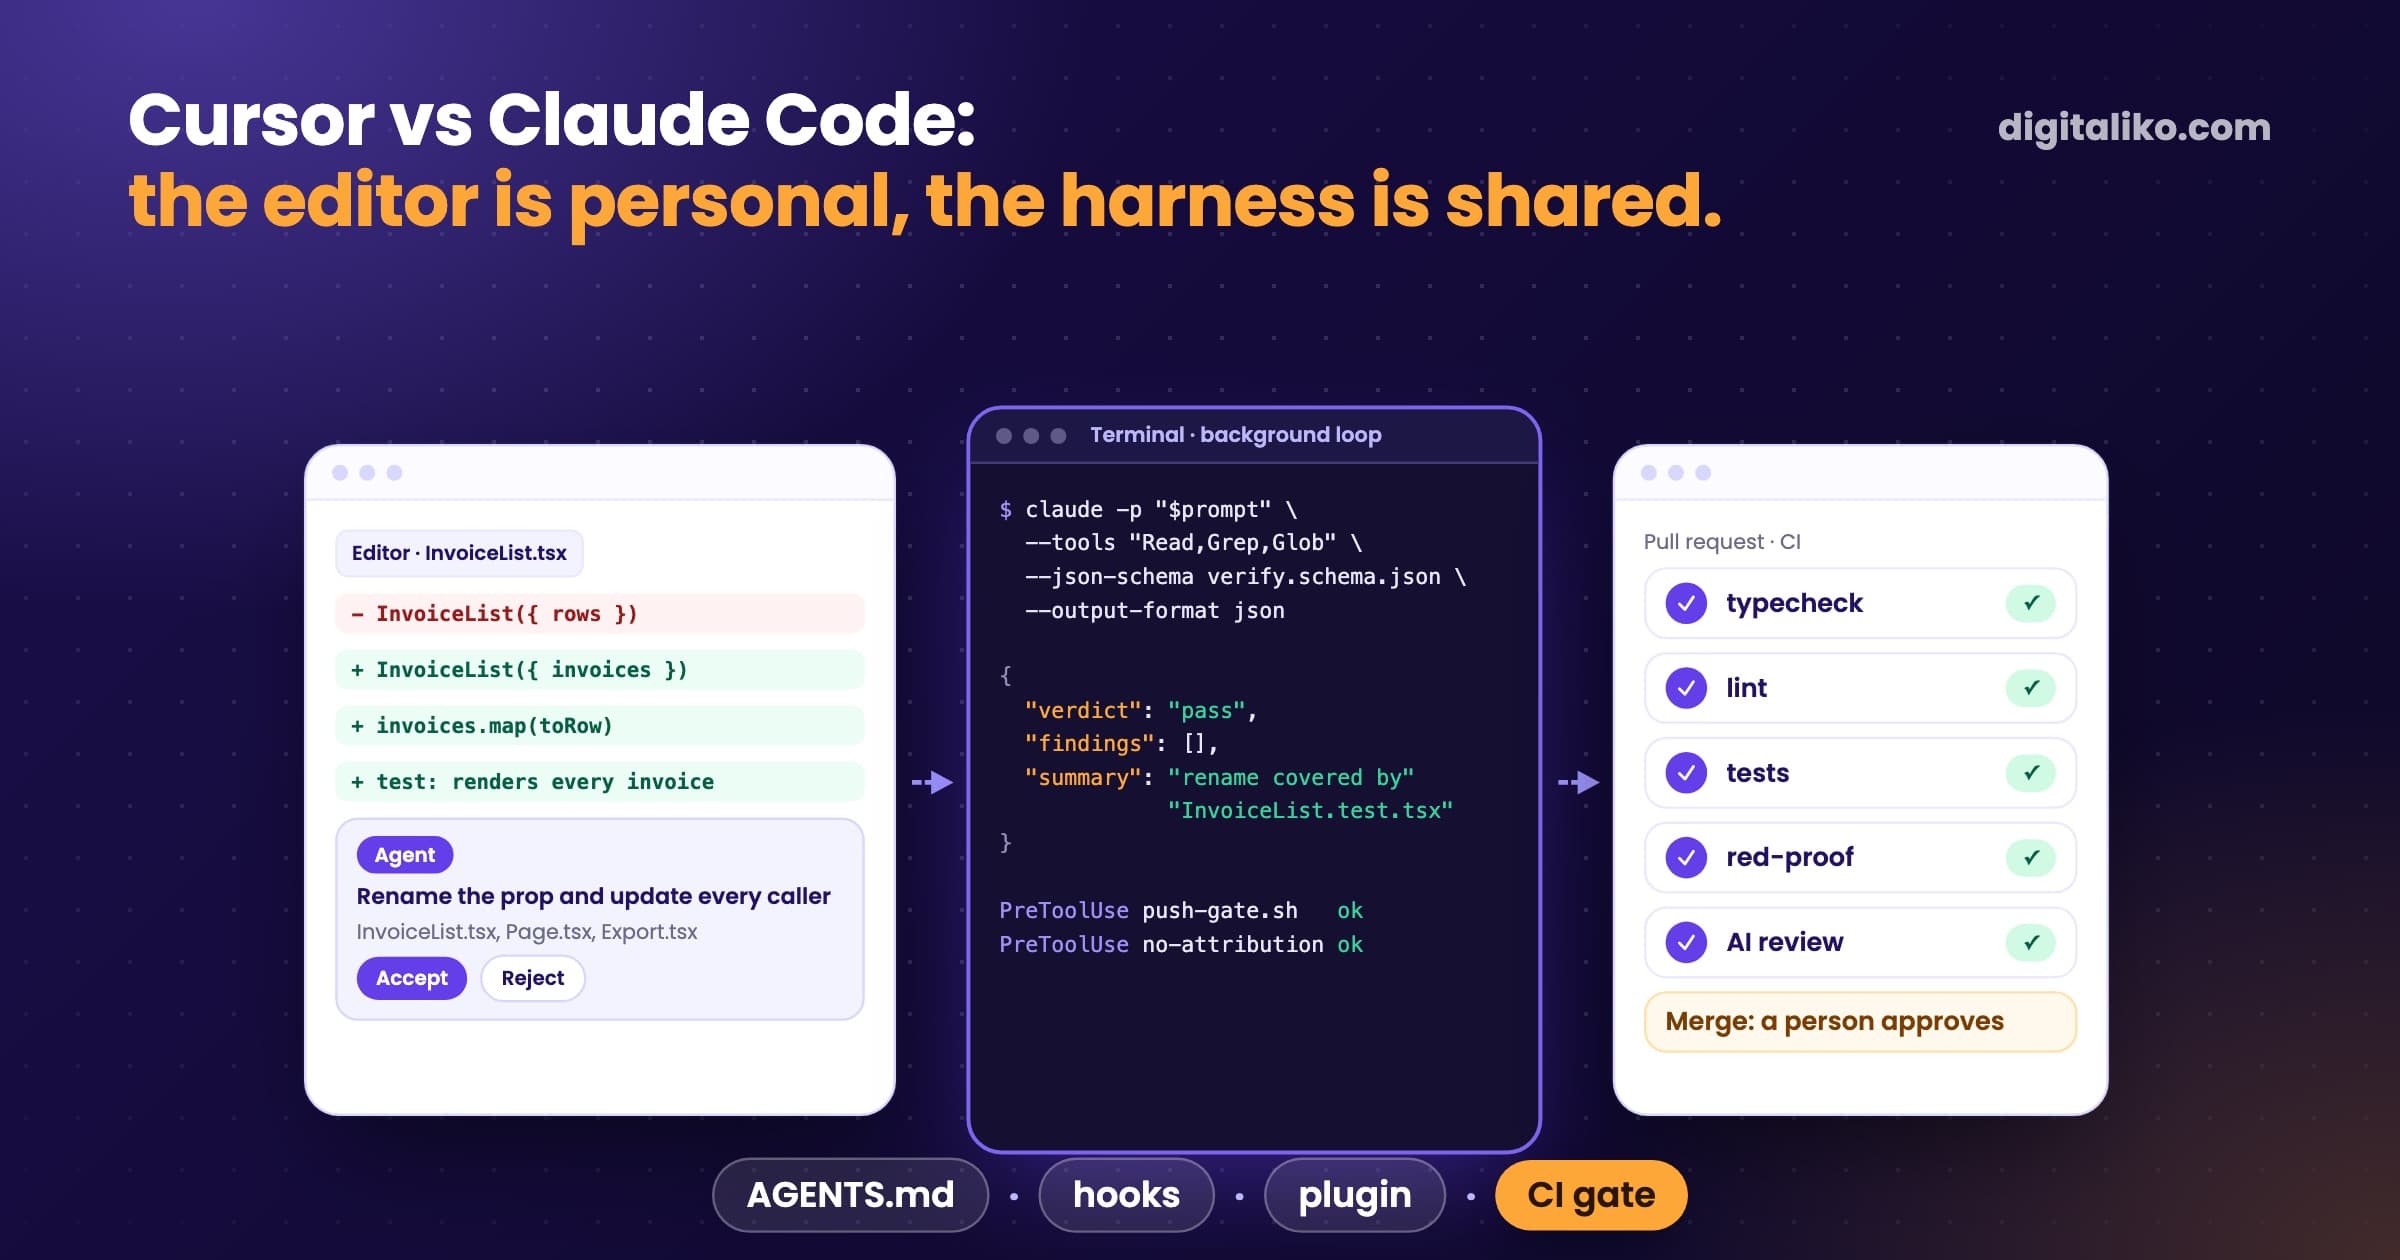
Cursor vs Claude Code: why we build on the terminal agent

Cursor vs Claude Code for a team, not a benchmark: Cursor is an editor with an agent inside, Claude Code is an agent that runs the same on a laptop, in CI and in a background loop. Why our whole harness runs on Claude Code, and when Cursor is the better pick.

AI in the dev team

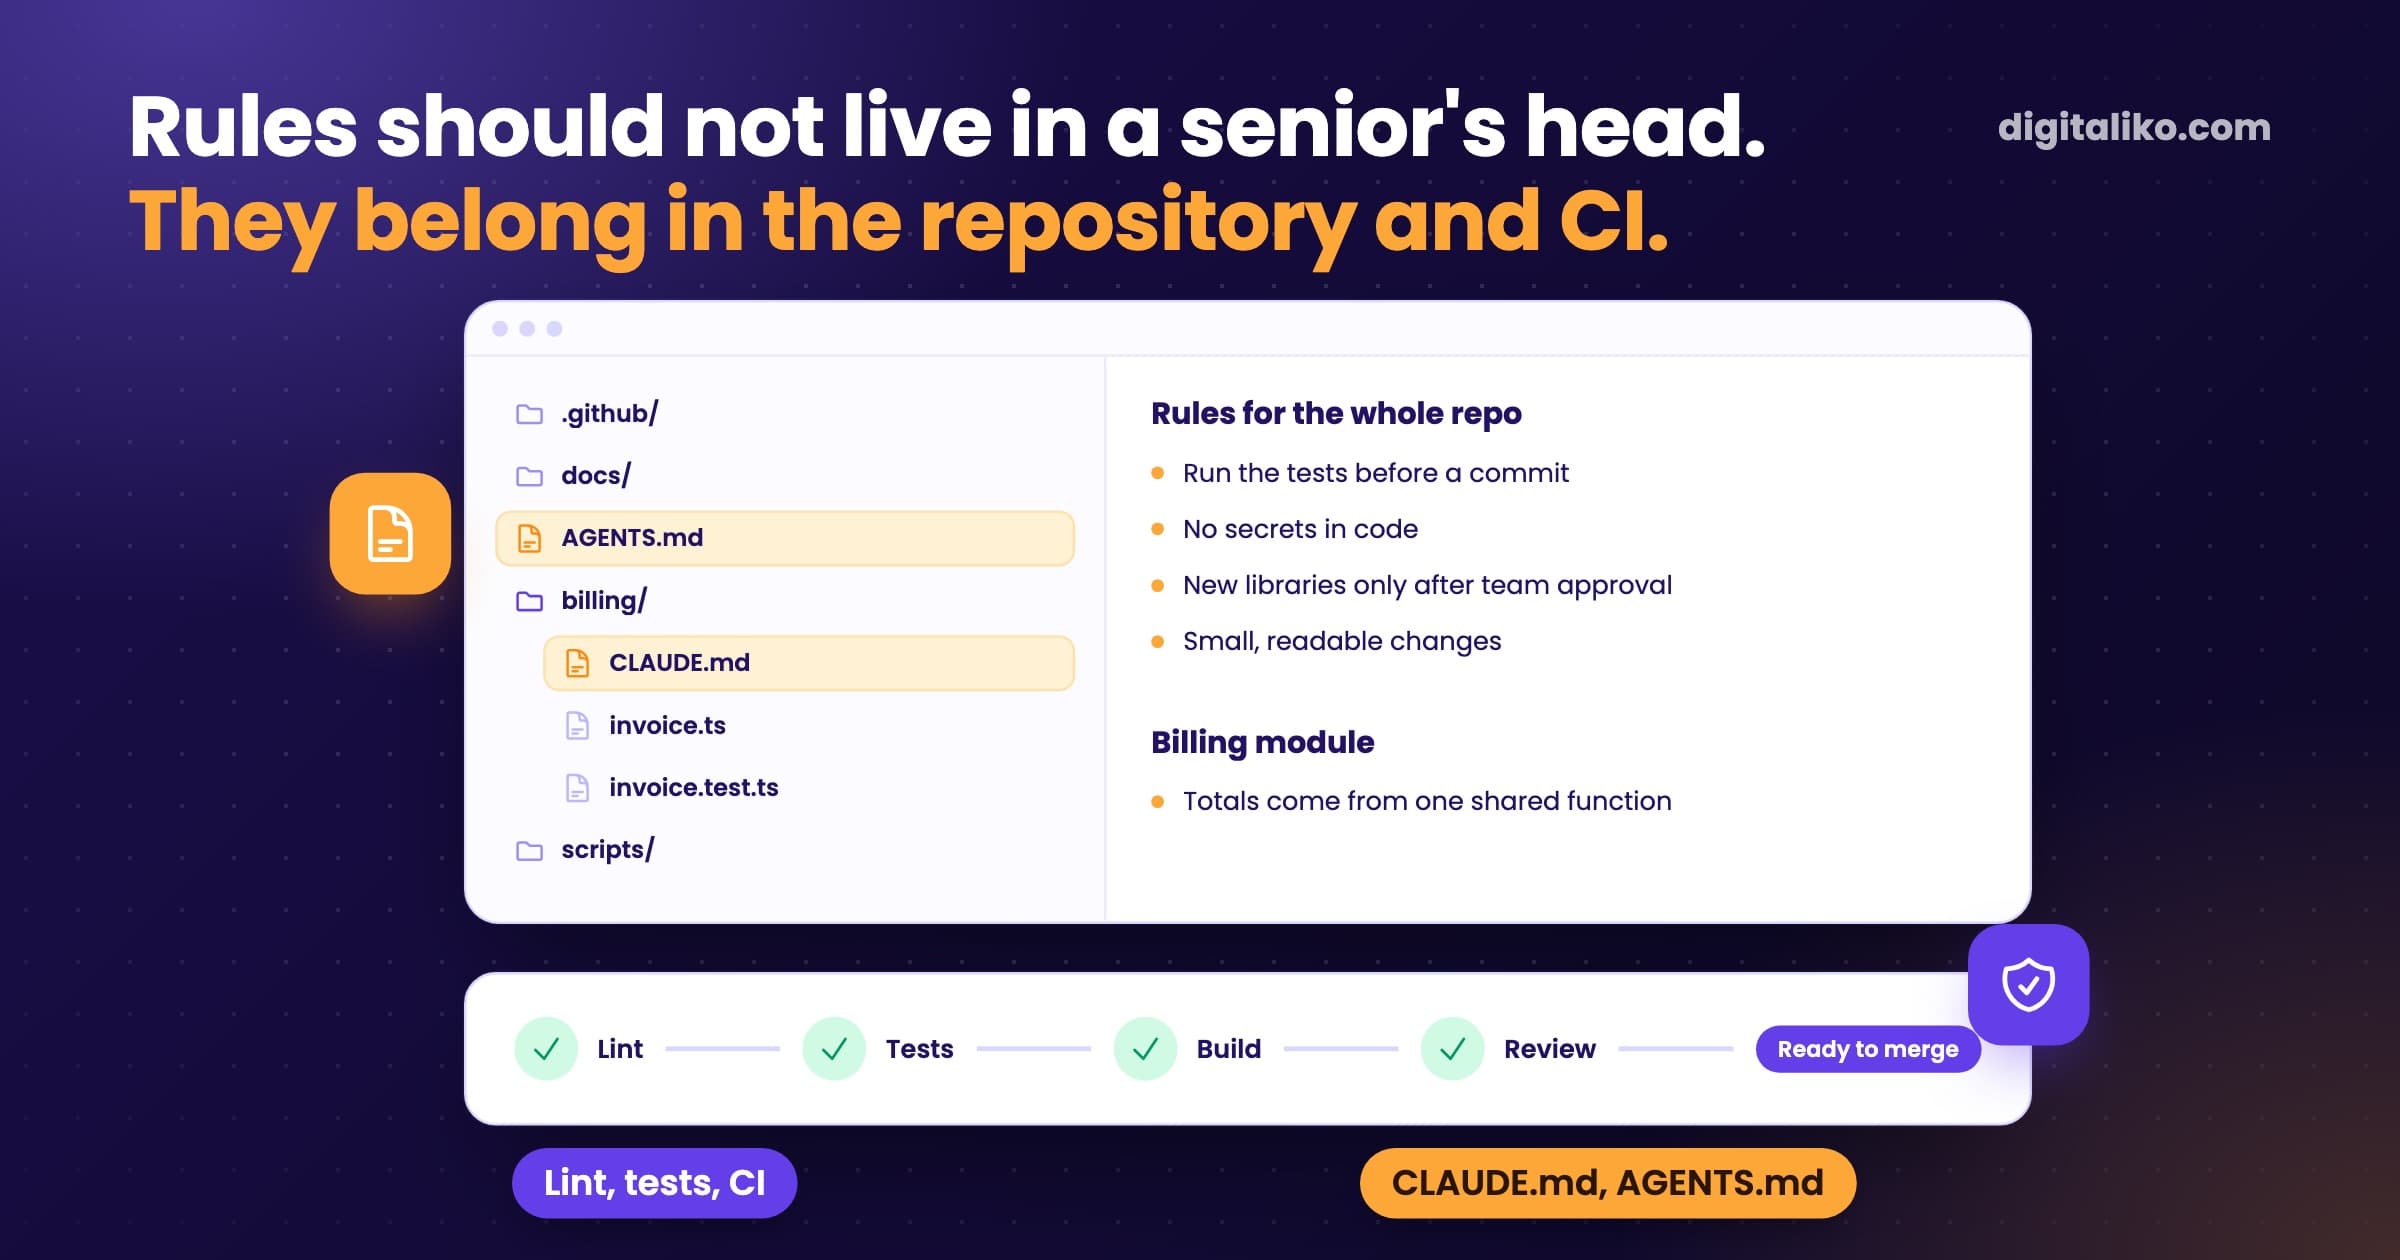
CLAUDE.md and AGENTS.md: rules for AI code in a team

Rules for AI code in a team belong in the repository: a short CLAUDE.md or AGENTS.md, lint and tests for what matters most, review by someone other than the author. What to write, where, and what to leave out.

AI in the dev team

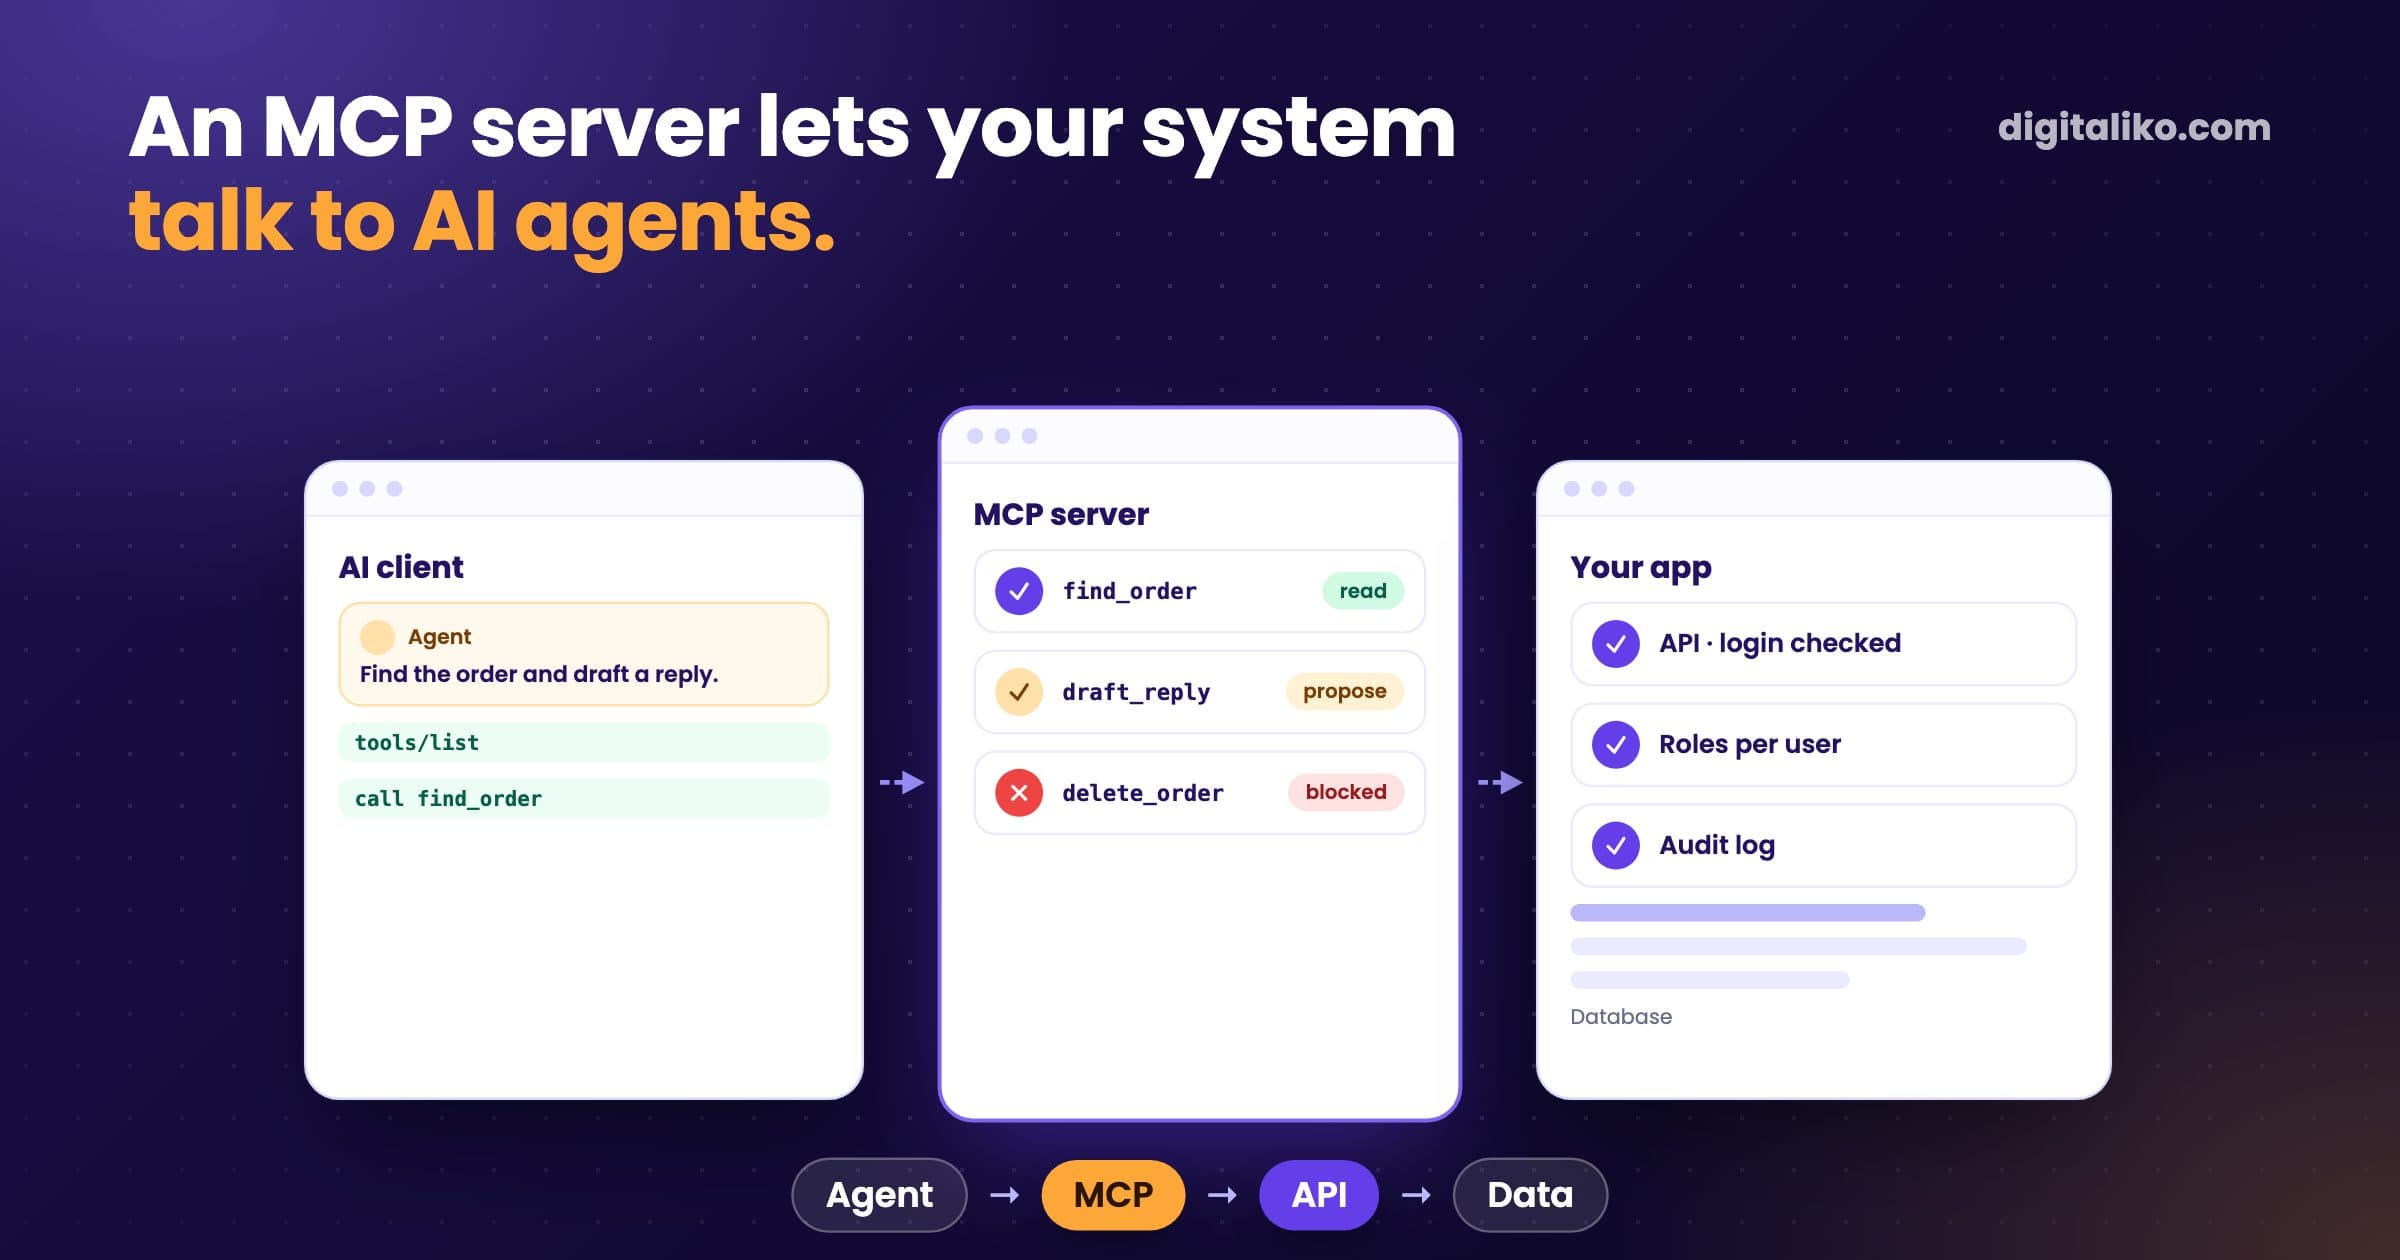
How to build an MCP server, and when you should not

How to build an MCP server: pick stdio or Streamable HTTP, register a few tools with a schema, connect a client and add authorization before it goes remote. What we learned from our own prototype, and which tools an agent should get.

AI in the dev team

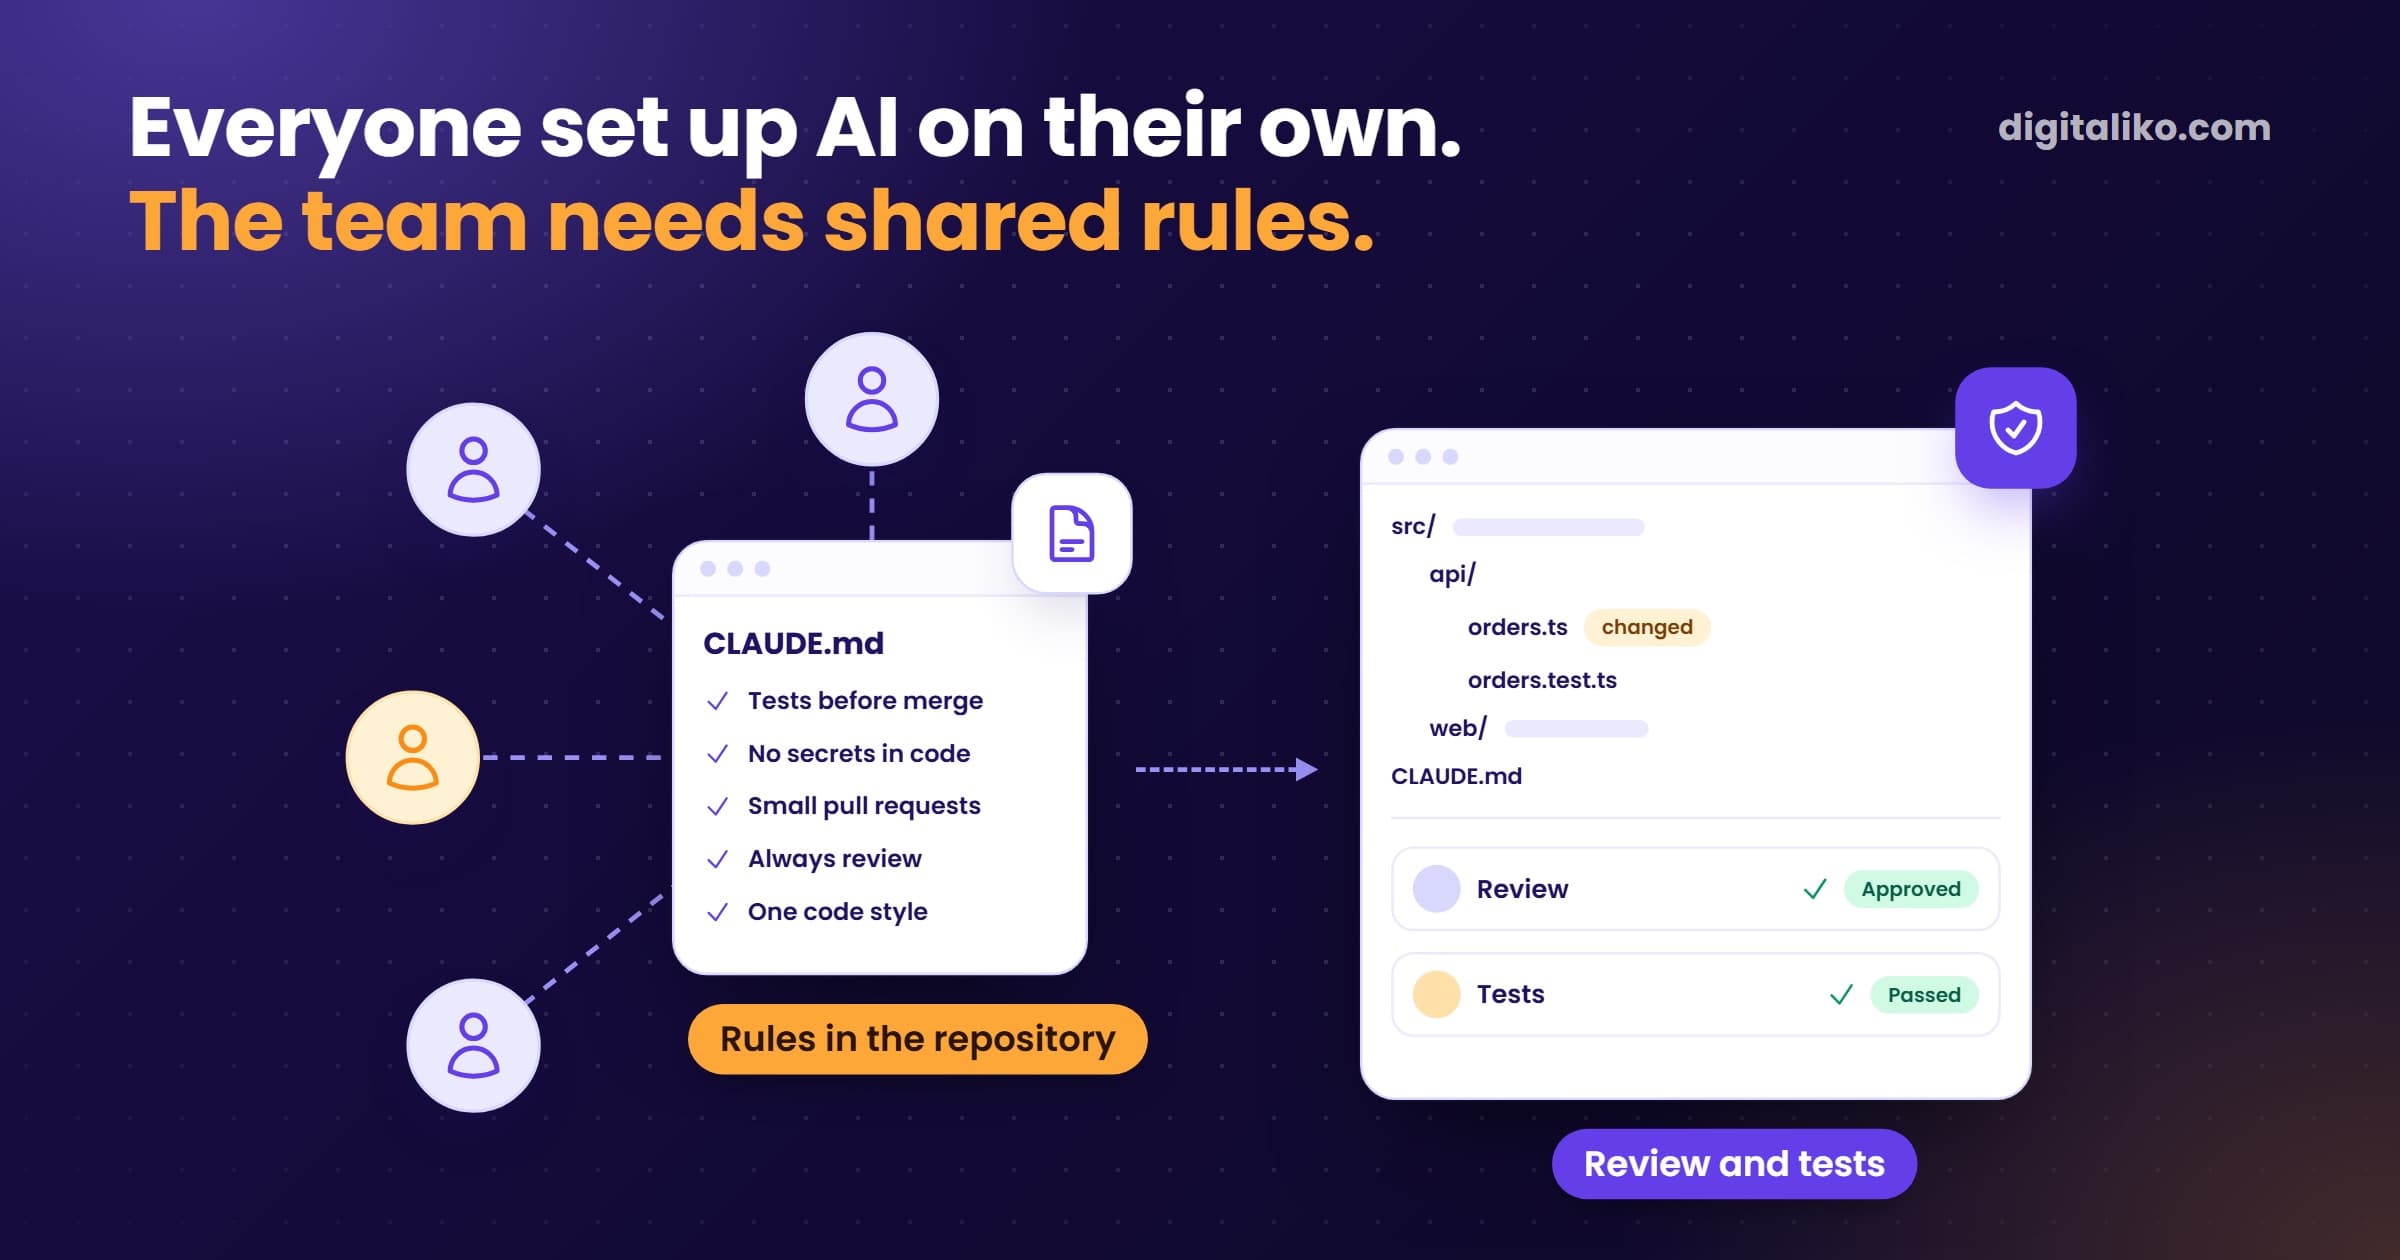
How to introduce AI into a development team

You introduce AI into a development team through shared rules in the repository, review by someone other than the author and one owner, not by picking a tool. A plan for the first 30 days.

Harness and checks

Harness and checks

Playwright MCP: let the AI agent prove it works

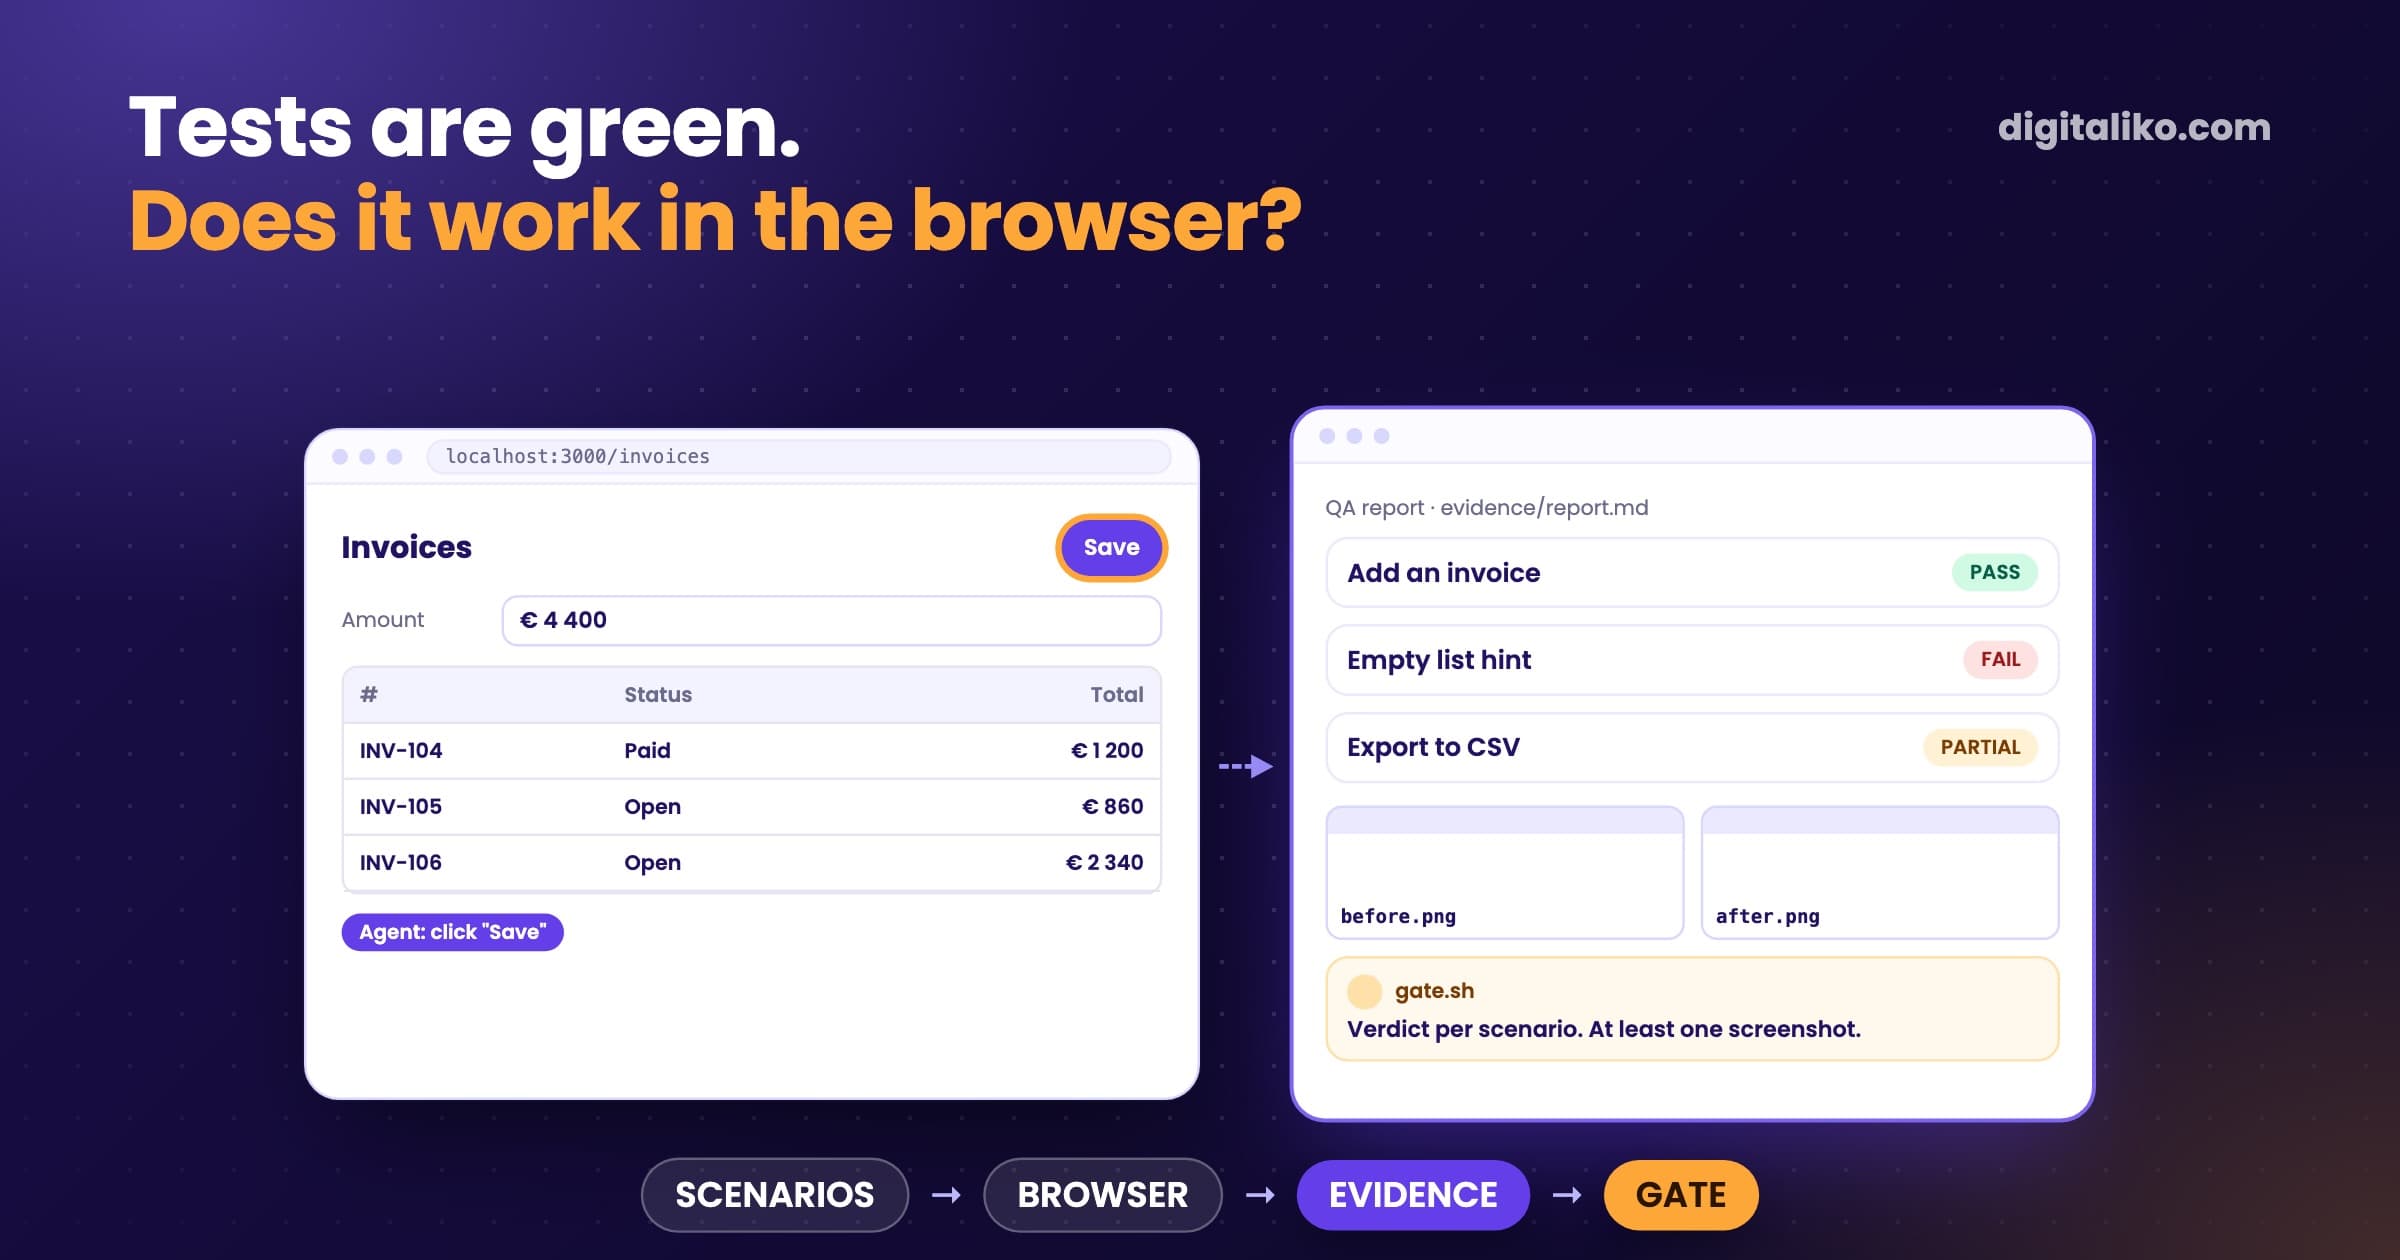
Playwright MCP gives an AI agent a real browser. How we use it so the agent checks its own change in the running app and hands back PASS or FAIL with screenshots, what it catches that unit tests miss, and when plain Playwright scripts are the better tool.

Harness and checks

LLM as a judge: a reviewer that tries to refute the work

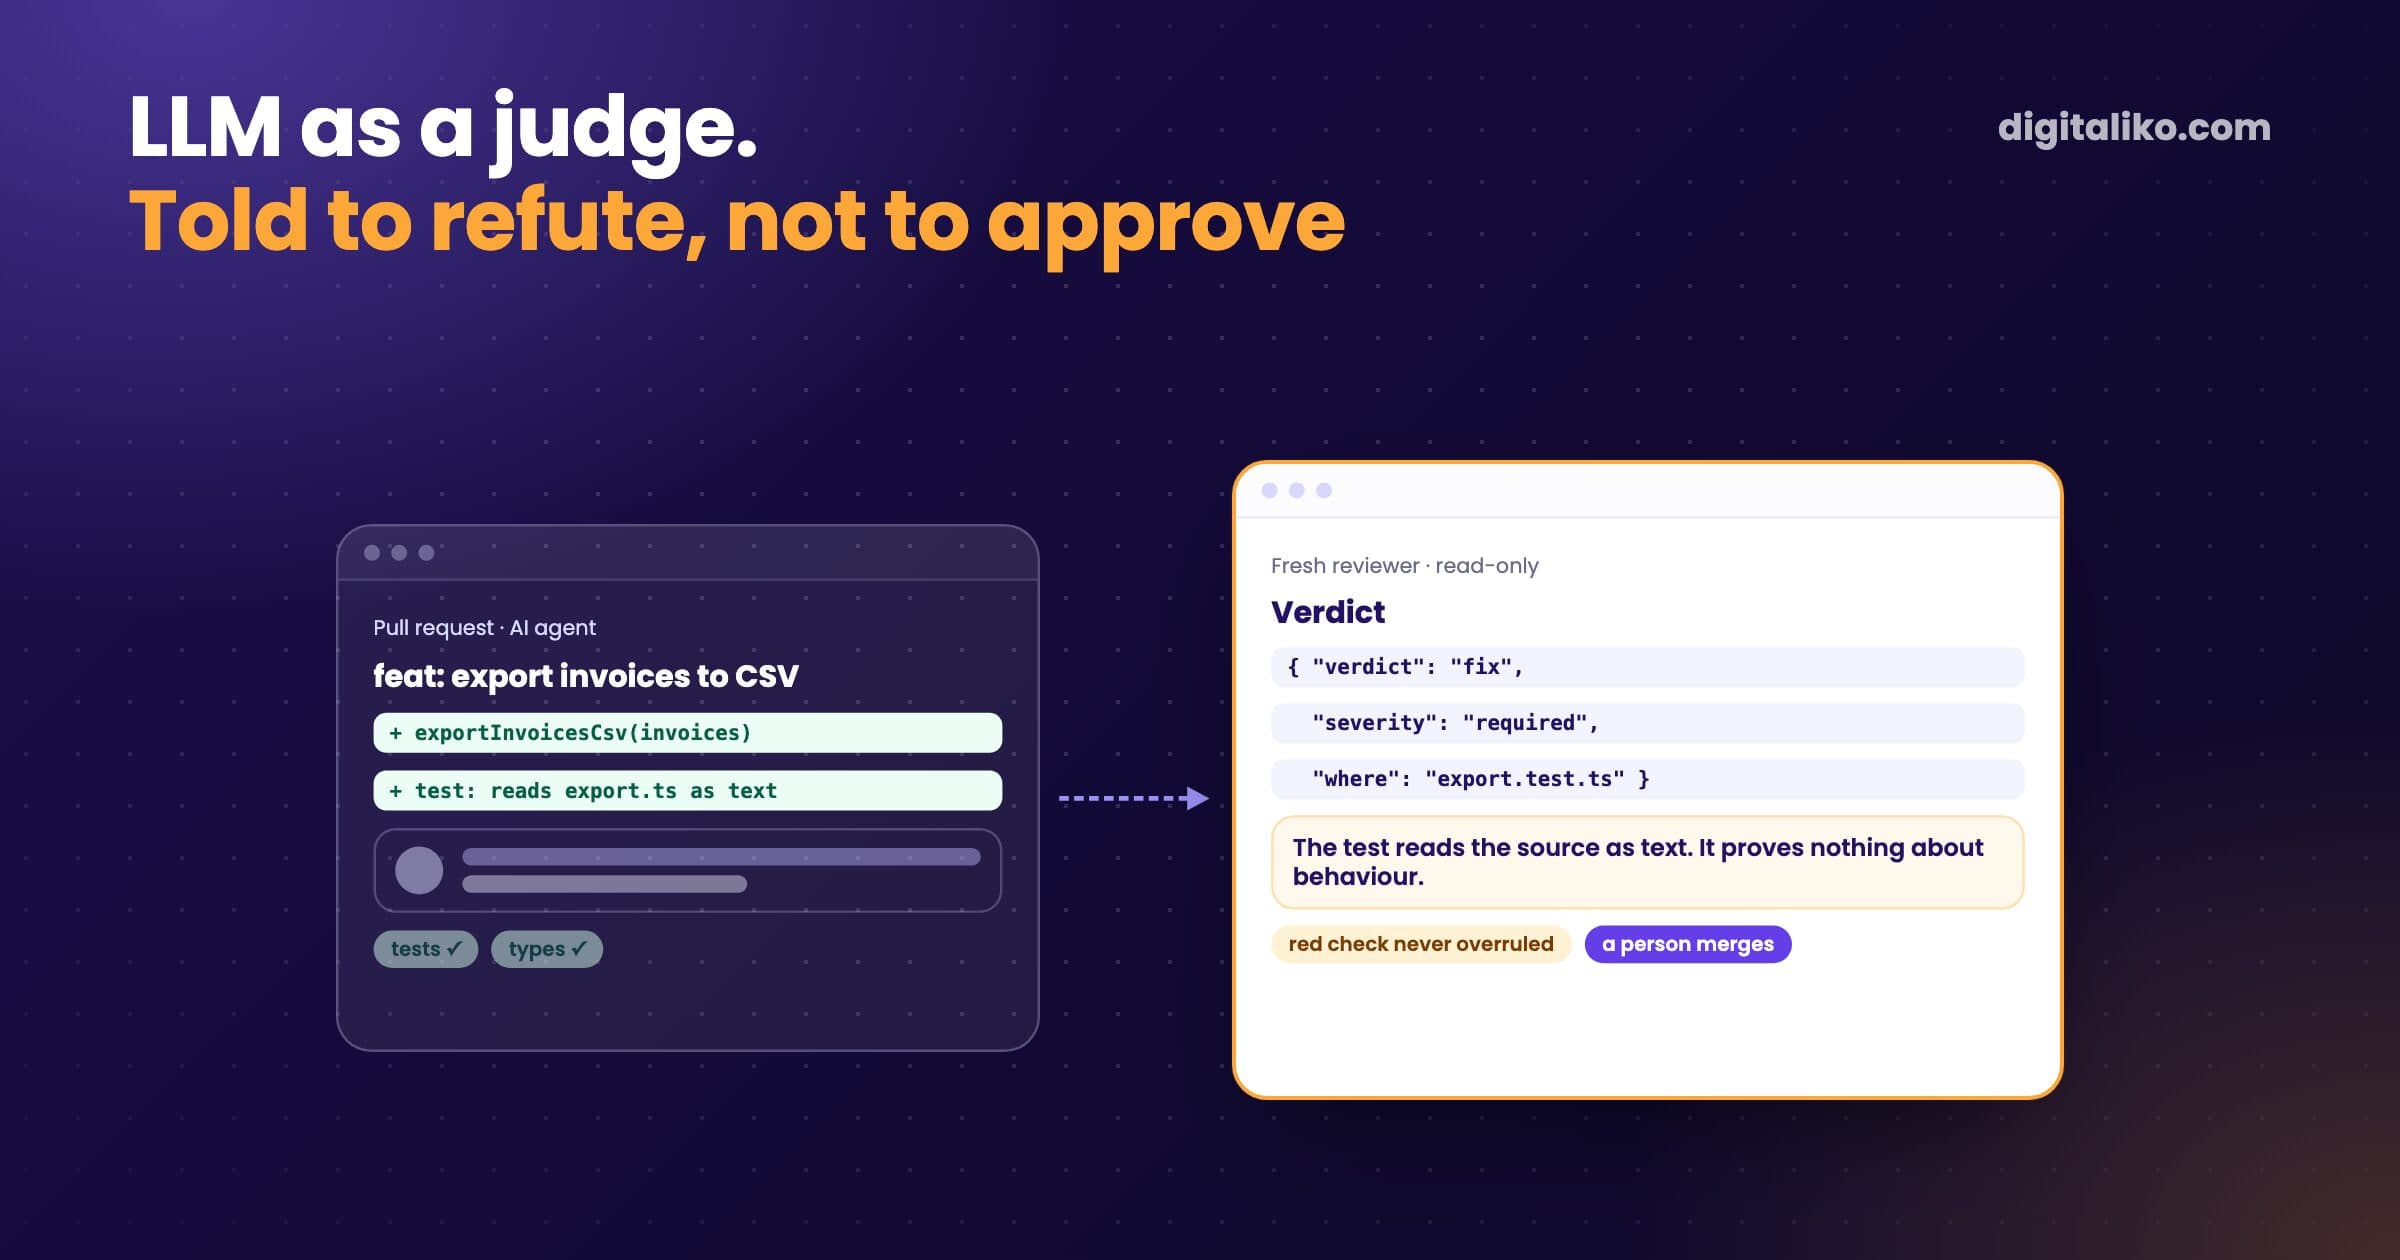
LLM as a judge means a language model grades another model's work against written criteria. How we run one on every pull request our AI agent opens: machine checks first, a fresh read-only session told to refute, a typed verdict, and the rules we added after the judge got it wrong.

Harness and checks

Claude Code review in CI: what AI code review misses

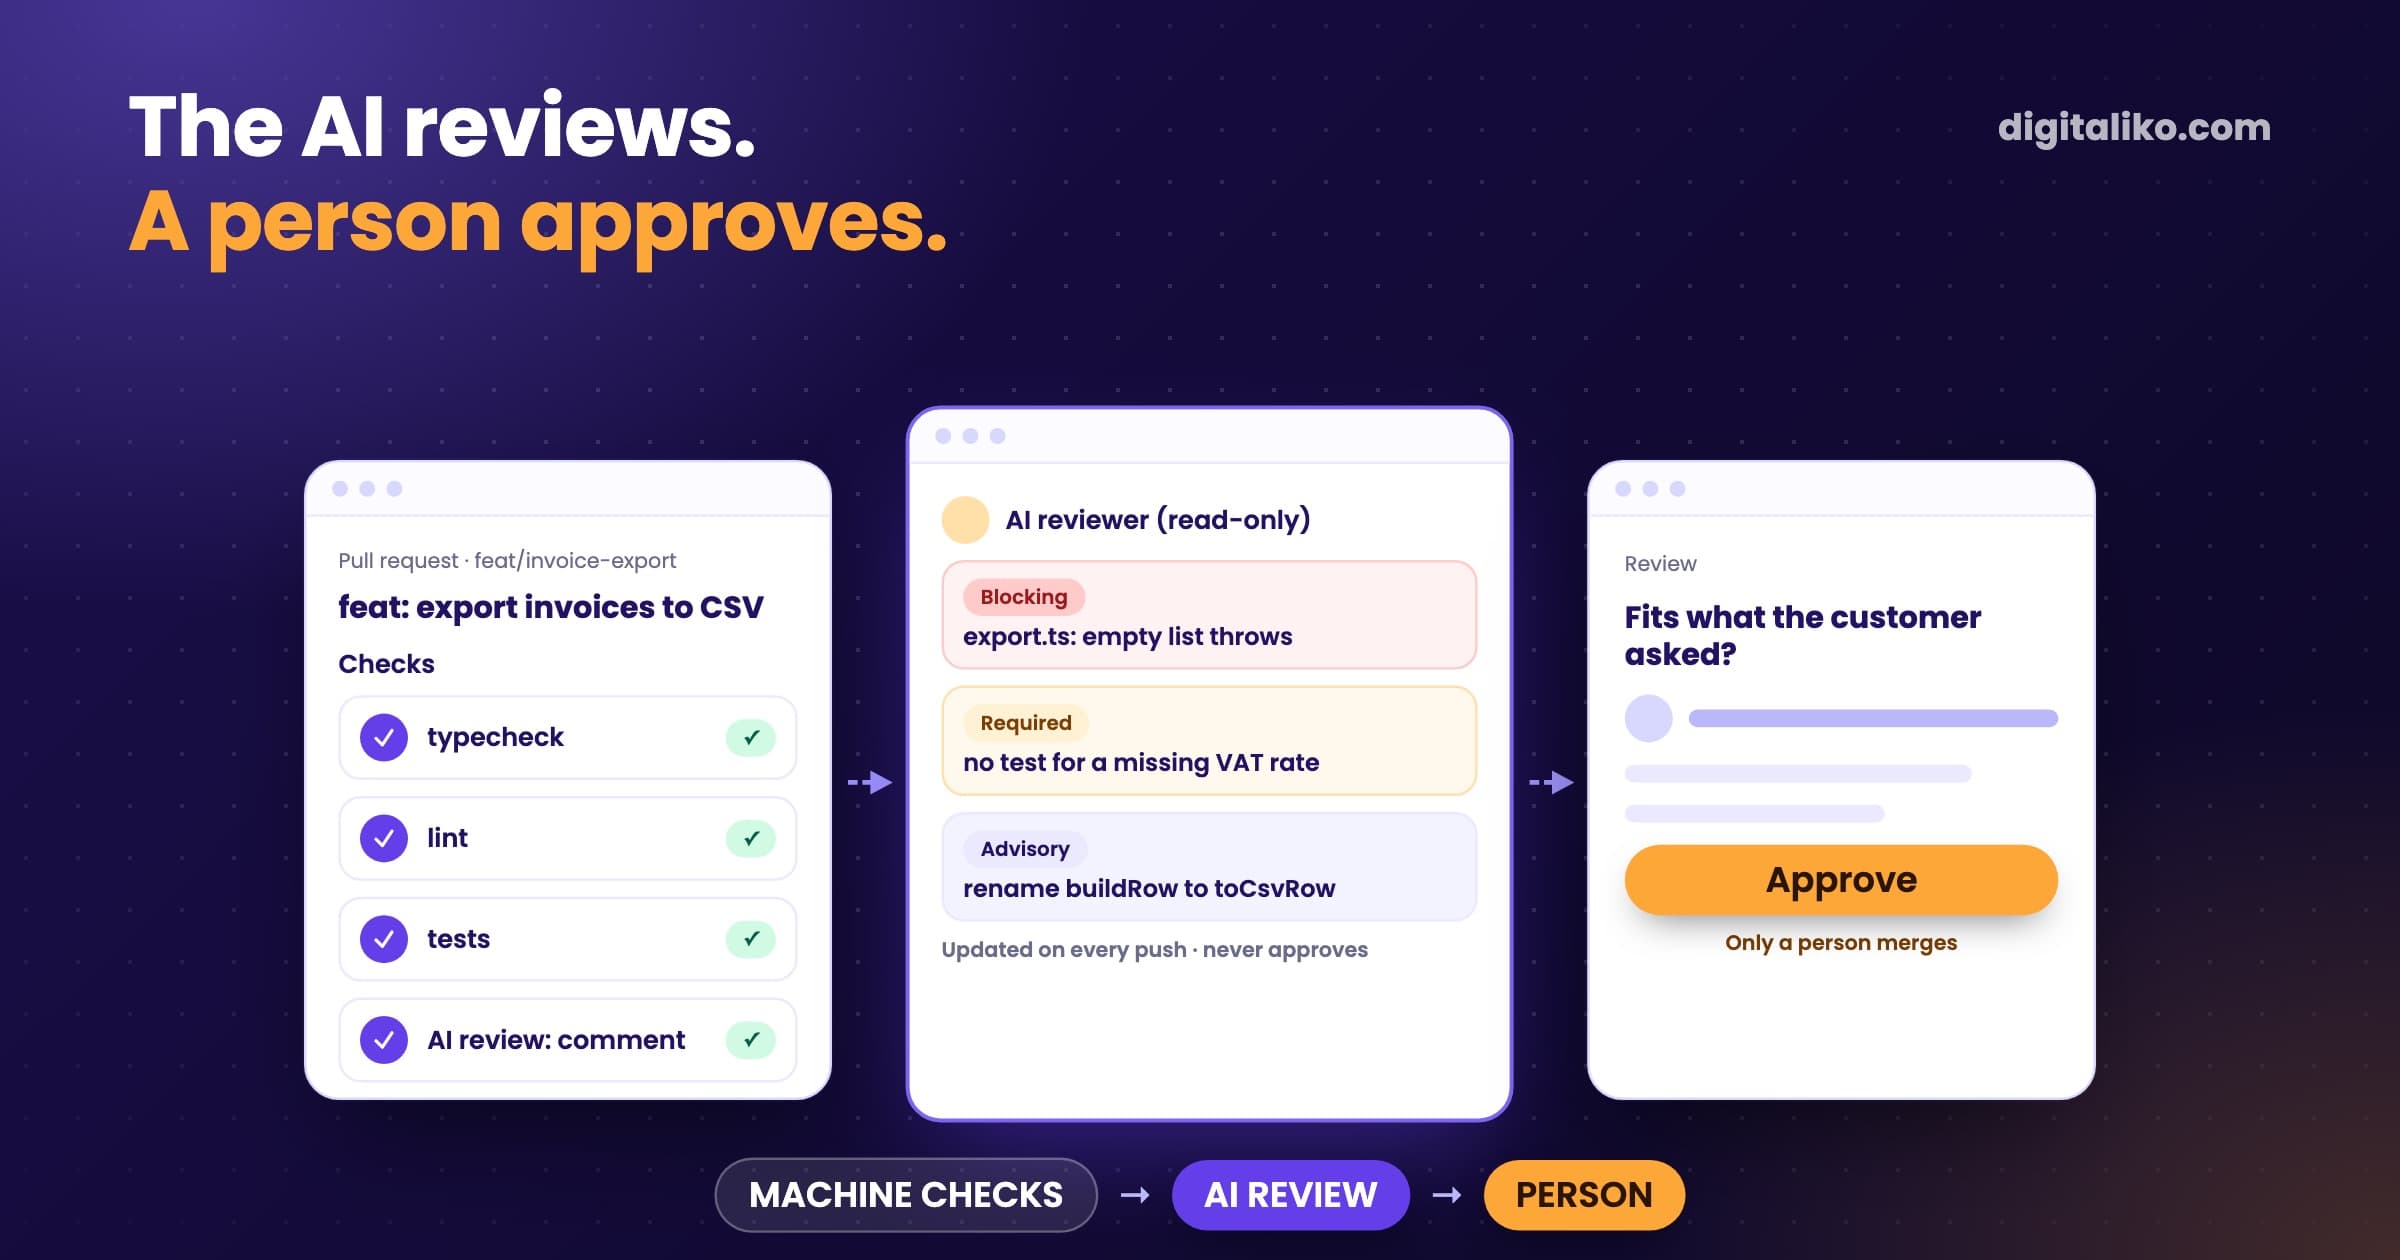
How we run Claude Code review on every pull request with one reusable GitHub Action: what the AI reviewer is told to look for, how it stayed green and silent, what it misses, and why only a person approves.

Harness and checks

Claude Code hooks that silently do nothing

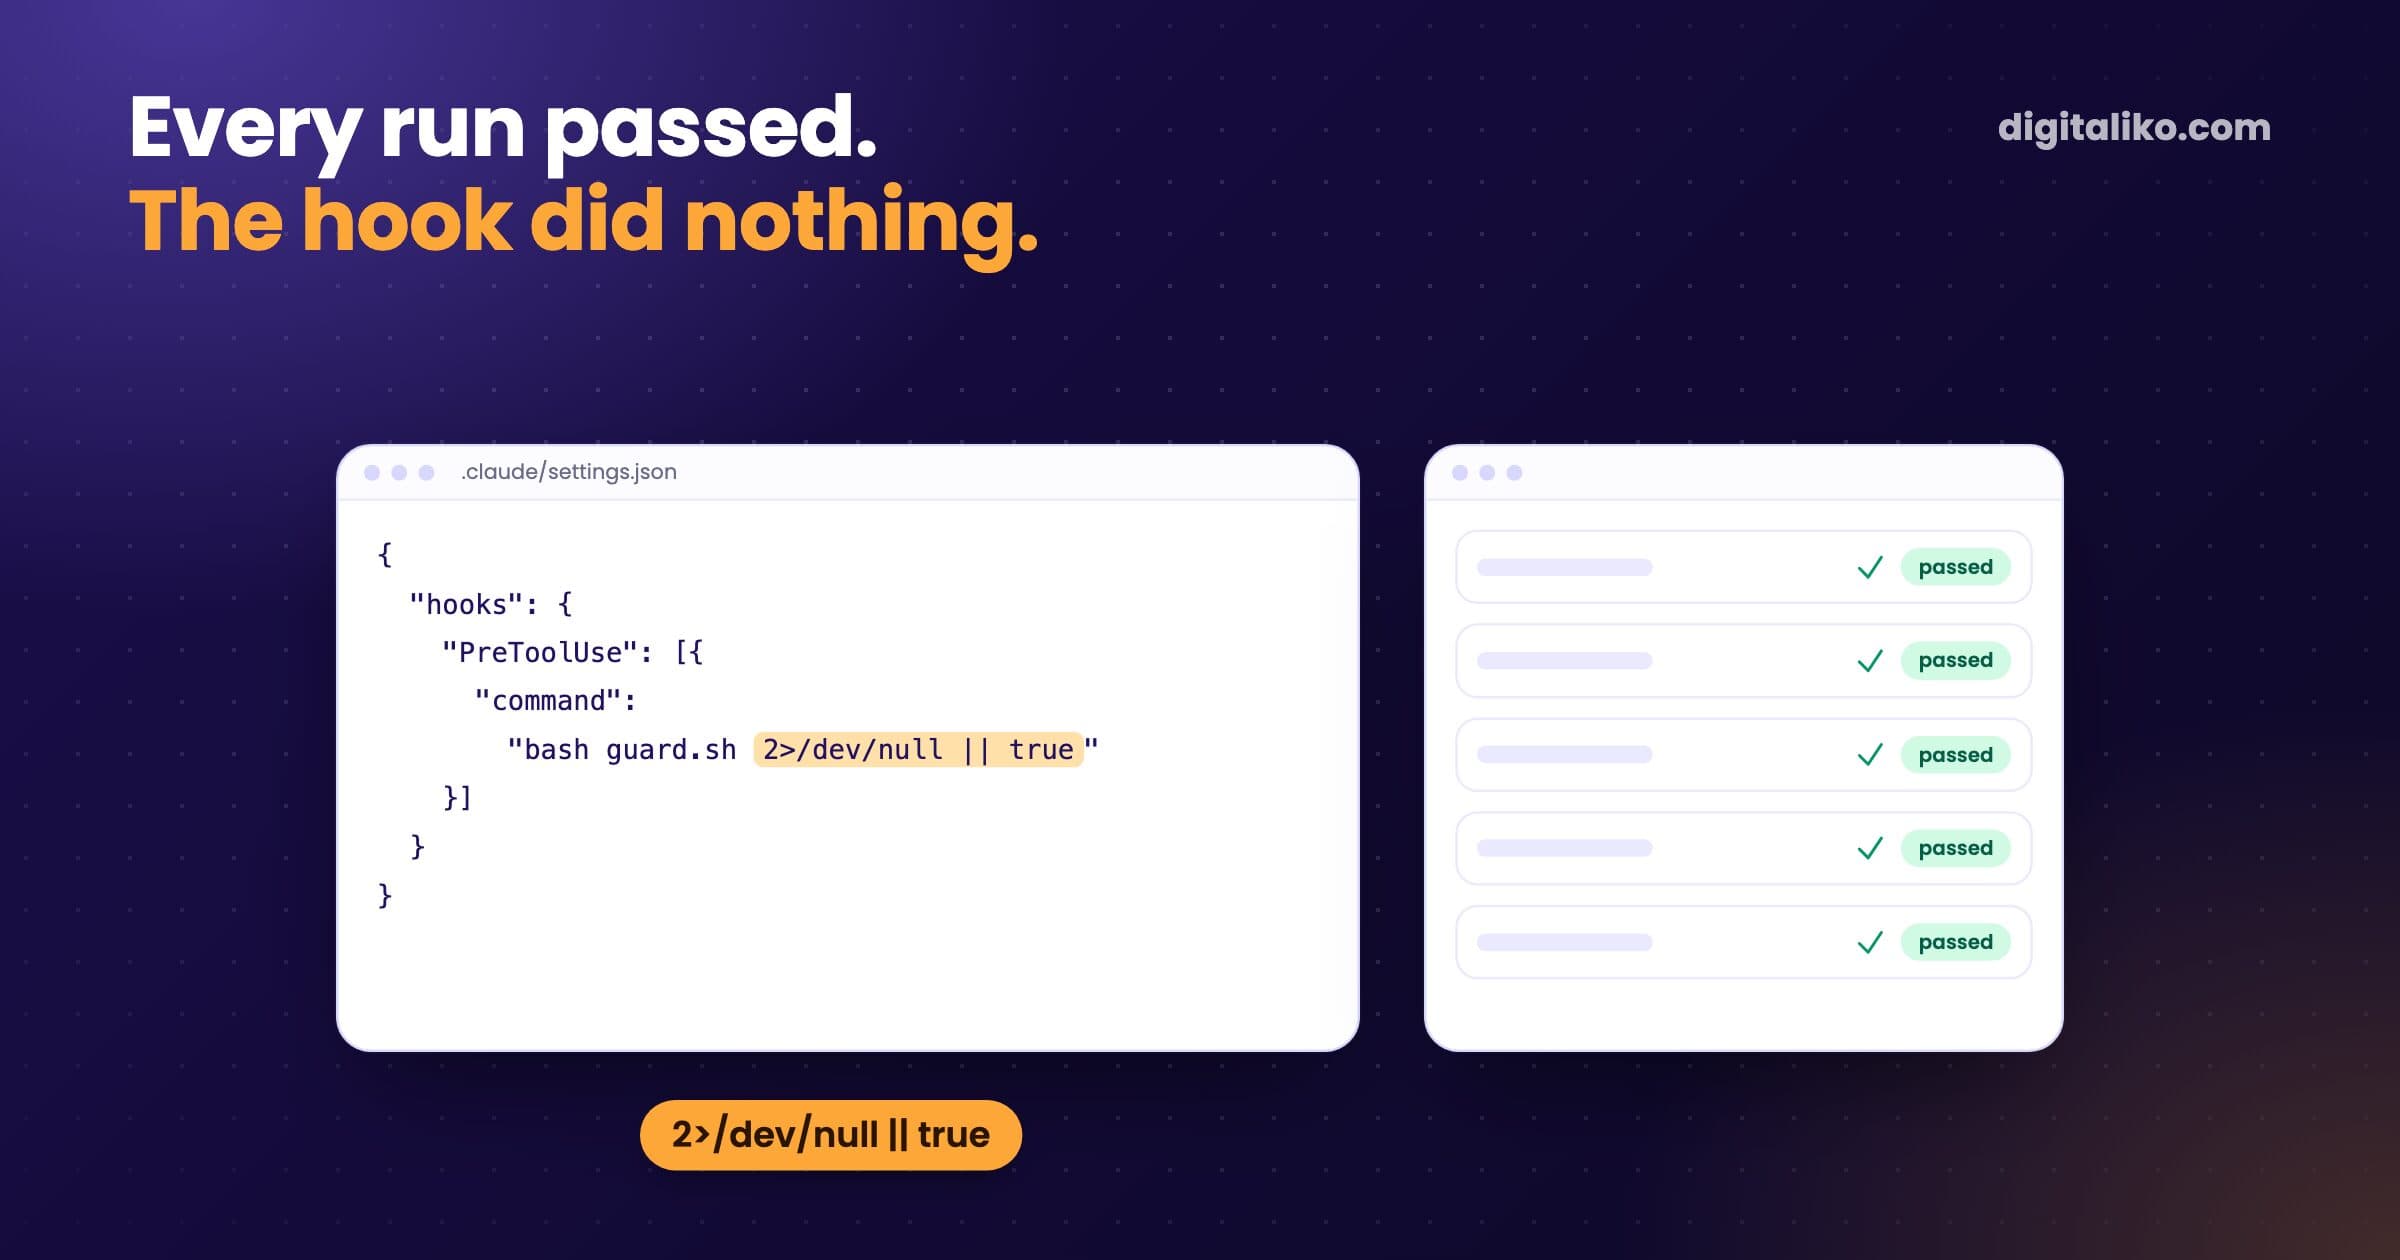
A Claude Code hook can pass on every run and still do nothing: stderr sent to /dev/null, a relative path, a trailing || true. Four checks that catch it, and the Stop hook that blocks "done" while tests are red.

Harness and checks

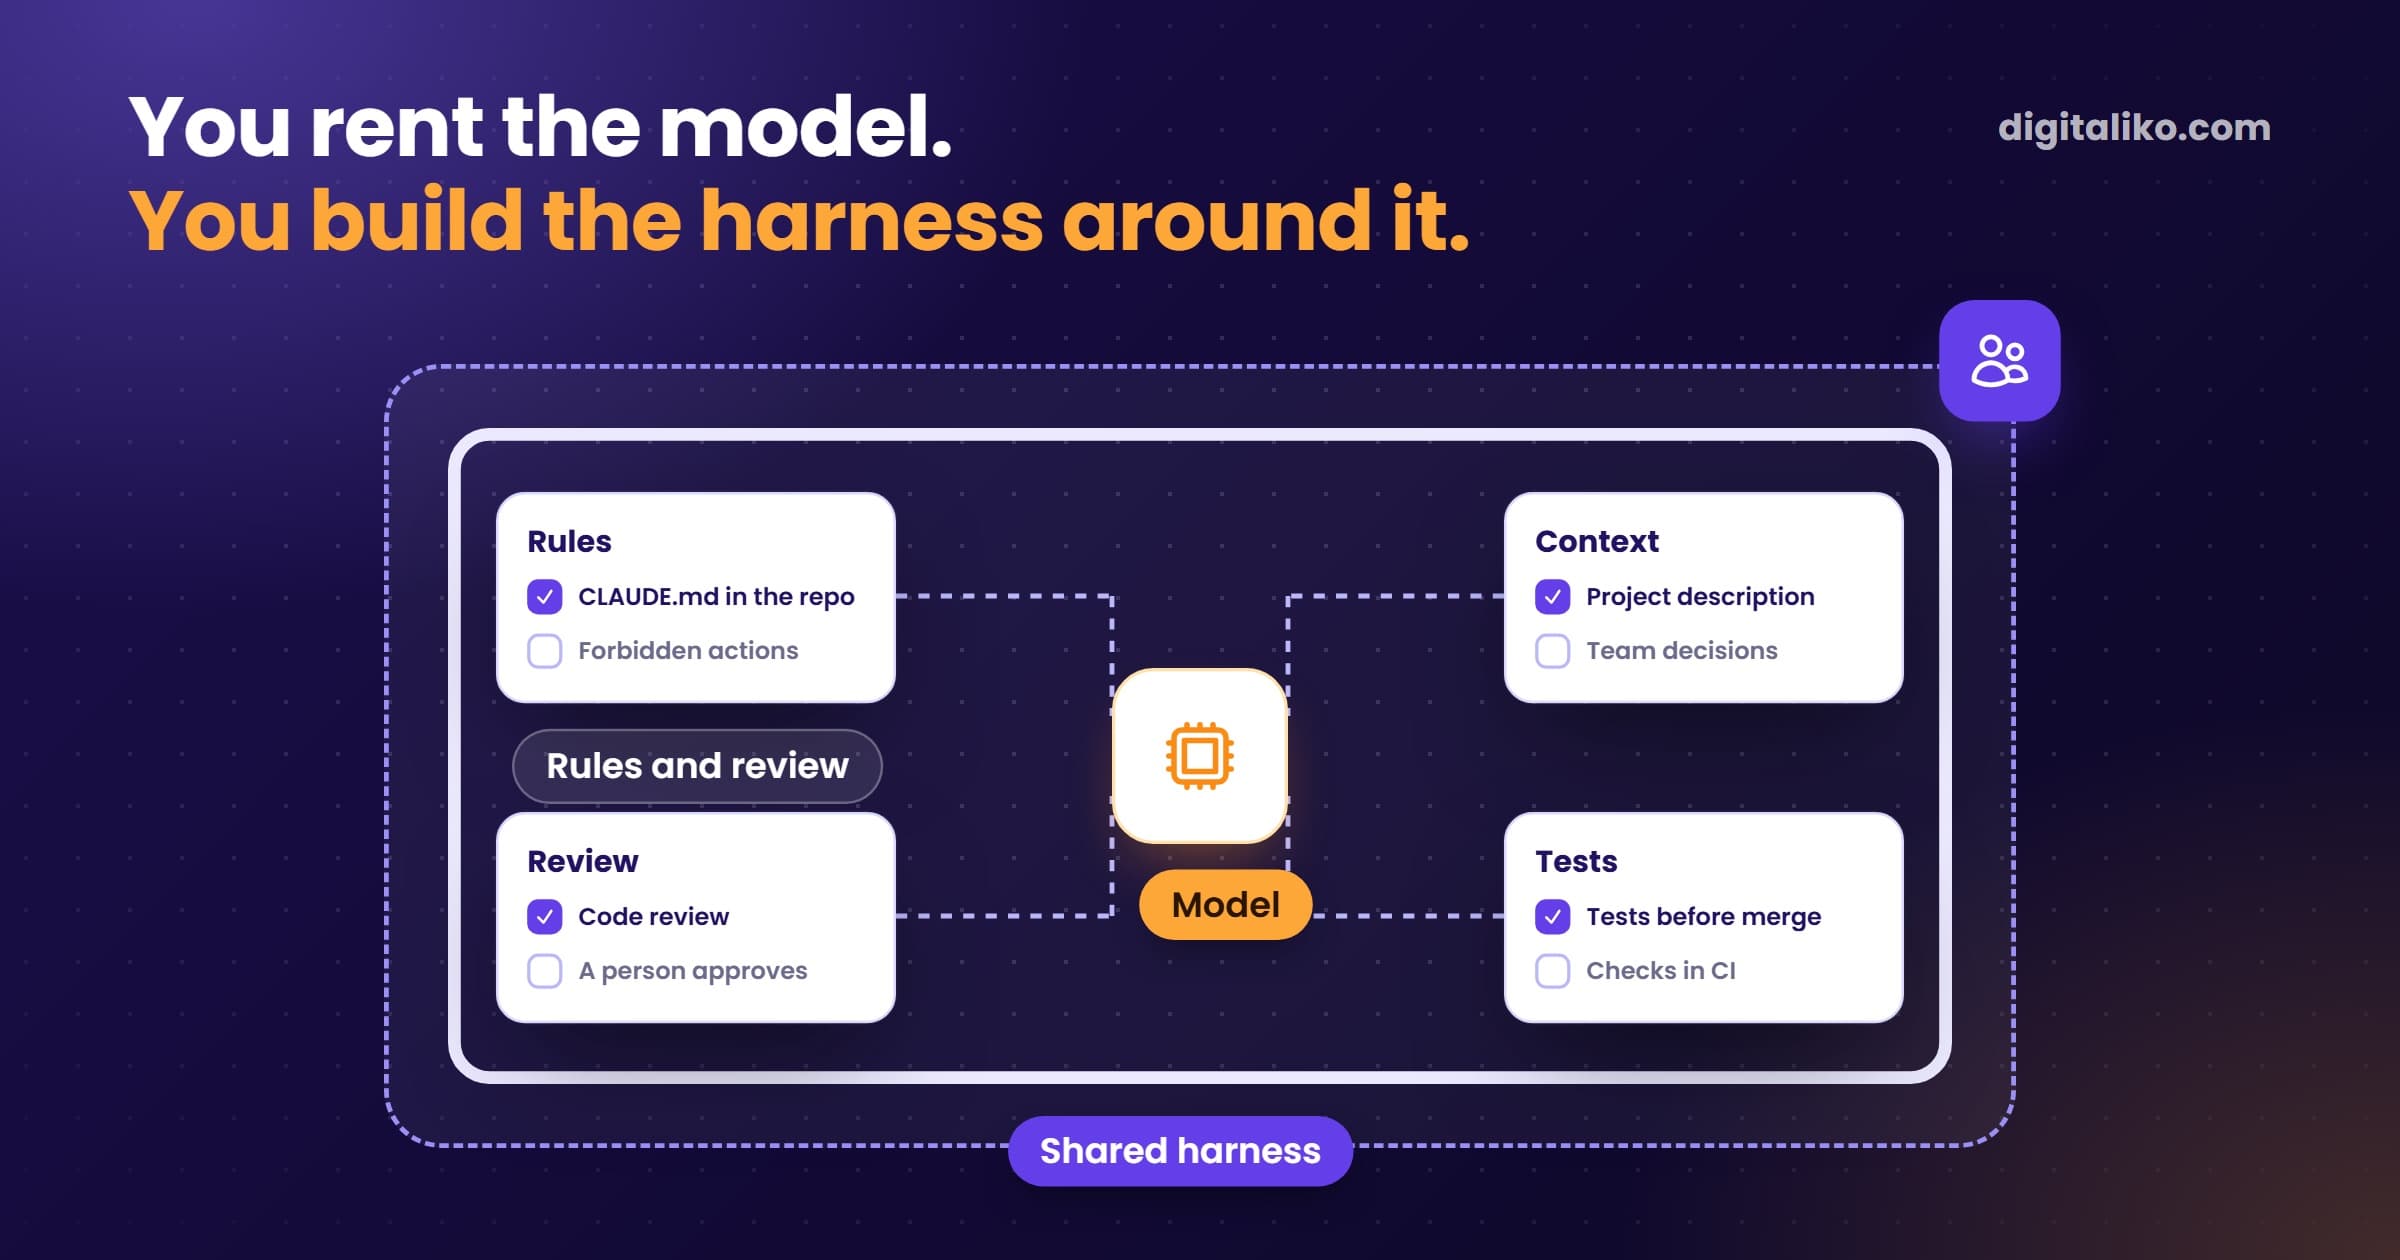
What is an agent harness? Agent = model + harness

An agent harness is everything around the AI model: rules, context, tools and checks. Why a shared harness for the team matters more than a better model, and how to start sharing rules.

Harness and checks

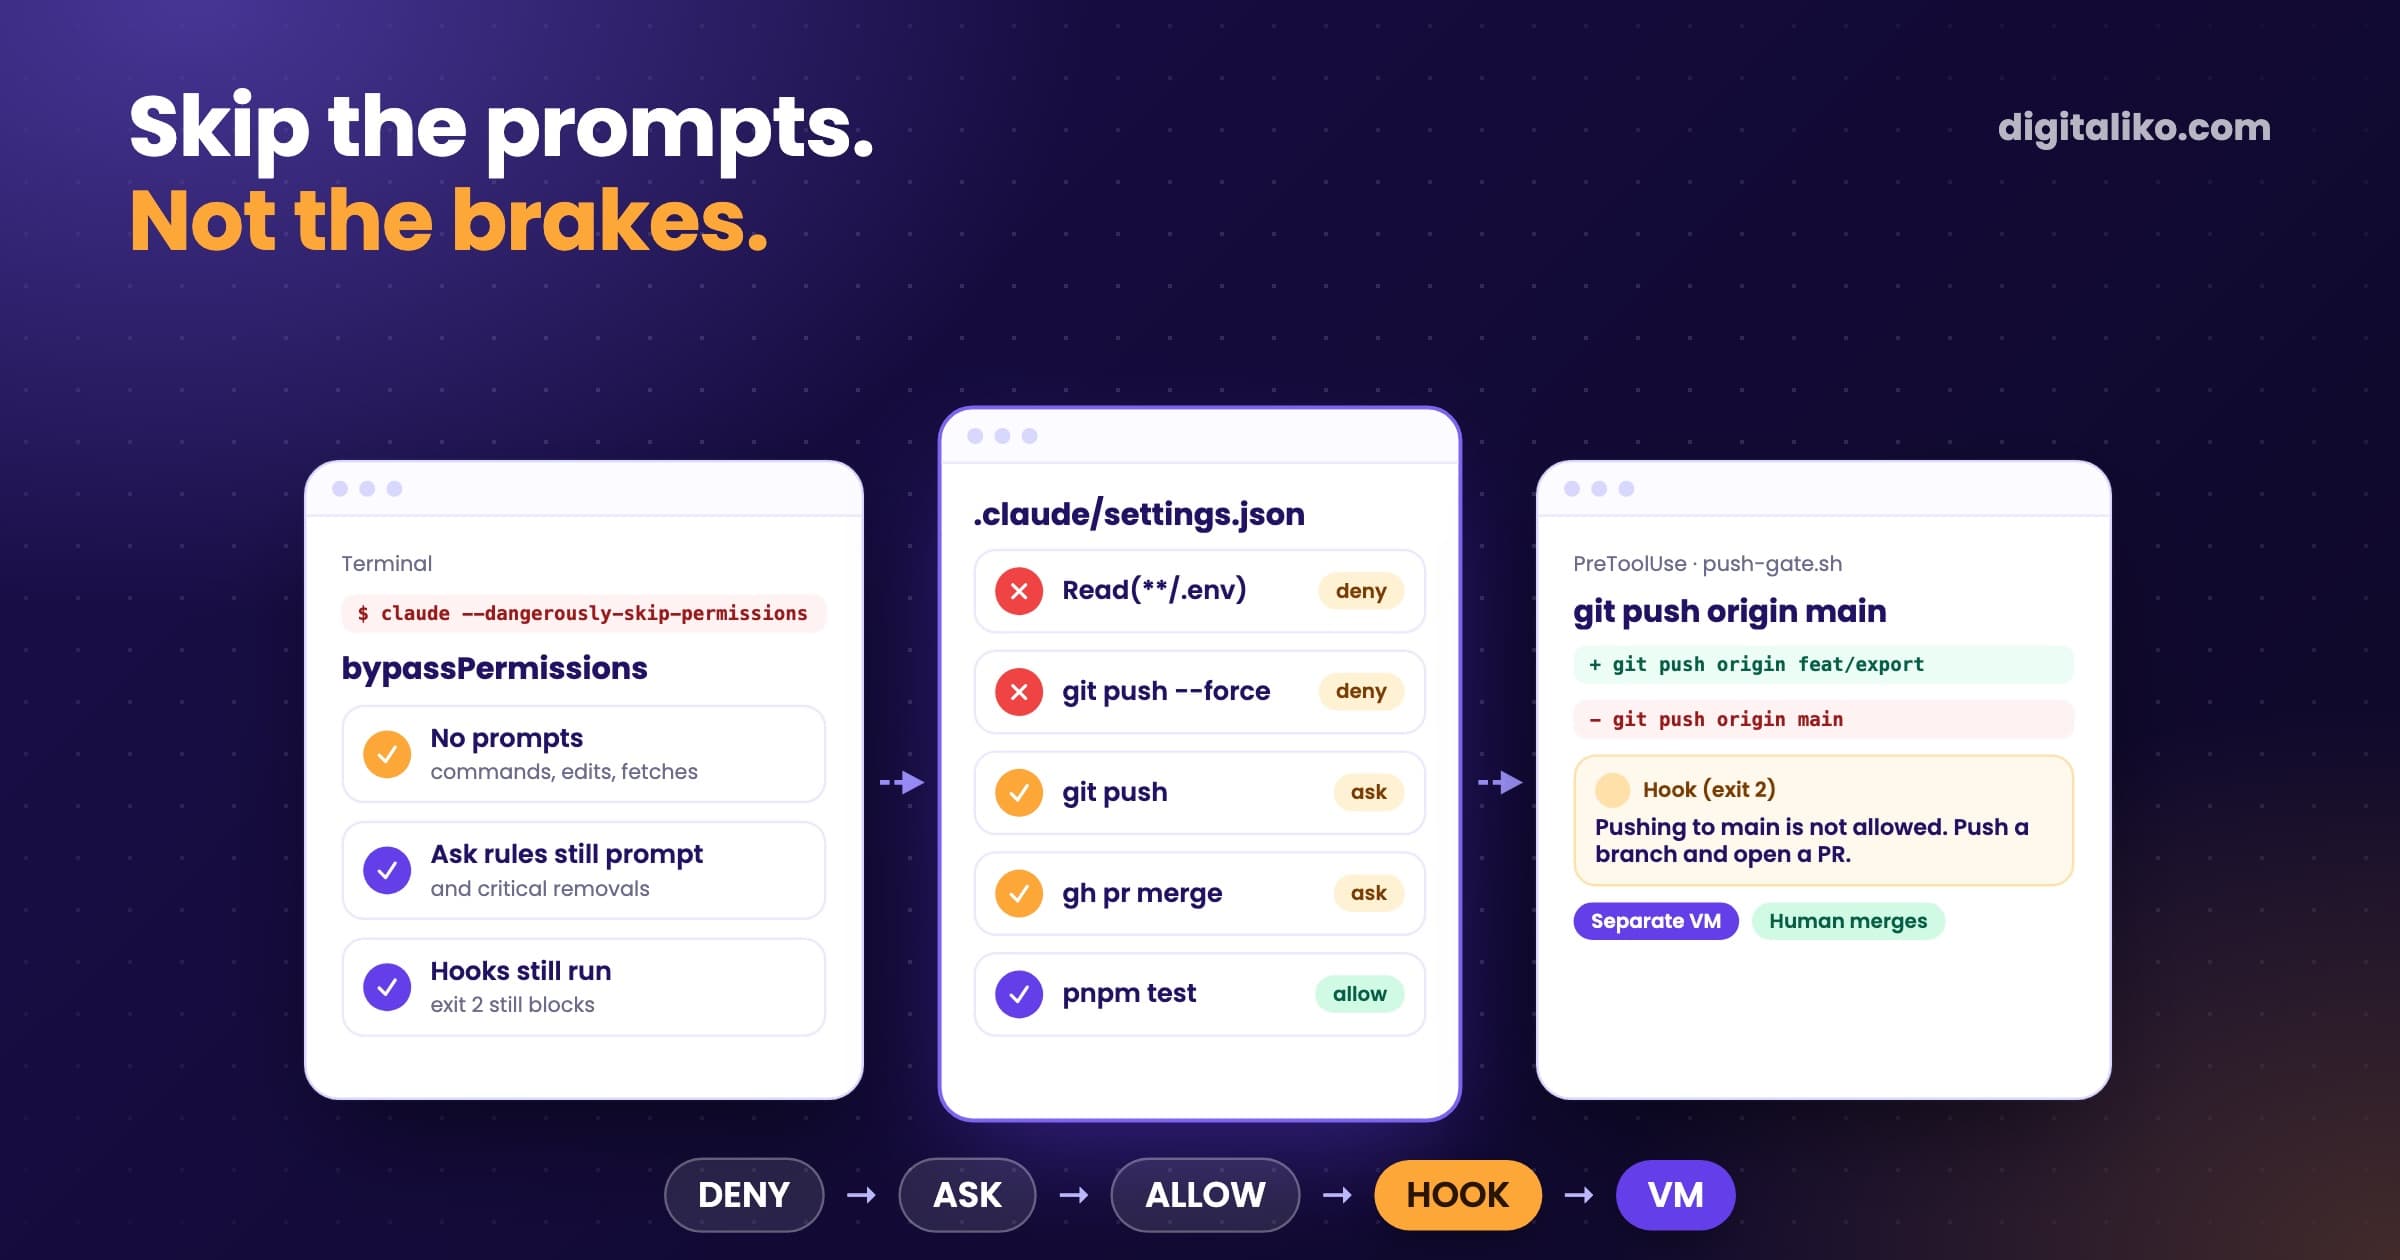
Claude Code dangerously-skip-permissions: when is it safe?

What --dangerously-skip-permissions really turns off, how allow, ask and deny rules decide, what a rule cannot see, and the three layers we use: rules on a laptop, hooks for what rules miss, full bypass only in an isolated box.

Harness and checks

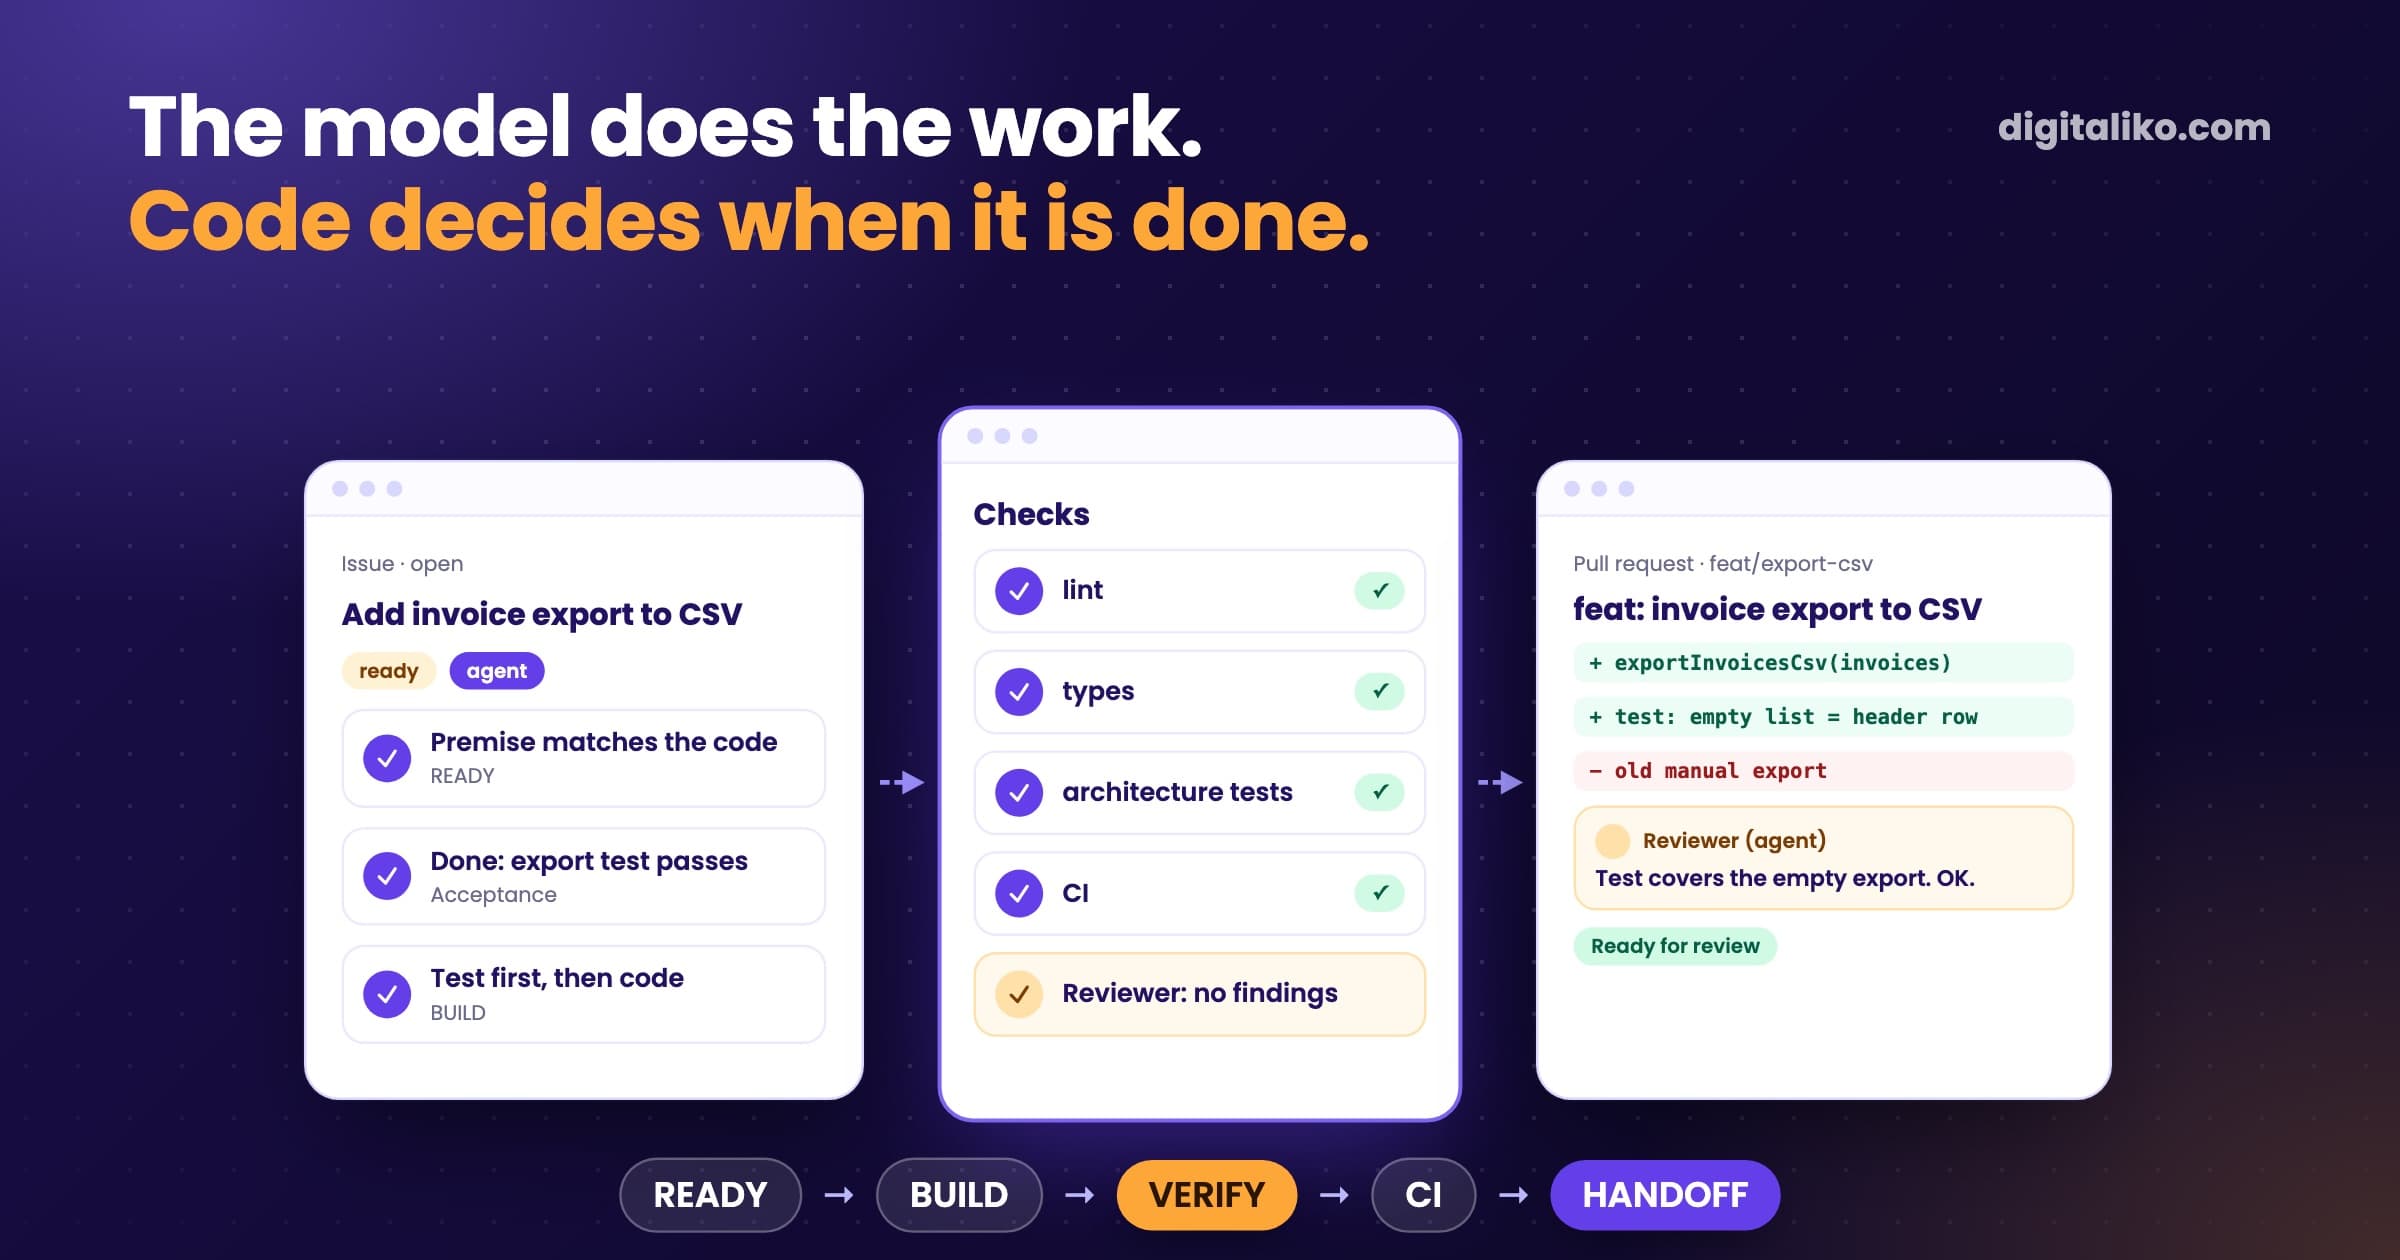
Harness engineering in practice: from issue to PR

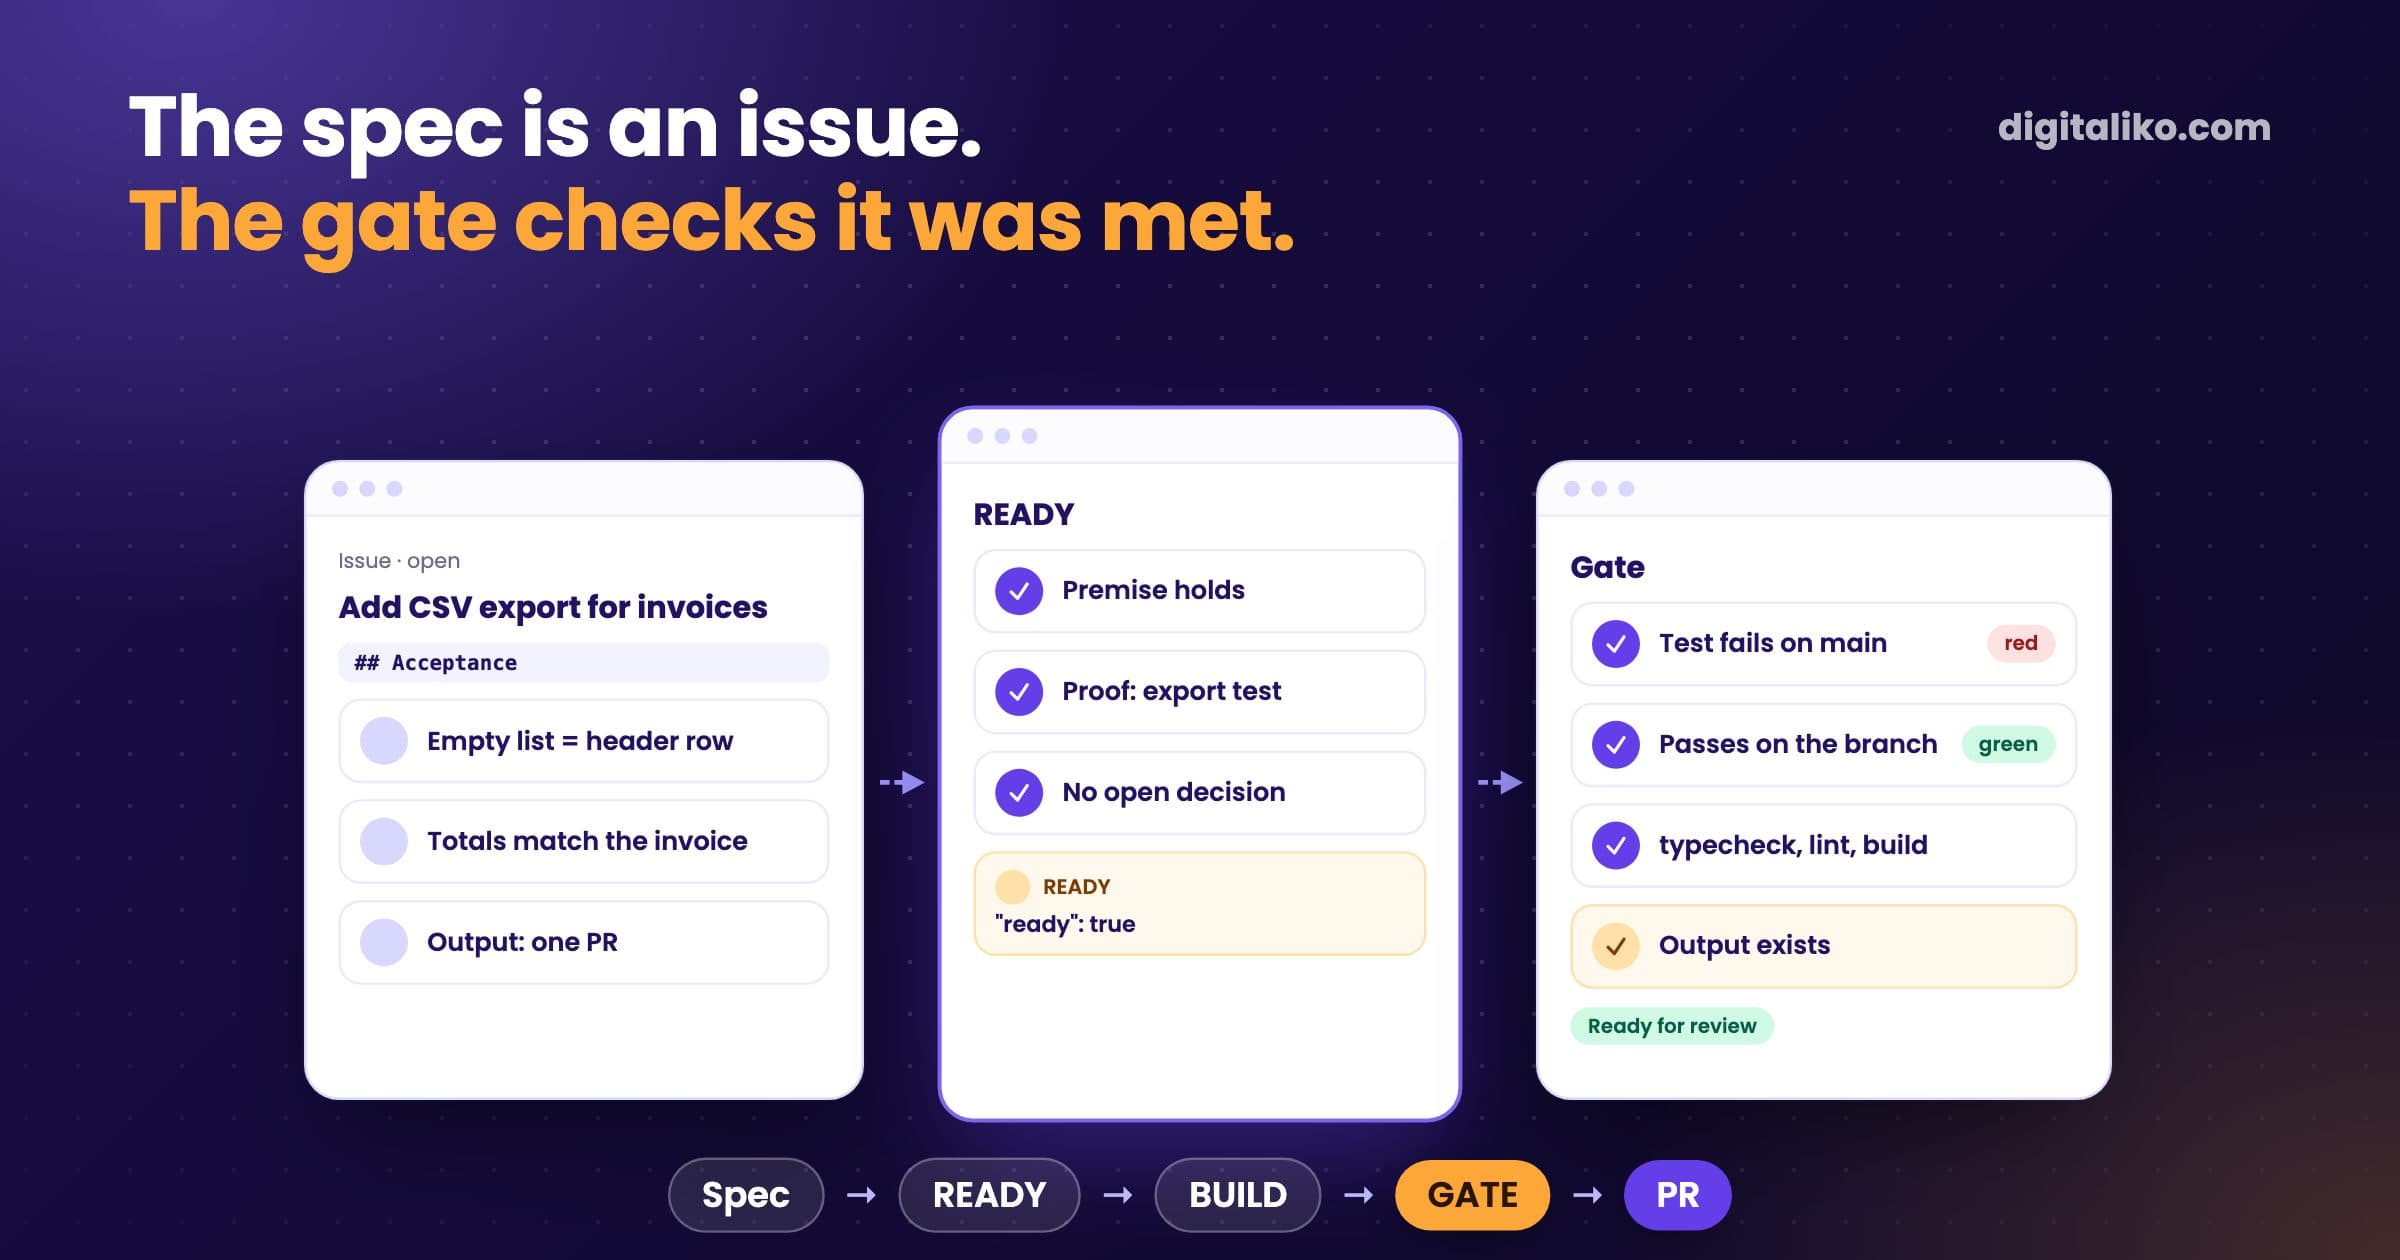
Harness engineering in practice: the code around an AI agent that decides what it takes, when it is done and who checks it. Our loop from a GitHub issue to a reviewed PR, the code that carries it, and what broke.

Harness and checks

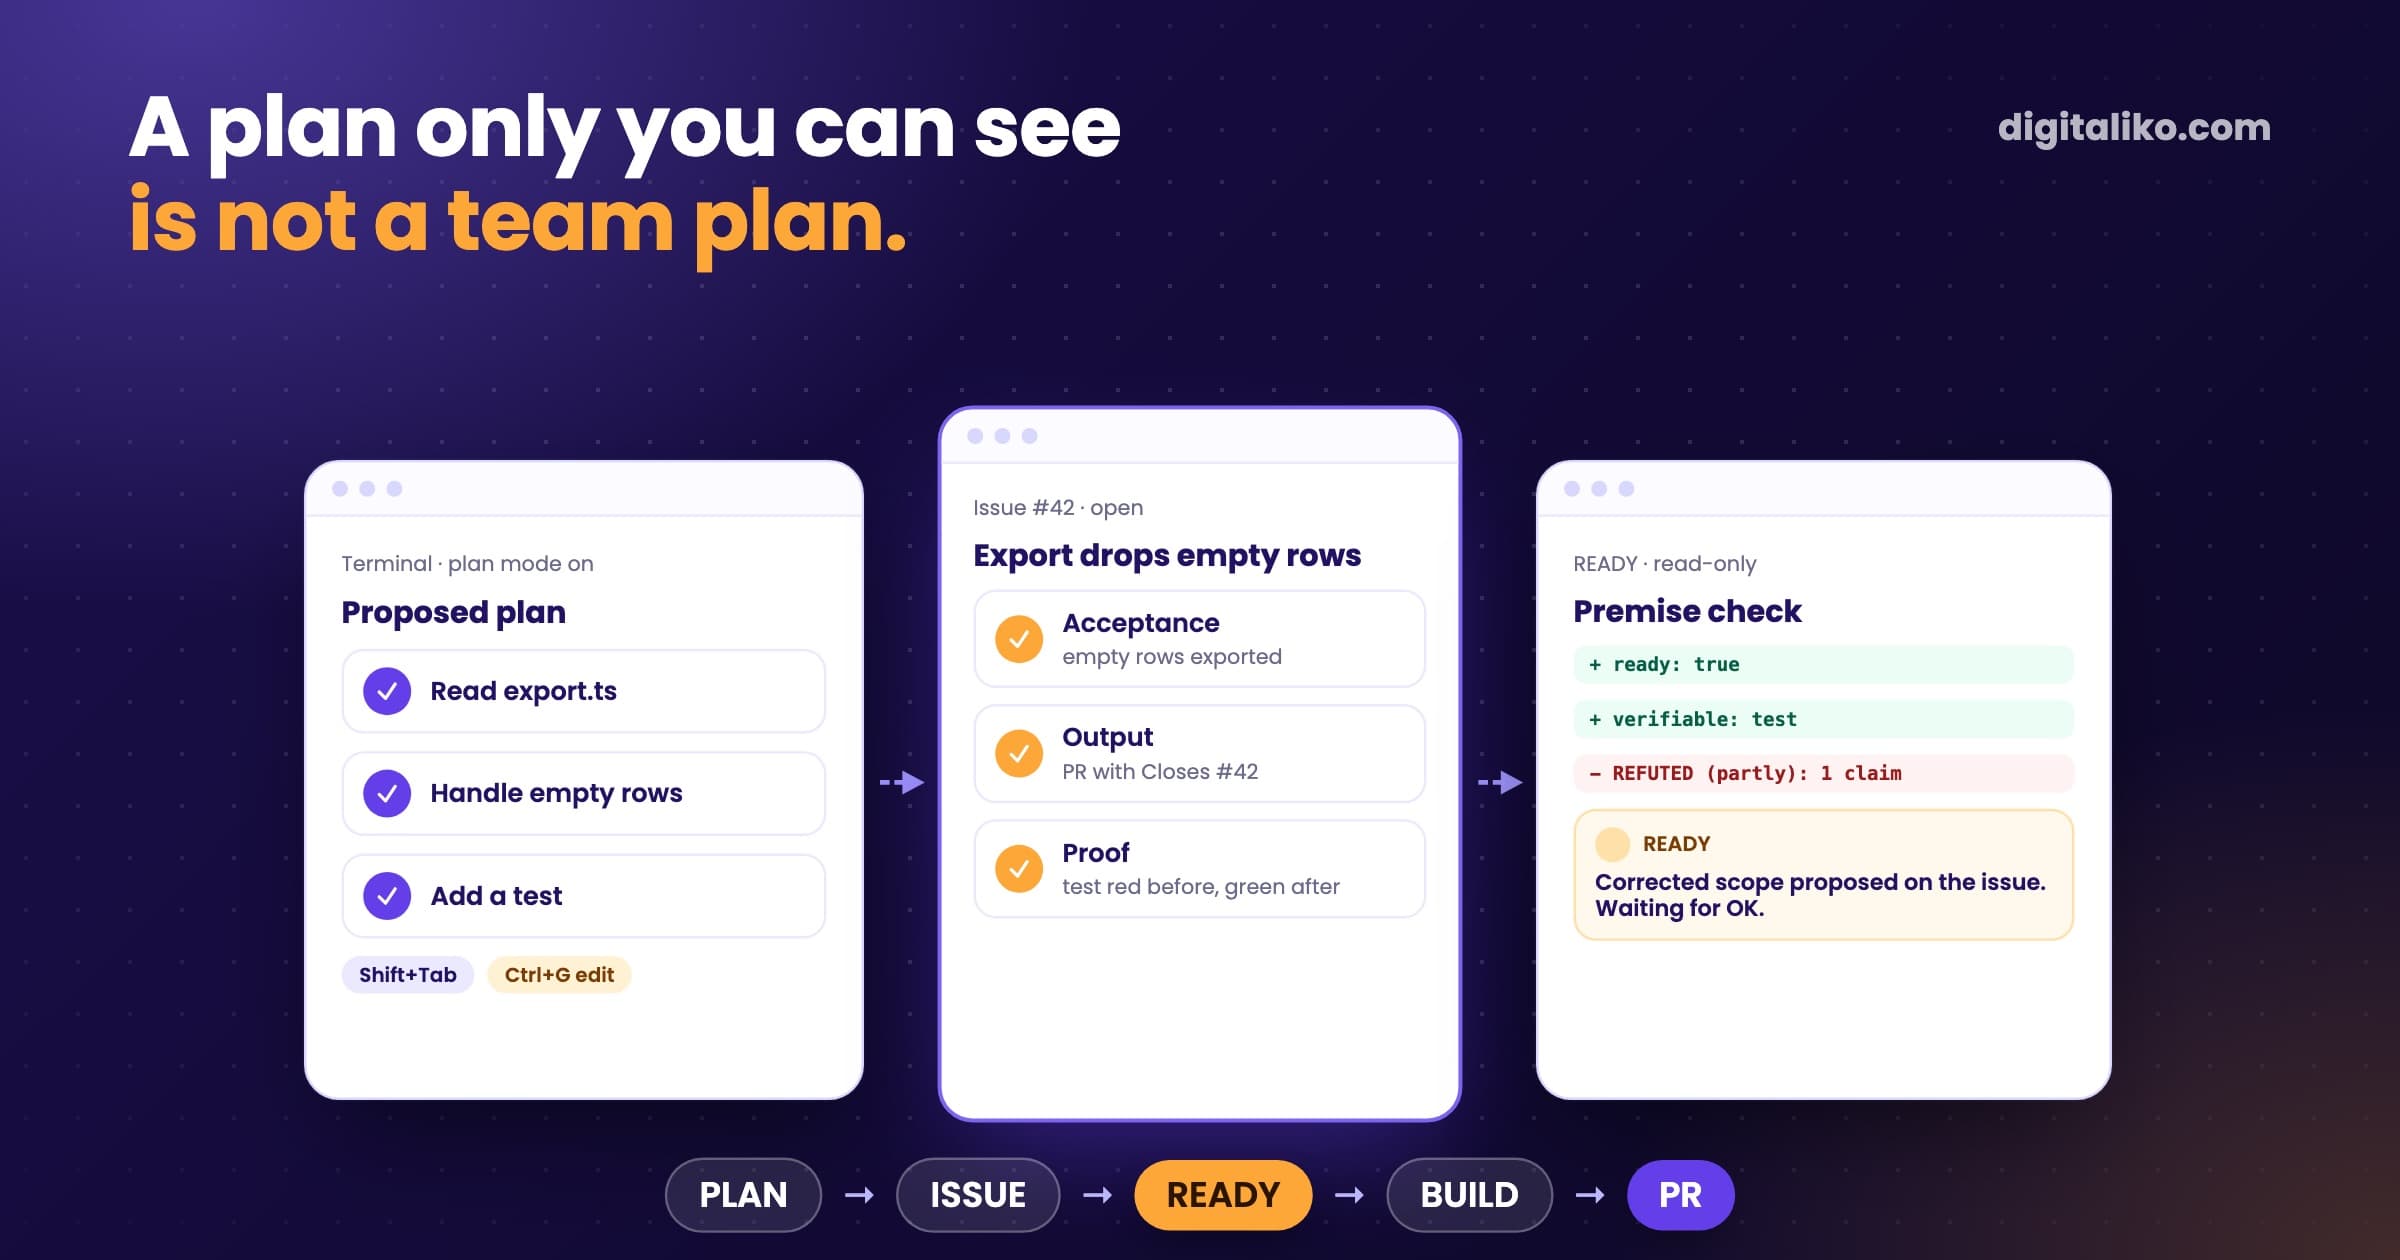
Claude Code plan mode: when is it enough for a team?

Claude Code plan mode explores the code and proposes a plan before any edit. That solves one session. In a team the plan has to outlive the session: ours lives in the GitHub issue, and a read-only check tests the premise against the code before anything is built.

Harness and checks

Red-green TDD with AI agents: the test must fail first

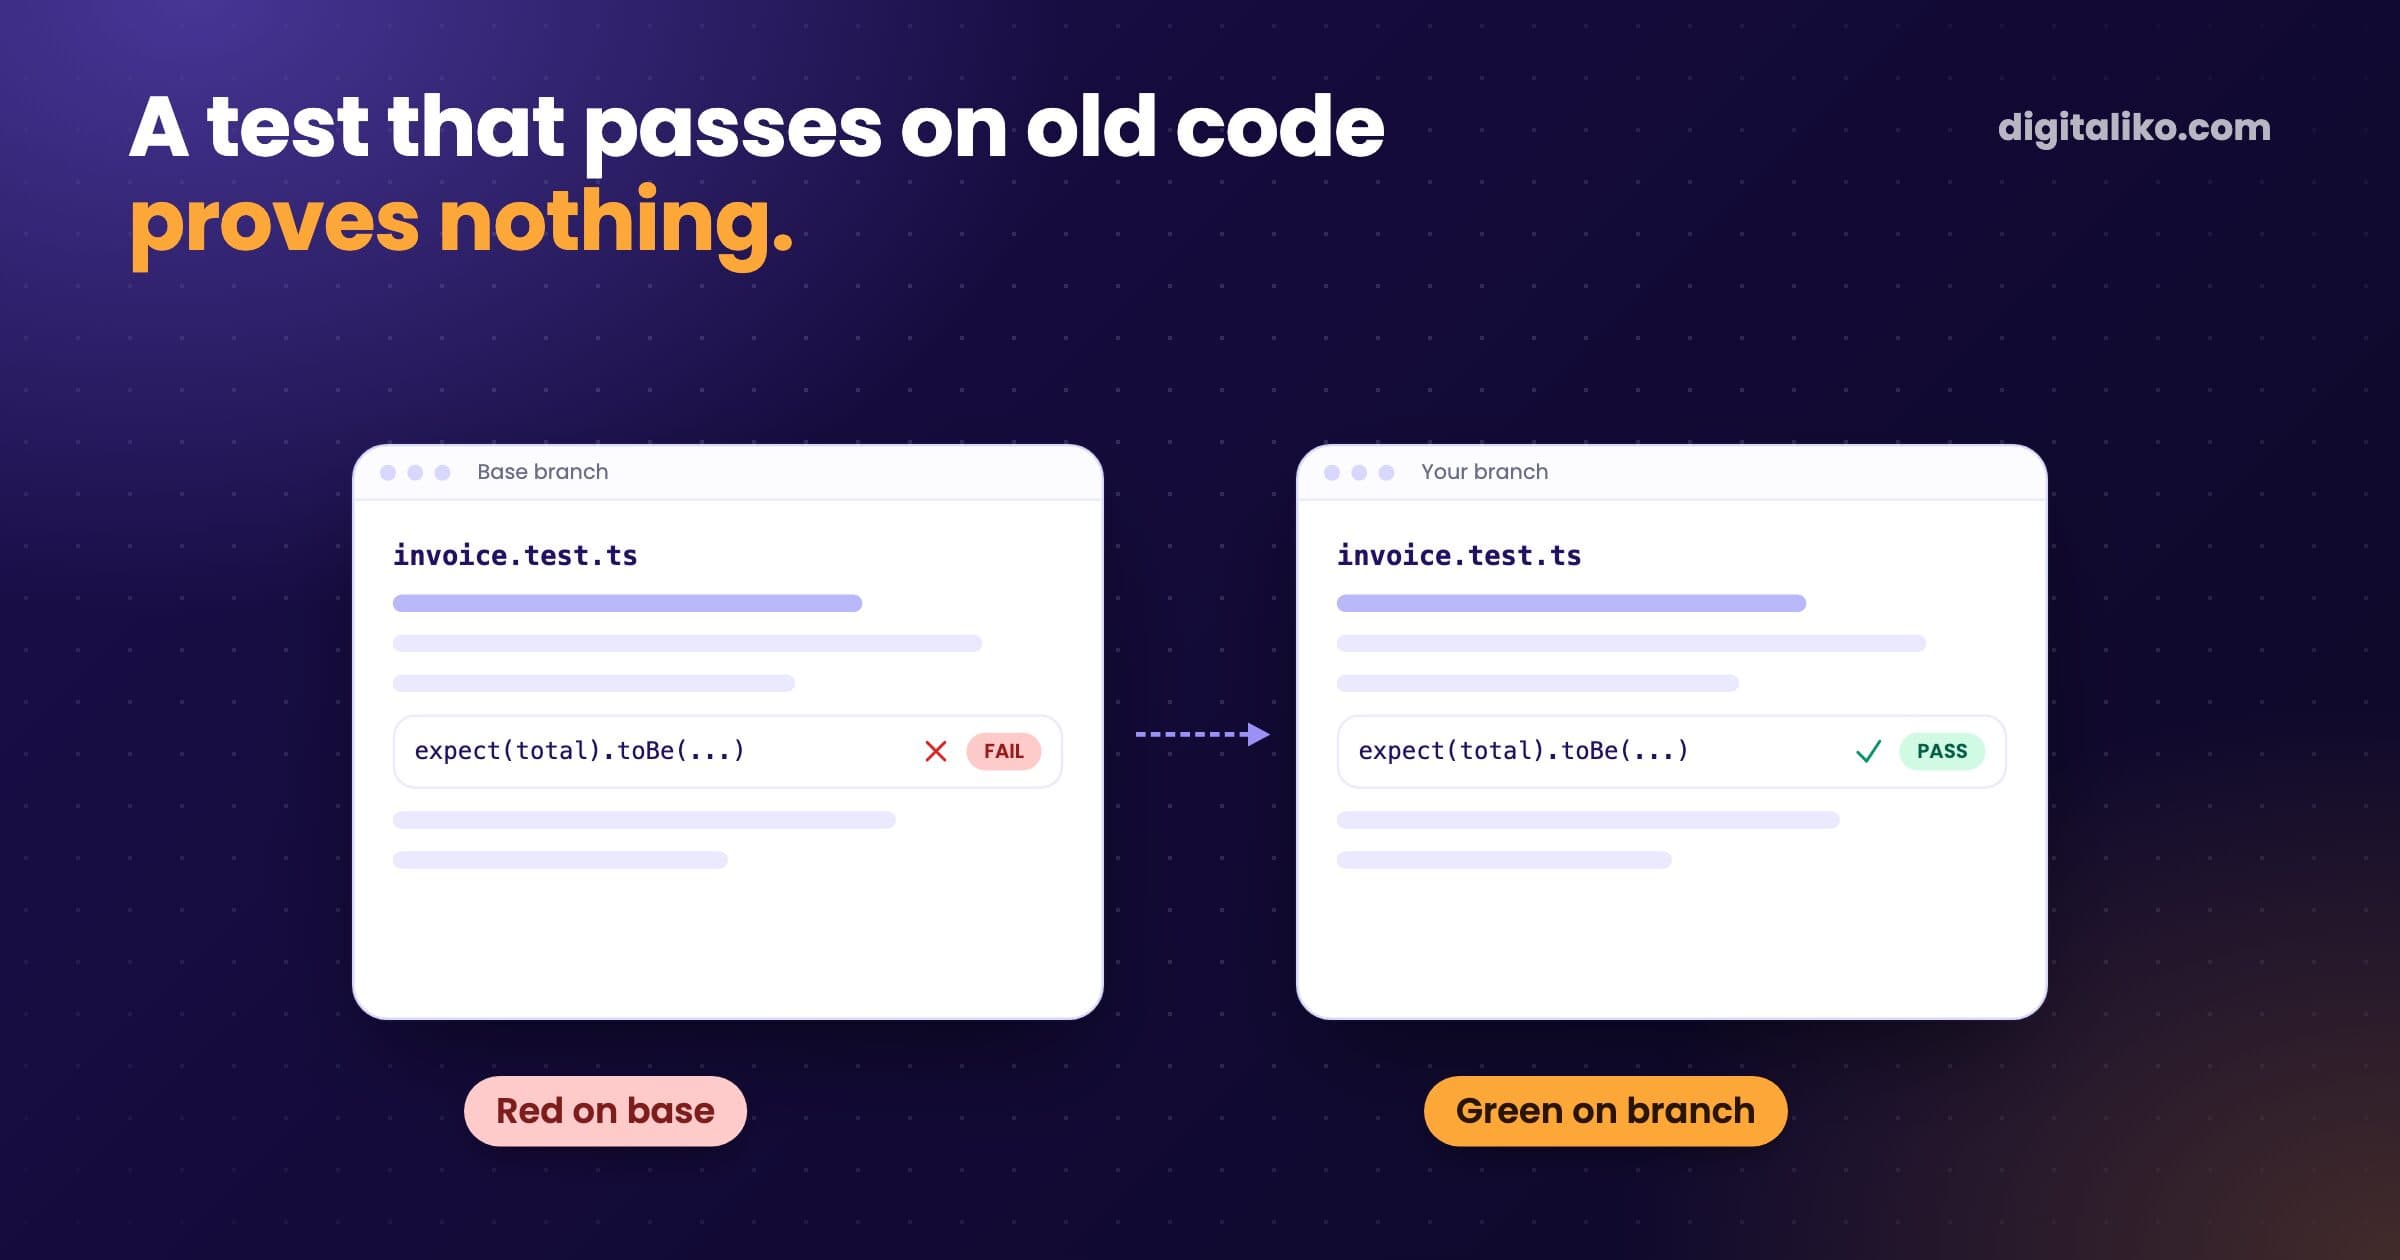
AI agents write tests that pass, not tests that prove anything. Our gate runs every new test against the base branch first: if it passes there too, the PR is red. The script, how to add it to CI, and the bug that gave a false pass.

Harness and checks

Spec-driven development with AI agents: our issue contract

Spec-driven development with AI agents: write down what to build and how you will know it is done before the agent writes code. Our lighter version: a GitHub issue with a task type and acceptance criteria, checked by a machine gate.

Harness and checks

Vibe coding vs agentic engineering: what's the difference?

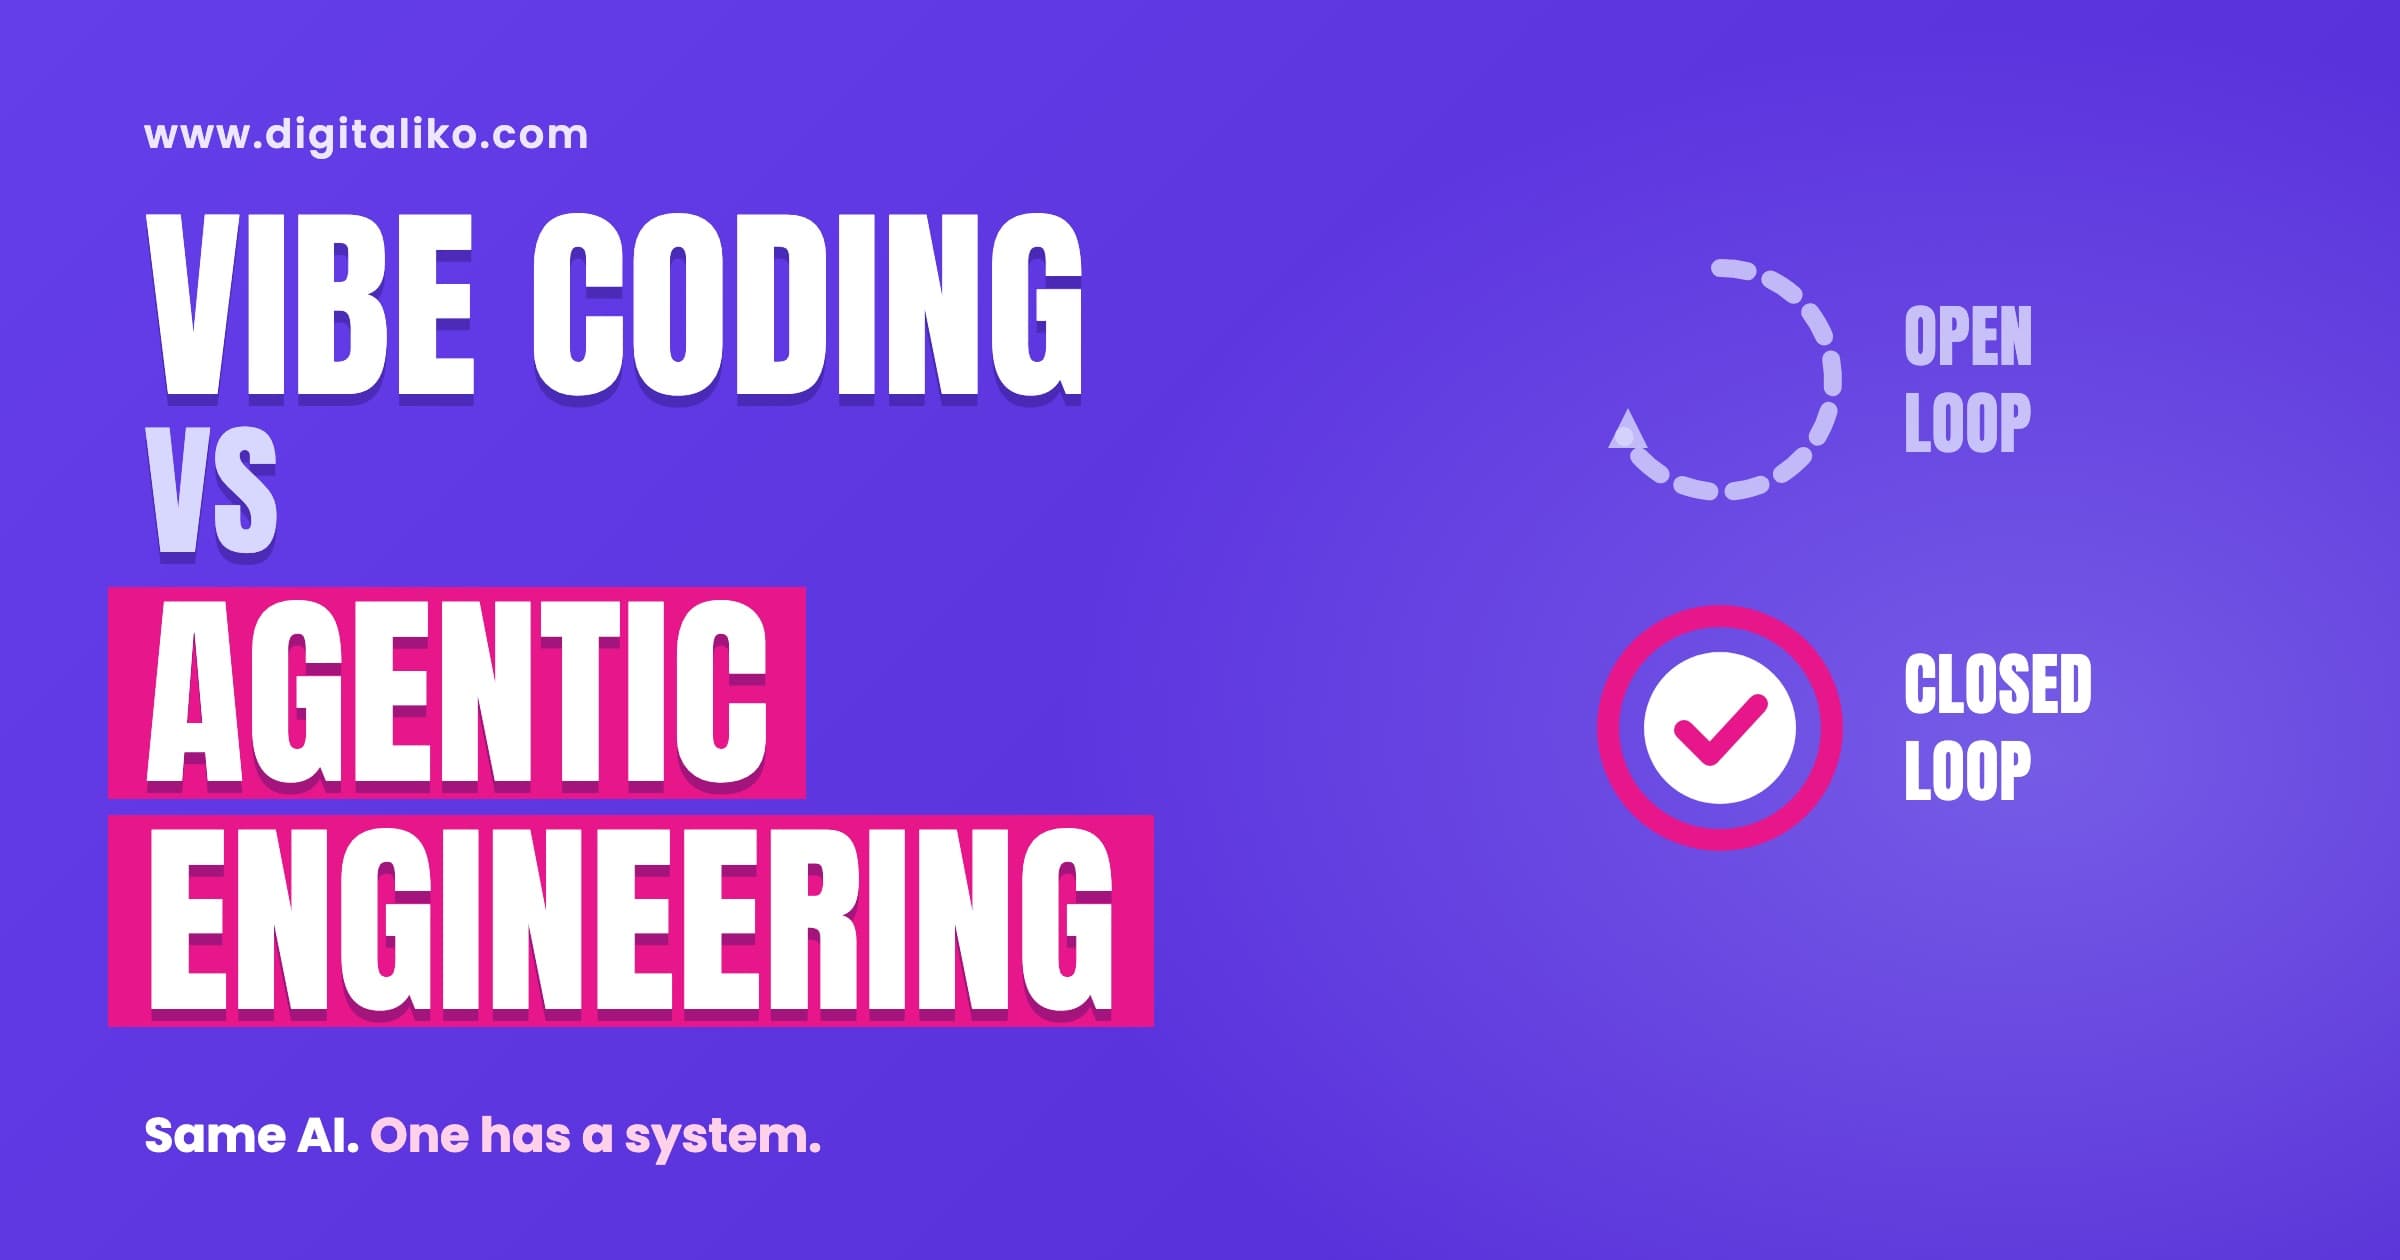
Vibe coding accepts AI output that looks finished. Agentic engineering puts the same AI inside a closed loop: a spec, tests, hooks, a review gate and a person who merges. What breaks without the system, and the code that closes the loop.

Web scraping and crawlers

Web scraping and crawlers

Playwright vs Puppeteer for testing and scraping

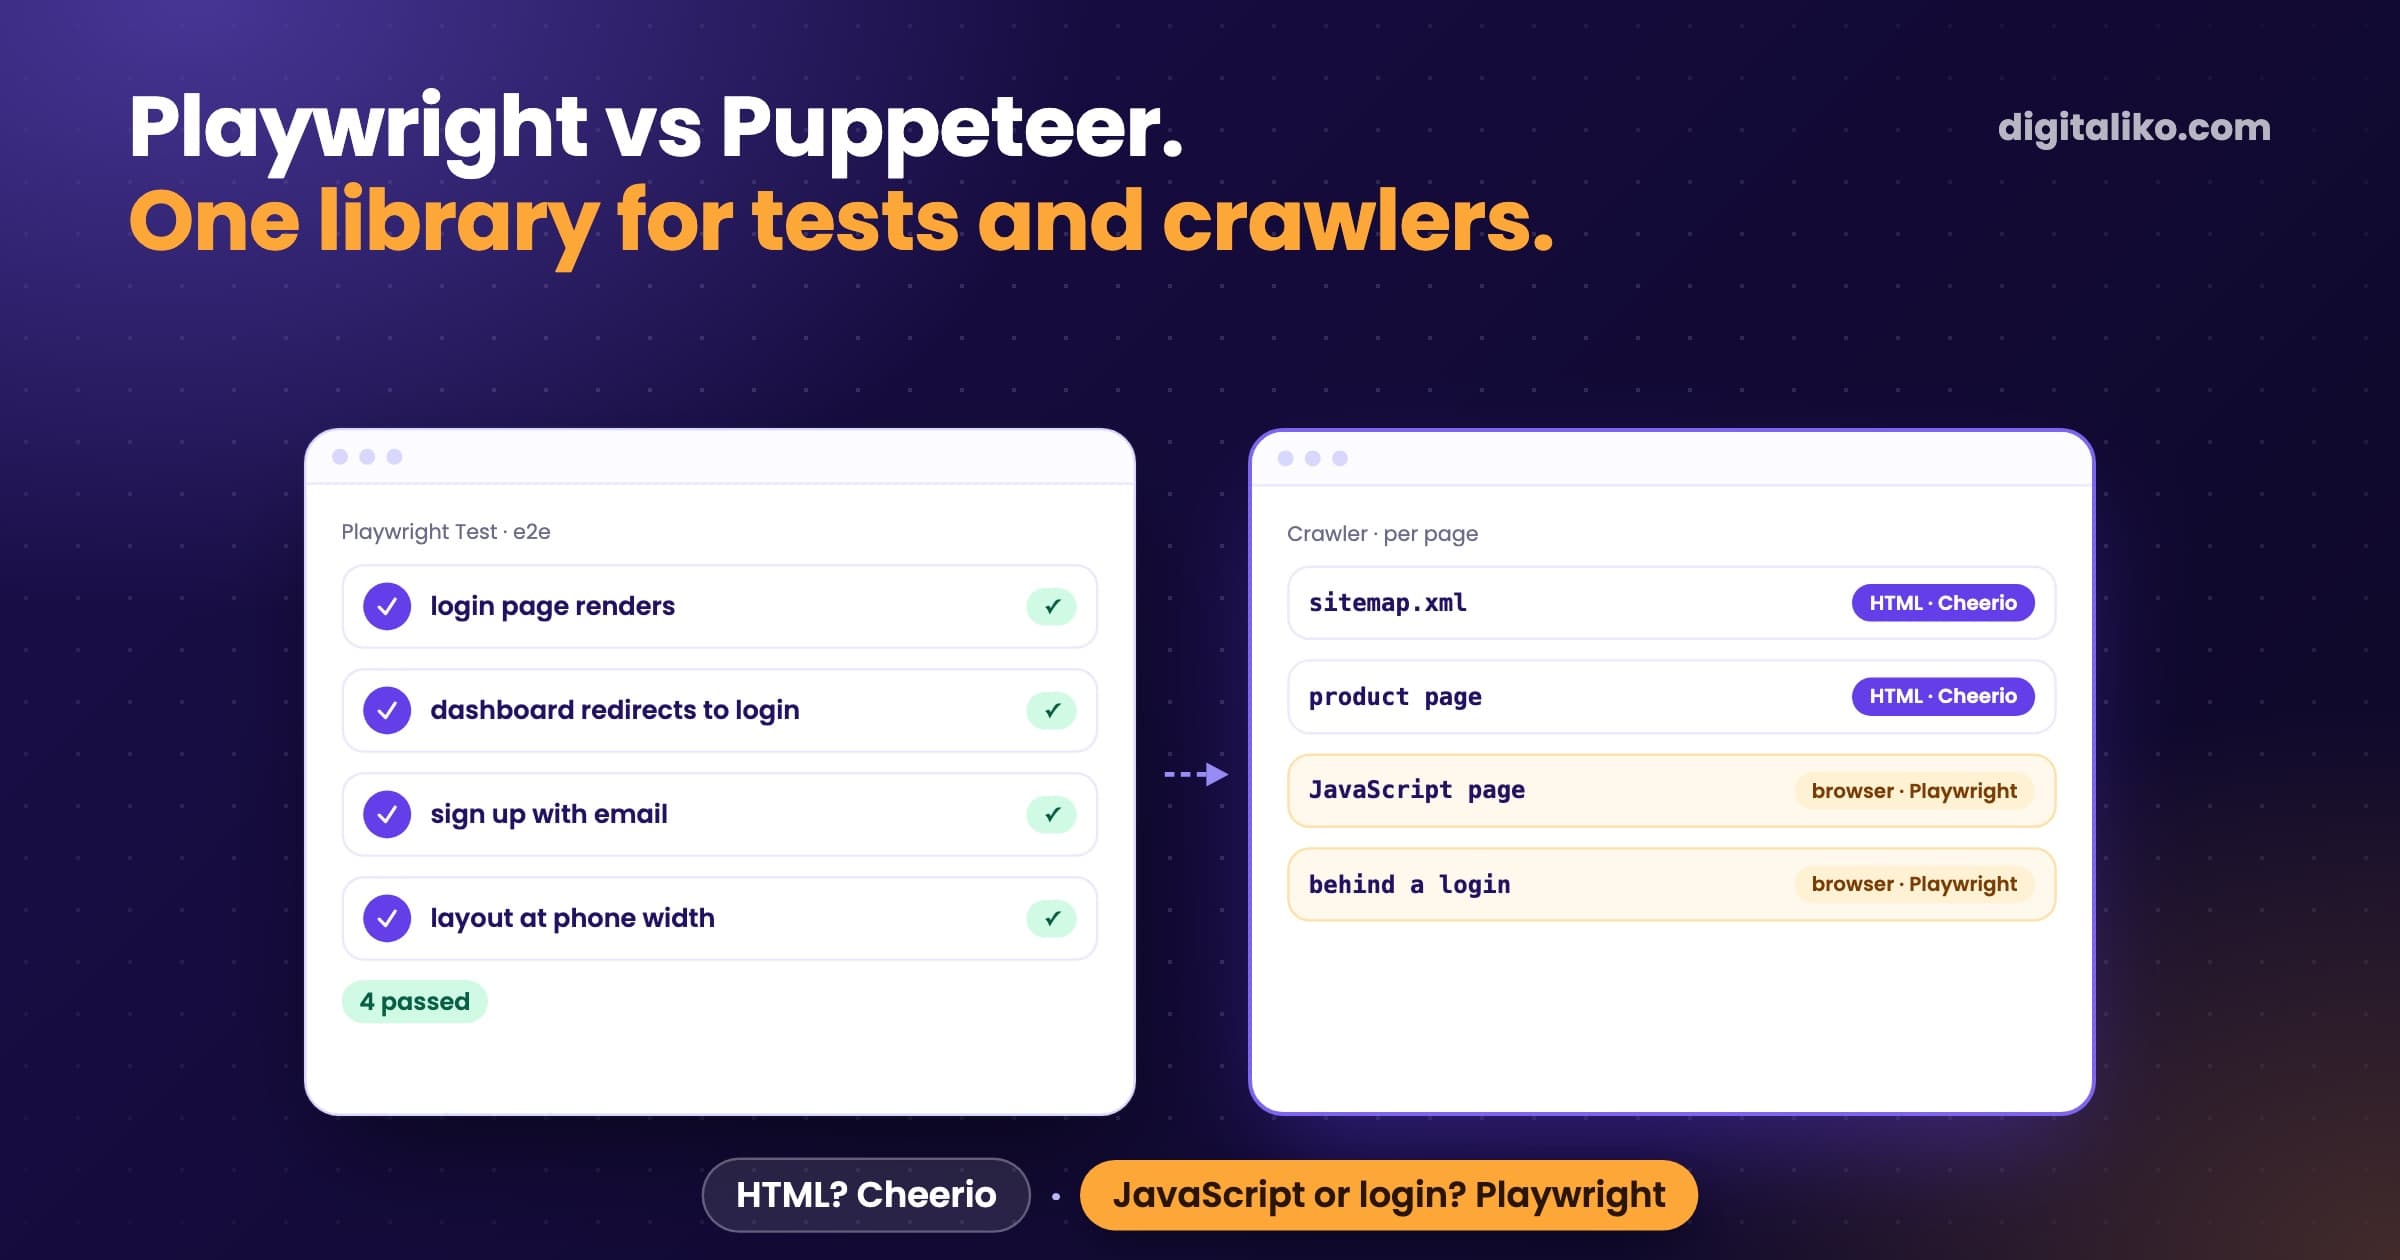
Playwright or Puppeteer? We run Playwright for end-to-end tests, website audits and production crawlers, and Cheerio where no browser is needed. What differs, how we decide per page, and where we have not tested Puppeteer.

Web scraping and crawlers

Crawlee for web scraping: what breaks in production

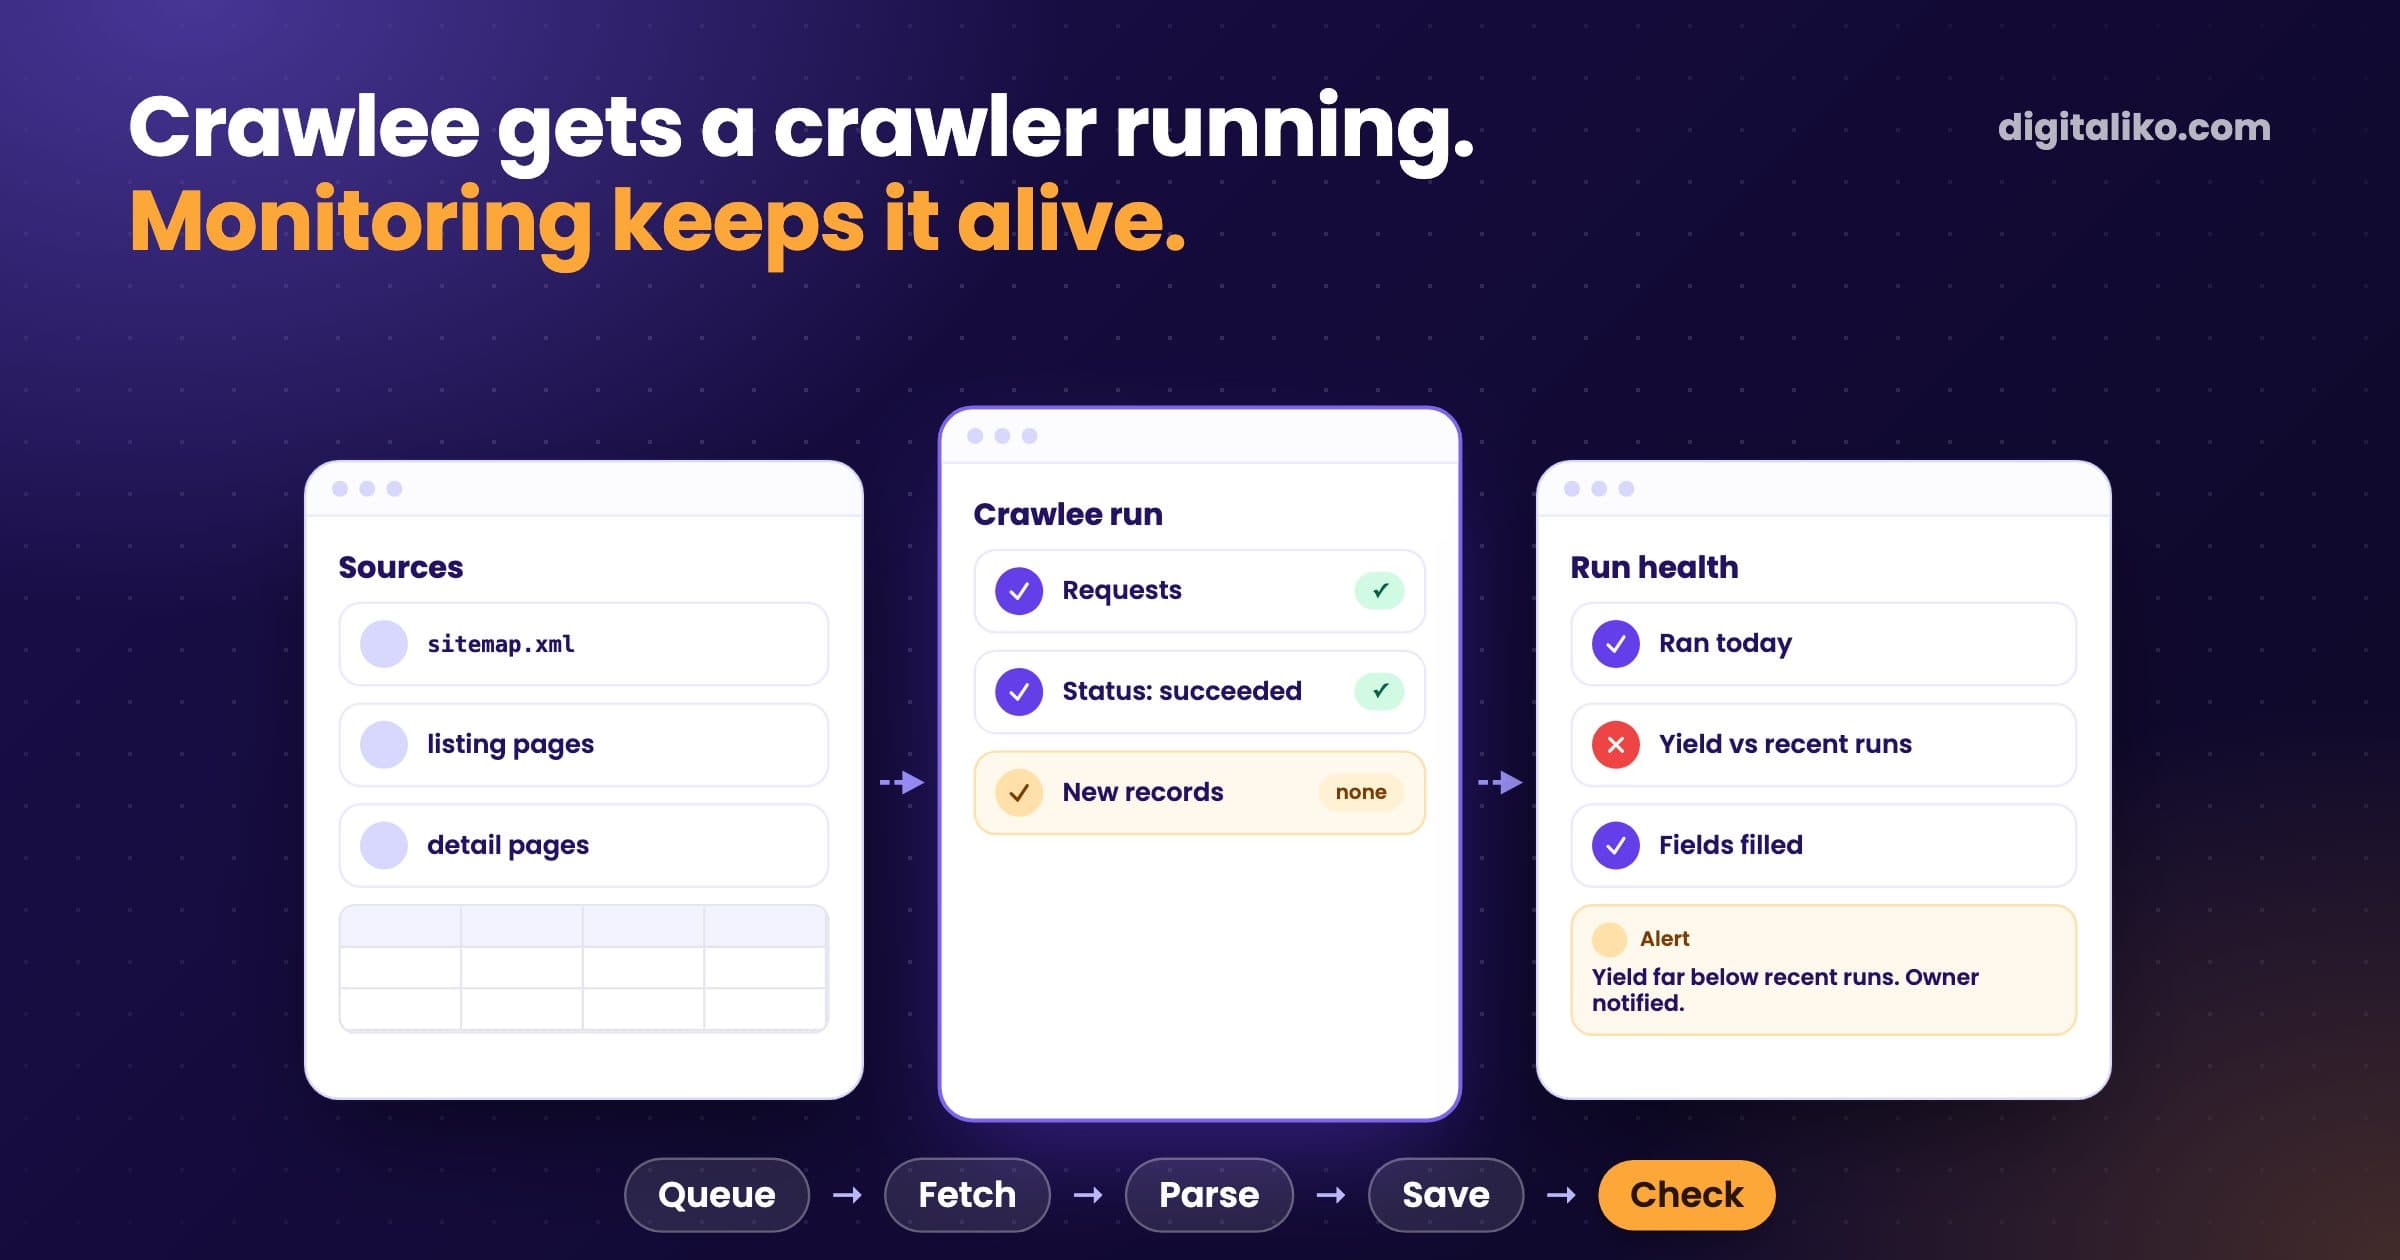
Crawlee is an open-source library for crawling and scraping with Cheerio, Playwright or Puppeteer. How we run it in production, what broke, and the checks that catch a crawler that dies without an error.

CTO decisions

CTO decisions

Claude Code pricing for a team: plans, API and agents

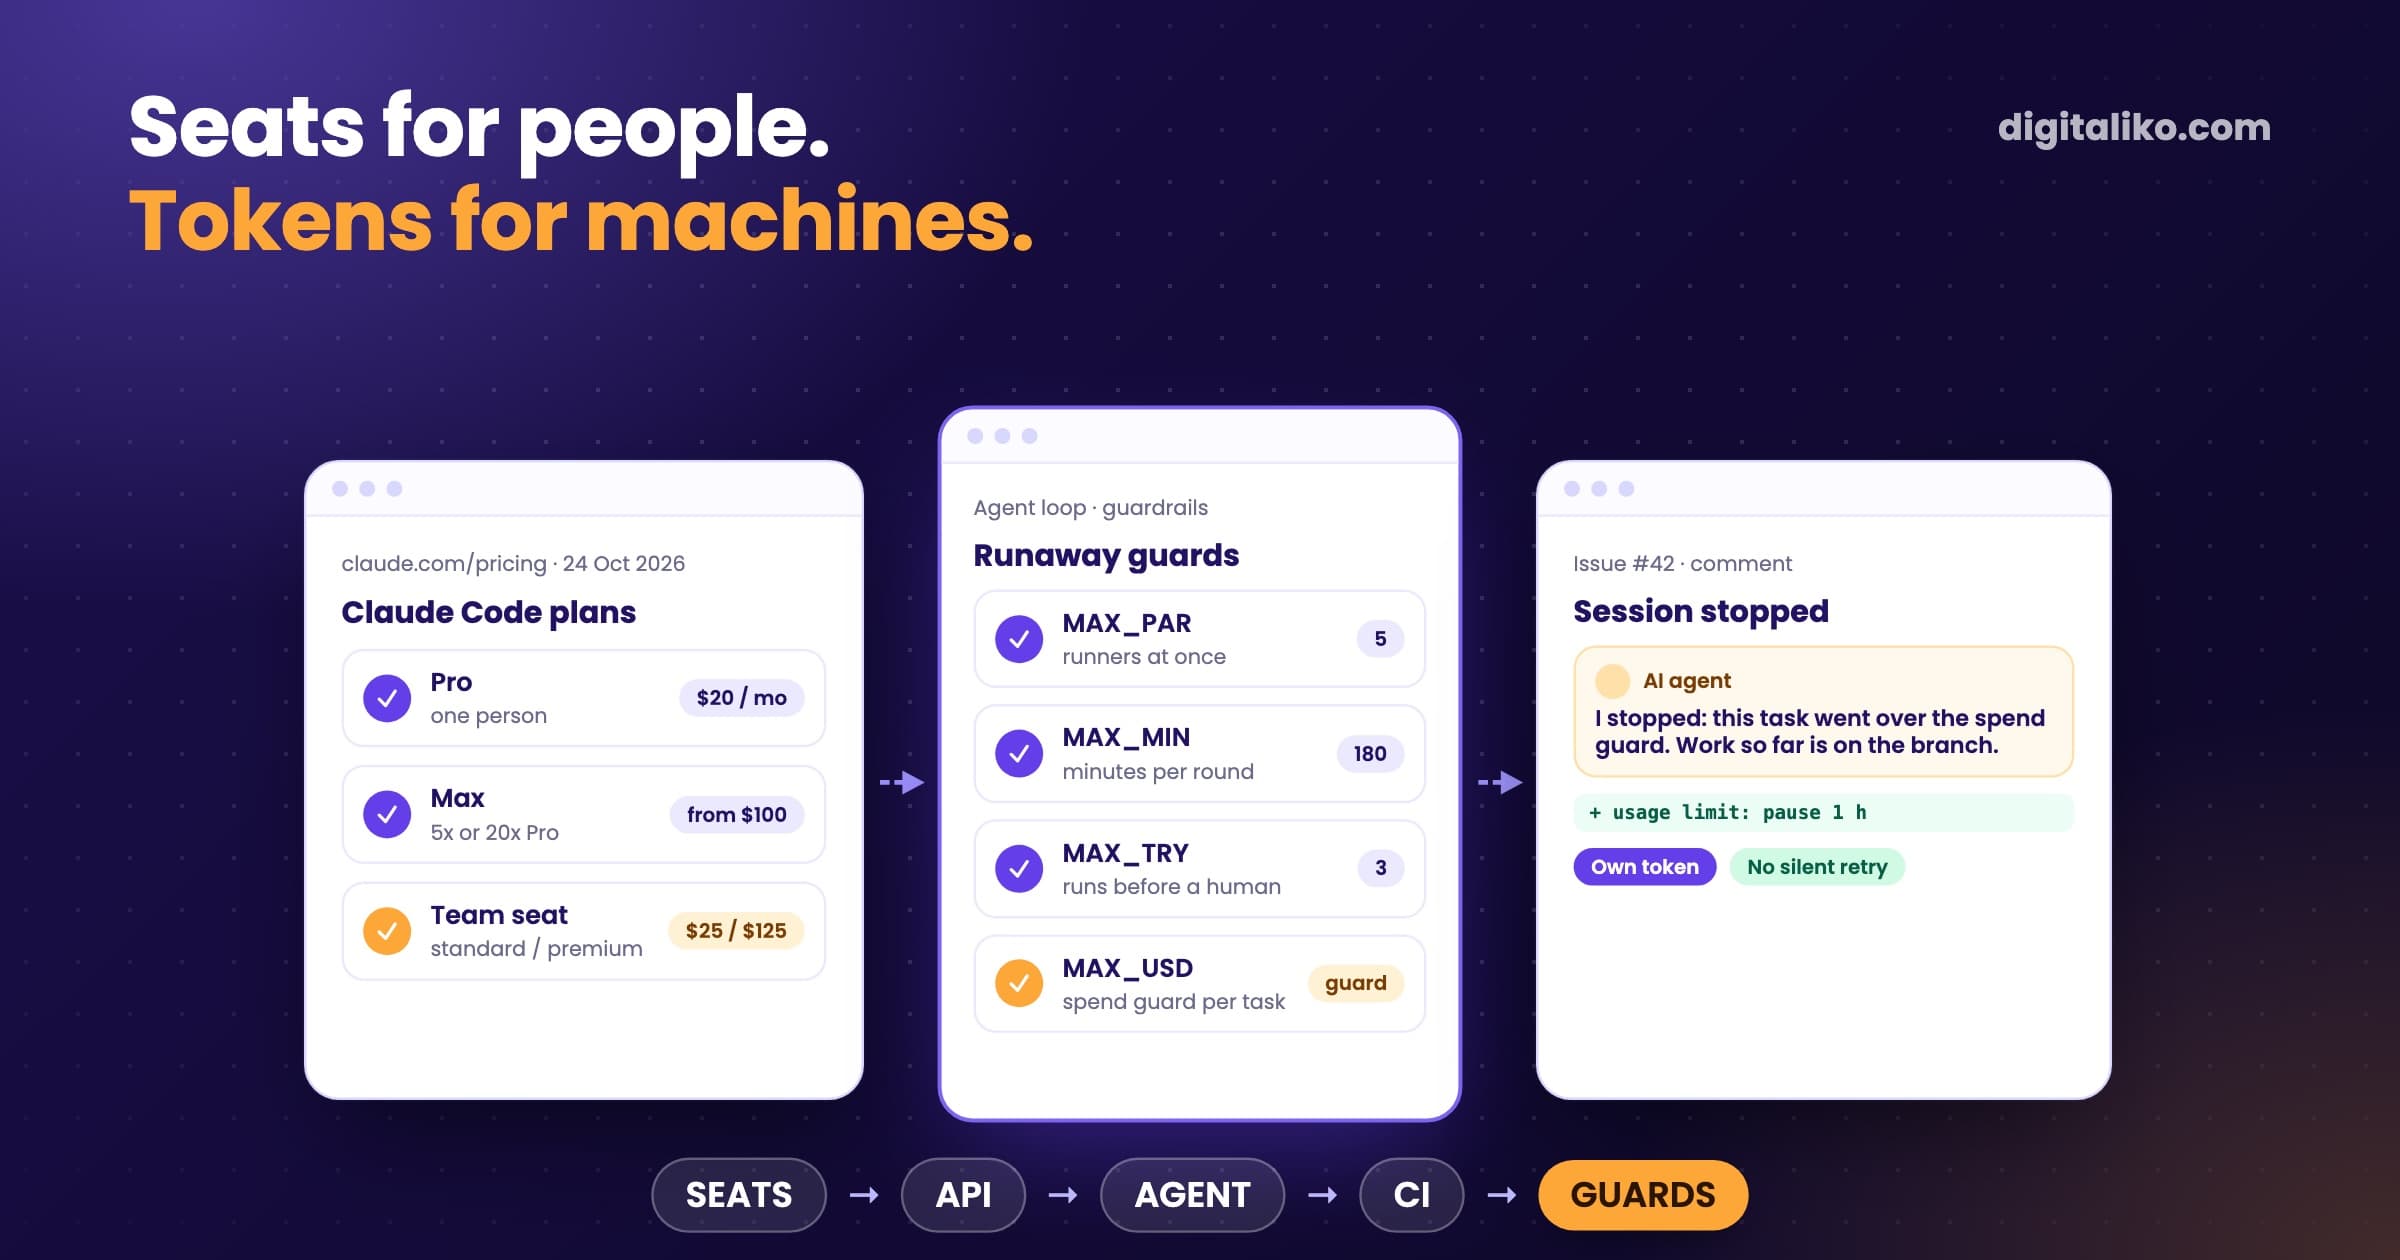
Claude Code pricing from Anthropic's public list (October 2026): Pro, Max, Team seats, Enterprise and API tokens. Which one fits developers, which one an always-on agent and a CI reviewer run on, and the guardrails that stop a background agent from burning the budget.

CTO decisions

Vercel alternatives: why we run Vercel and Cloudflare

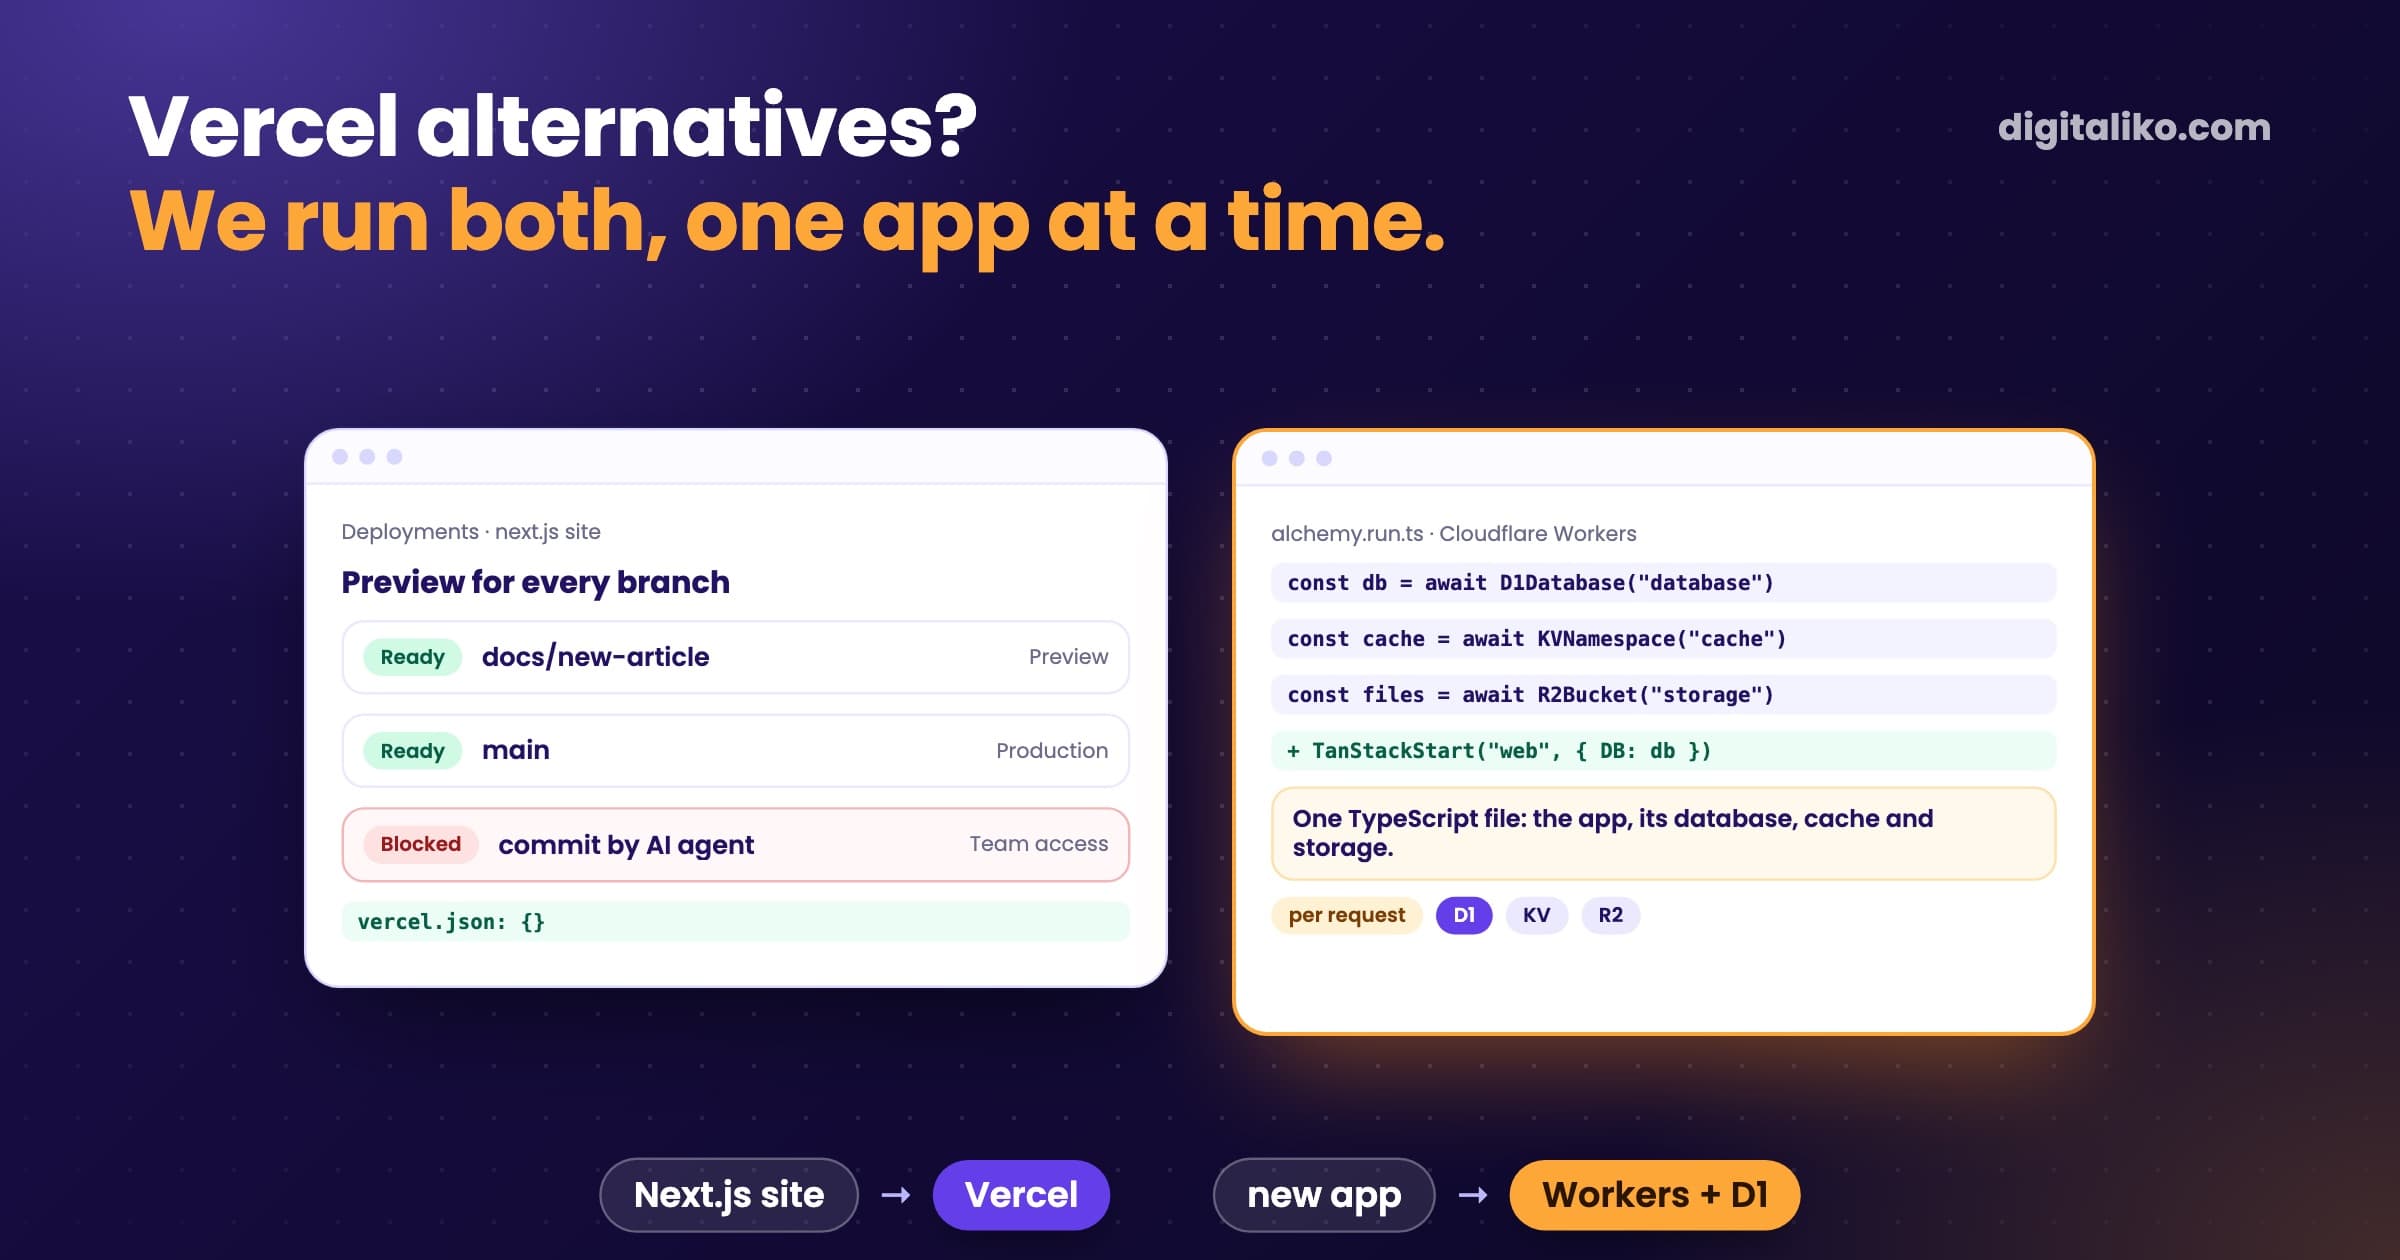
We did not replace Vercel, we split the work. Next.js sites stay on Vercel, new apps run on Cloudflare Workers and D1, declared in TypeScript with Alchemy. Pricing with sources, our config, and the deploy block an AI agent hit on Vercel.

CTO decisions

Better Auth vs Clerk: why we chose Better Auth

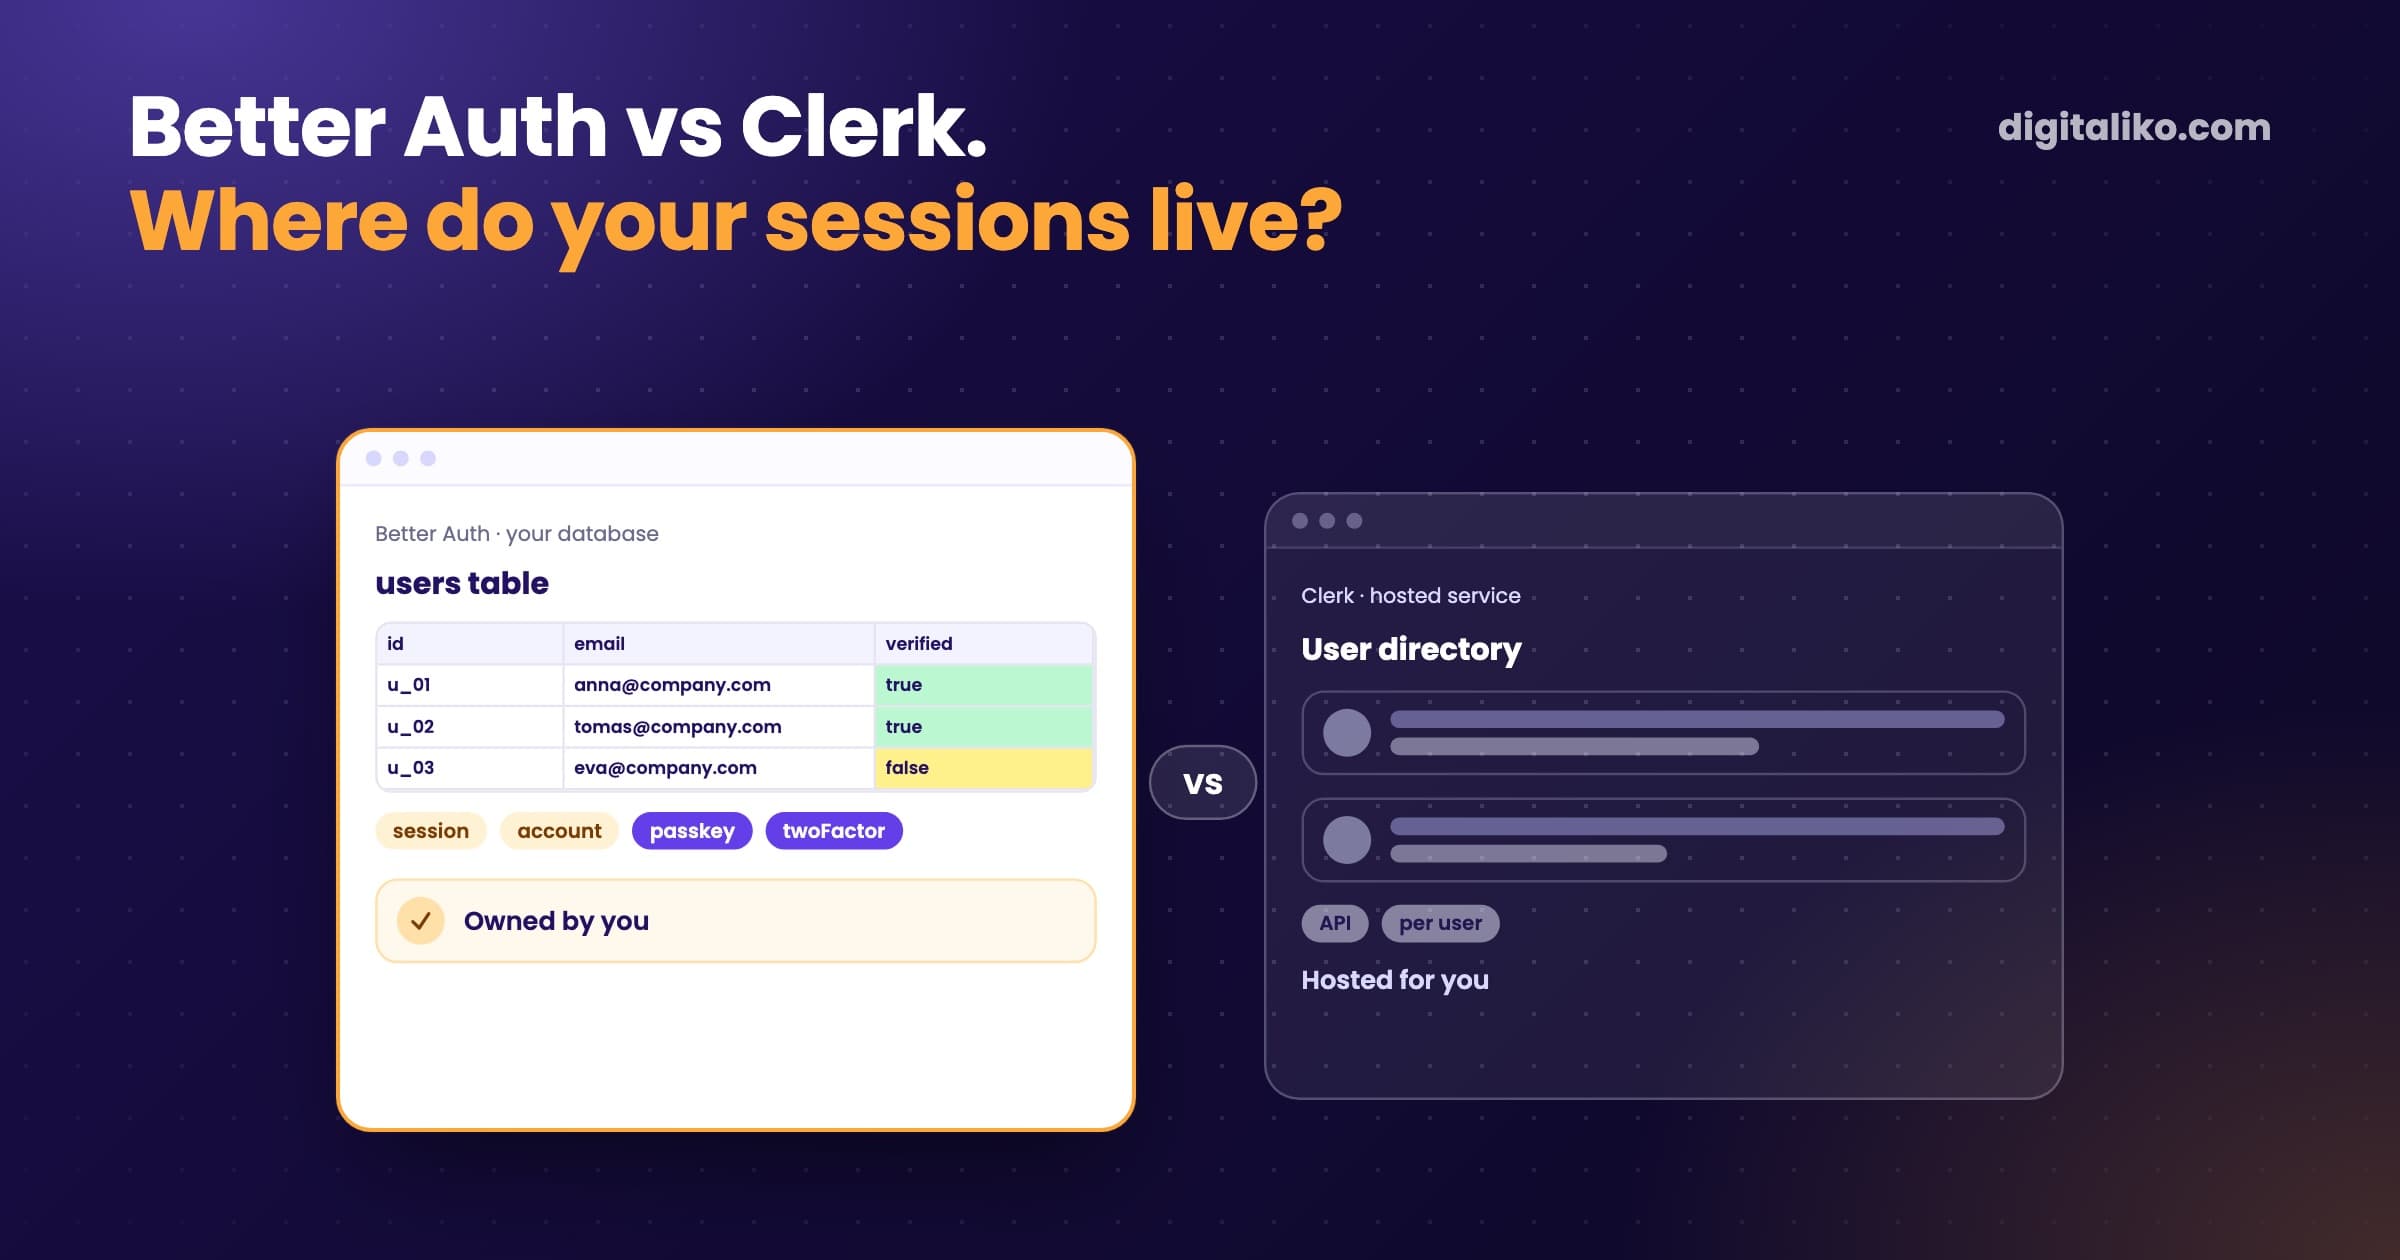
Better Auth vs Clerk comes down to where your users and sessions live. We moved from NextAuth to Better Auth in every new app and never picked Clerk. Our real config, the plugins we run, Clerk pricing and when Clerk is the better call.

CTO decisions

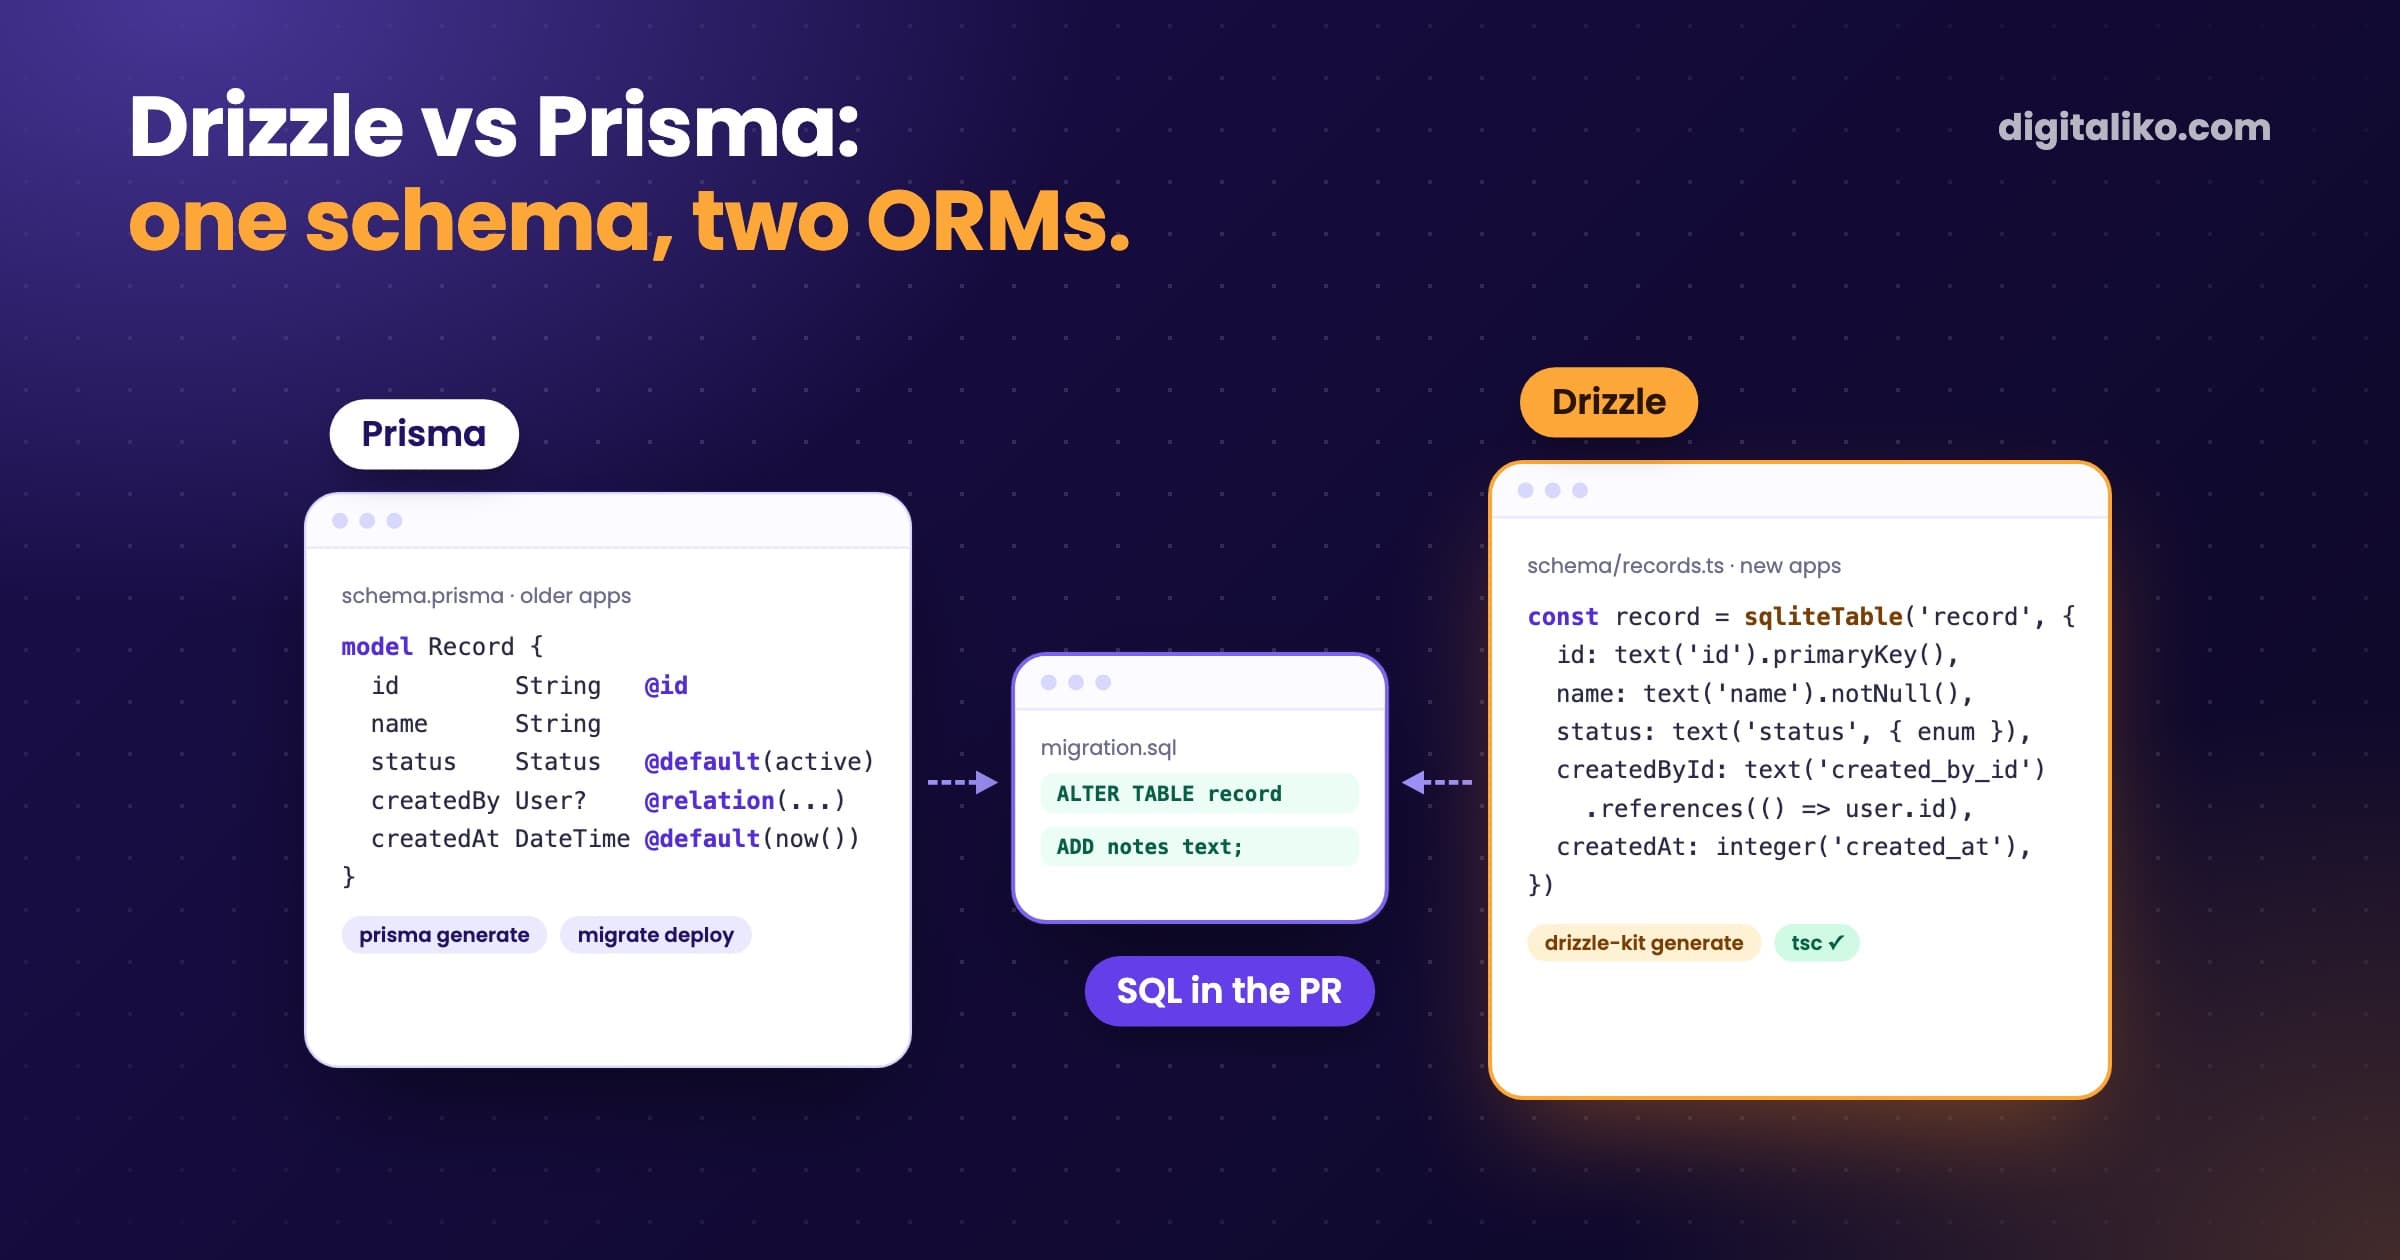
Drizzle vs Prisma: why we run both in production

Drizzle vs Prisma from two ORMs we run in production: Prisma on Postgres in older client apps, Drizzle on Cloudflare D1 in everything new. Real config, the migration flow, what Prisma 7 changed and when we would not switch.

CTO decisions

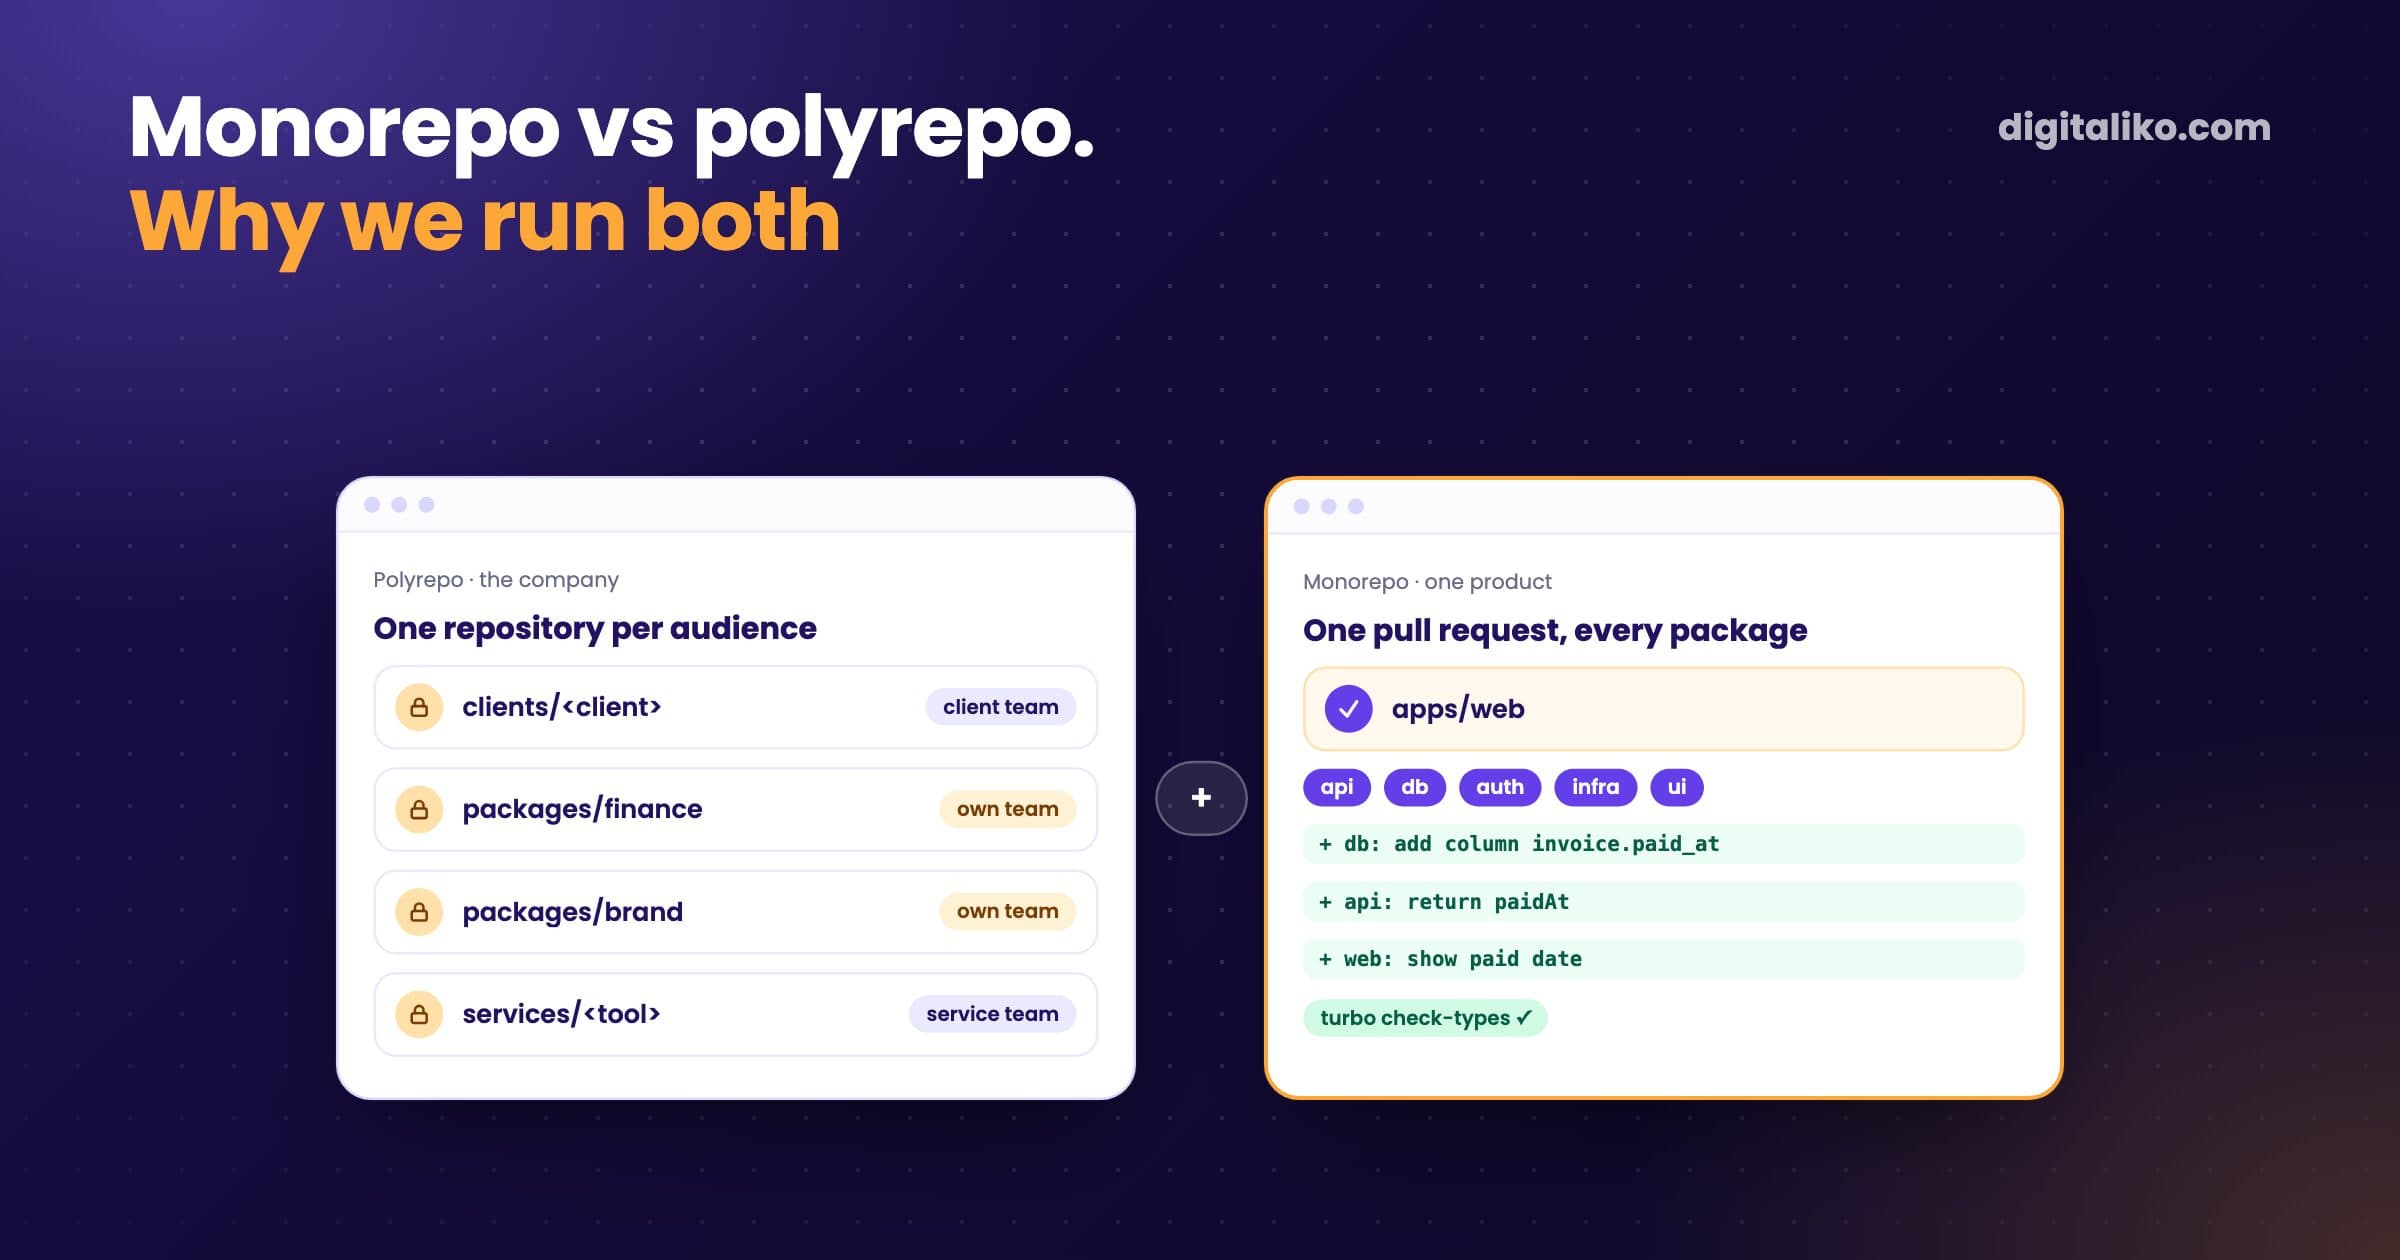
Monorepo vs polyrepo: why we run both

Monorepo vs polyrepo is not a matter of taste. A monorepo draws a code boundary, a polyrepo draws an access boundary. We run every product as a Turborepo monorepo and the company as a polyrepo of git submodules, and an AI agent works in both. Our configs, the trade-offs and how to decide.

CTO decisions

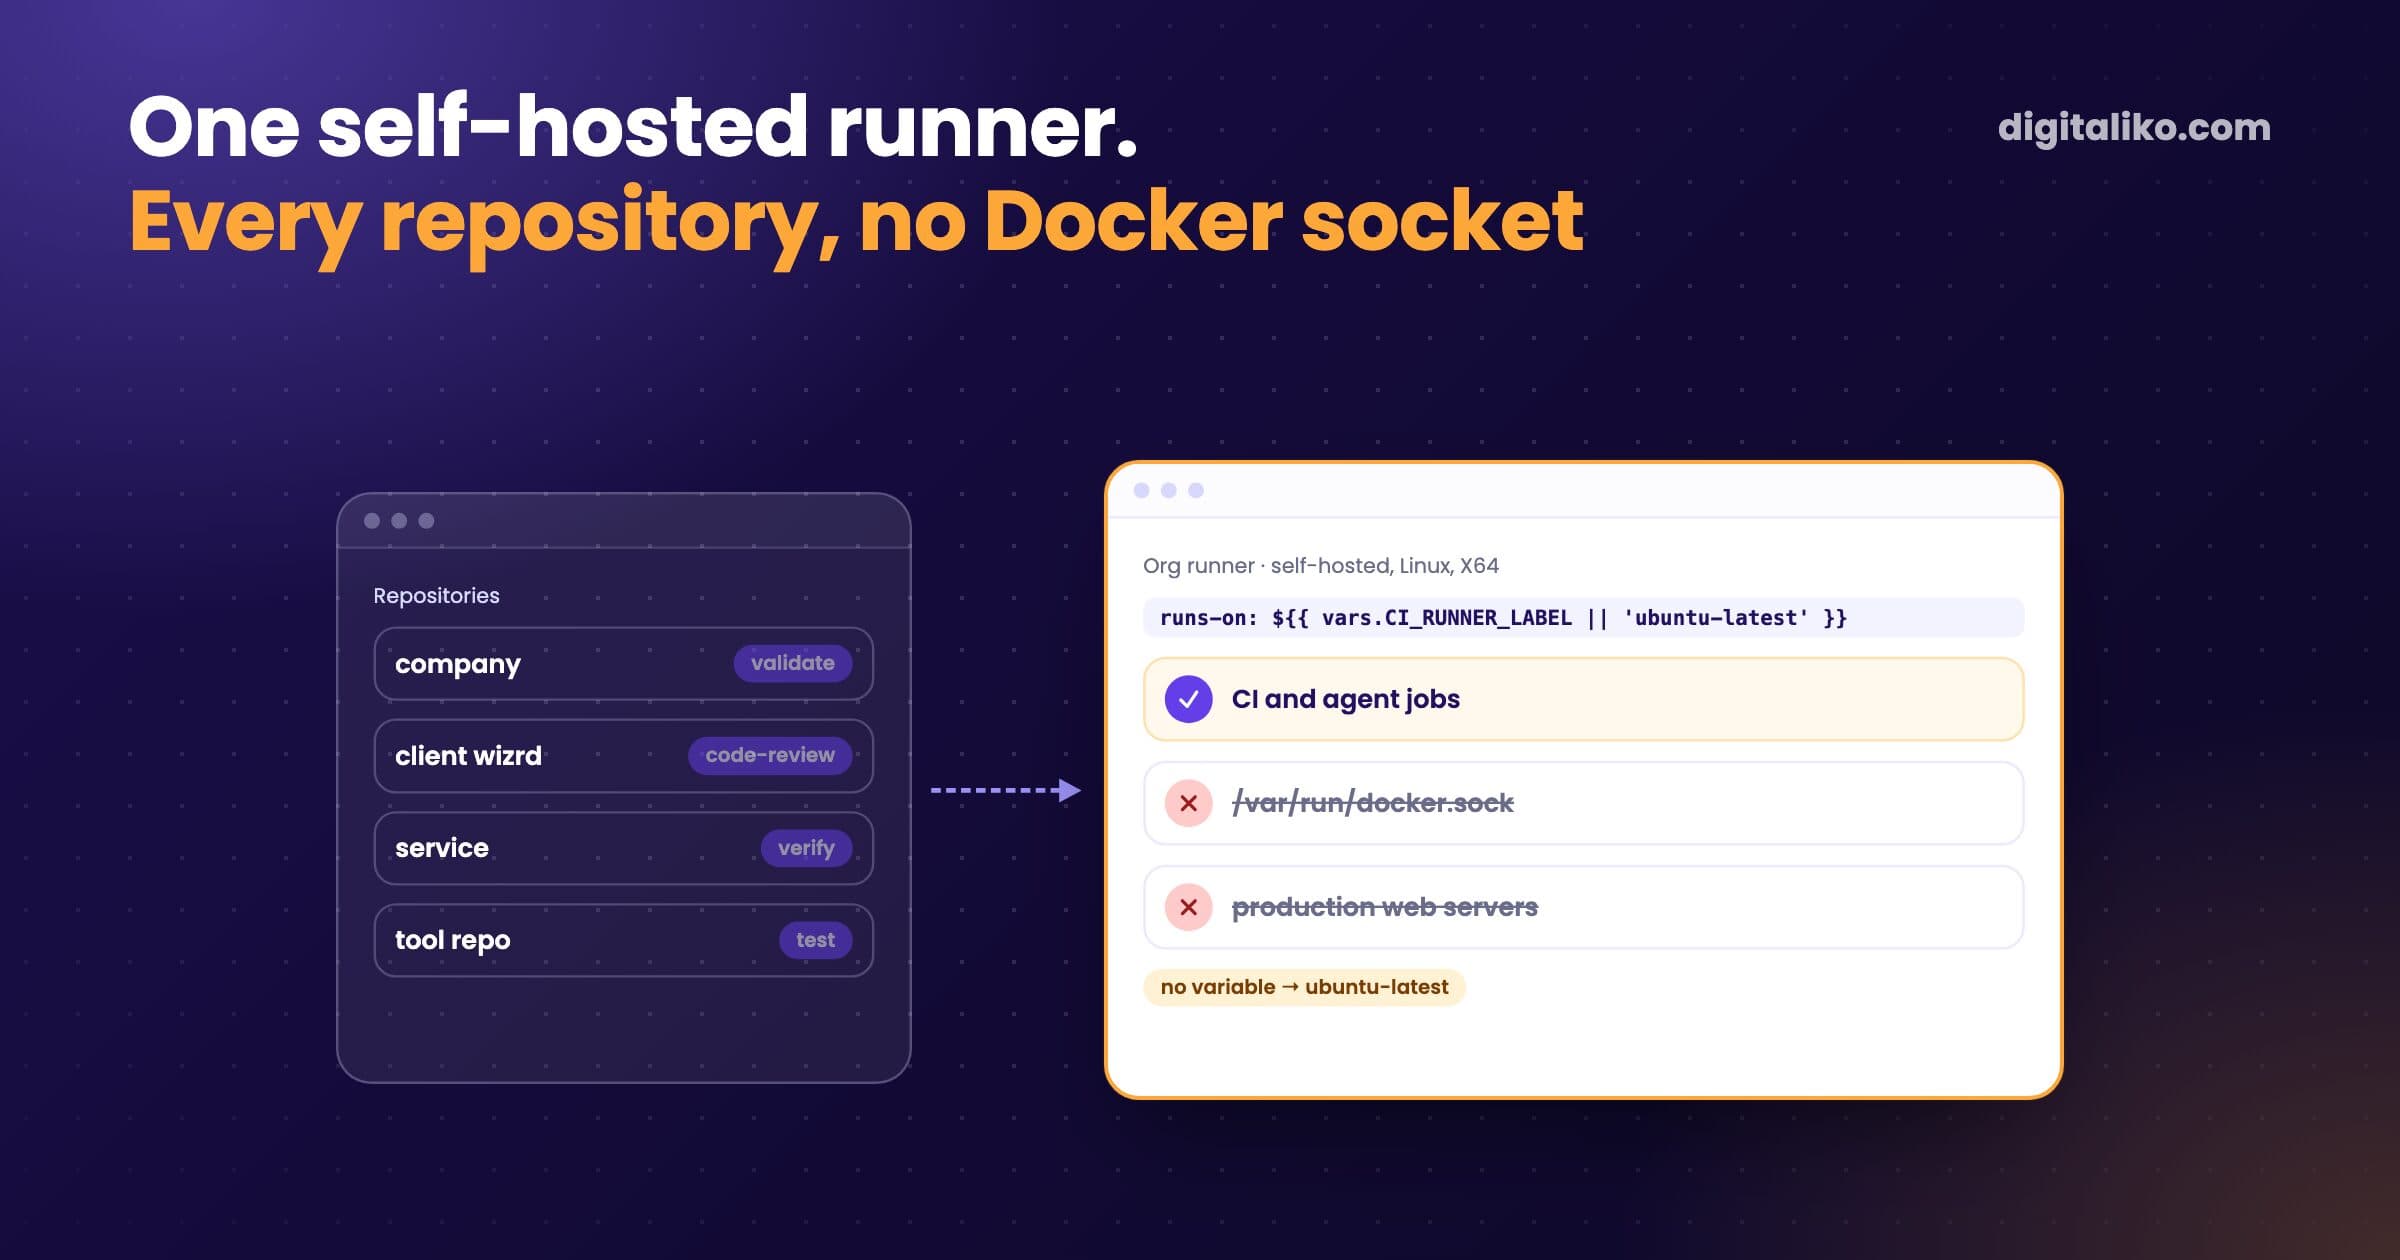
GitHub Actions self-hosted runner for the whole org

A GitHub Actions self-hosted runner is your own machine that picks up CI jobs. We run one at organization scope for every repository, pick it with one org variable that falls back to hosted runners, took the Docker socket away on purpose, and keep client-owned repositories off it. The config and the reasons.

CTO decisions

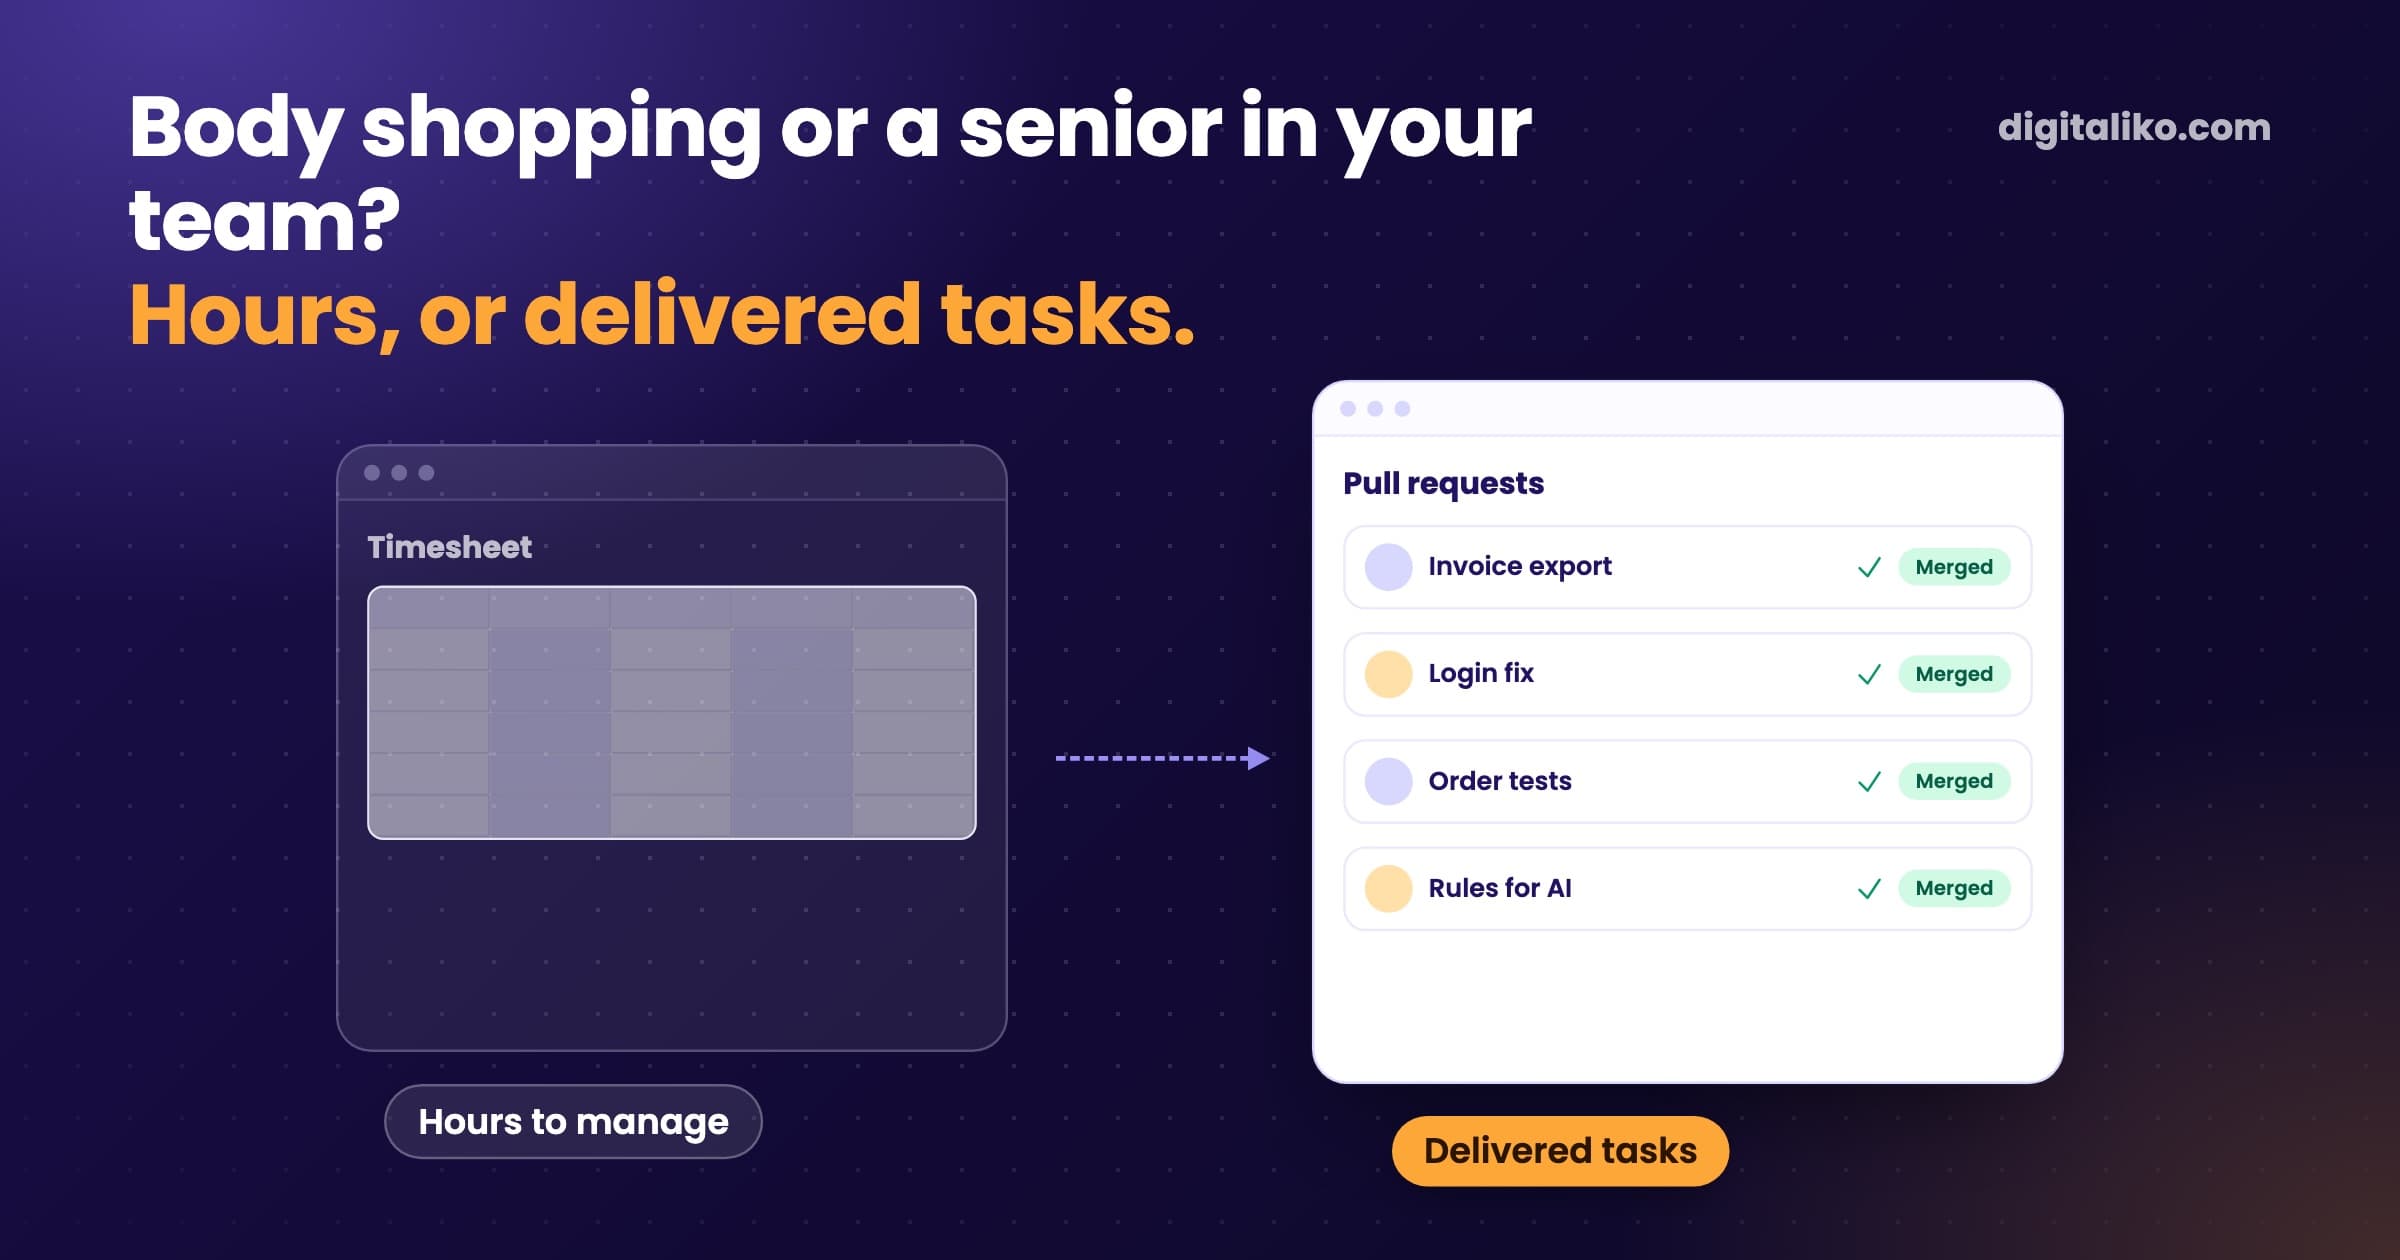
Body shopping or a senior developer in your team?

Body shopping gives you developer hours you manage yourself. A senior in your team gives you delivered tasks and a team that learns to work with AI. Compared with outsourcing and hiring, for CTOs.

CTO decisions

Refactor or rewrite from scratch? How to decide

Refactor when the code does the right thing badly. Rewrite when it does the wrong thing or you do not own it. A decision table for CTOs and a way to do it without stopping the roadmap.

Time to stop planning and start solving.

Contact

  • Digitaliko s.r.o.
    Šípková 377/17
    958 03 Malé Uherce, Slovakia
  • Get in touch
    info@digitaliko.com
    +421 950 595 506
    WhatsApp